Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
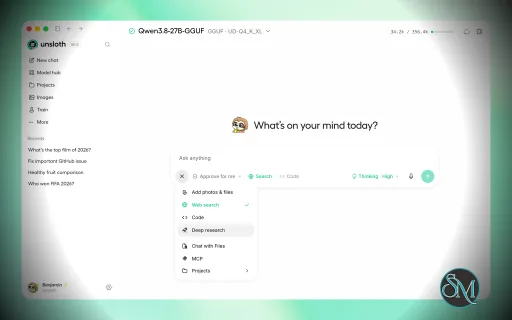
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.913-beta - Software Mirrors |
|---|
Unsloth v0.1.913-beta for WindowsUnsloth-Desktop-Windows.exe | 21.8 MB Unsloth-Desktop-Windows-ARM64.exe | 21.19 MB |
Unsloth v0.1.913-beta for macOSUnsloth-Desktop-MacOS.dmg | 22.29 MB |
Unsloth v0.1.913-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 23.67 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 23.42 MB Unsloth-Desktop-Linux.AppImage | 170.71 MB |
Others Download related to Unsloth v0.1.913-betaUnsloth-Desktop-ARM64.app.tar.gz | 22.08 MB |
Unsloth v0.1.913-beta Source Code
Unsloth v0.1.913-beta Source code (zip)
Unsloth v0.1.913-beta Source code (tar.gz)
|
Unsloth v0.1.913-beta Release Notes: Make Unsloth your own with custom backgrounds and a improved UI/UX. This release also cuts app update times and speeds up Linux app and Qwen-Image gen when VRAM is limited. Also new: DeepSeek-V4.1-Flash-1017 in Unsloth Dynamic v3.1 GGUFs (preview), FLUX.2-klein-9B on low-RAM machines, smoother chats and batched MoE fine-tuning.

Highlights
- Custom backgrounds to personalize your chats (+ move composer to bottom - more customization coming next week)
- DeepSeek-V4.1-Flash-1017 new Unsloth Dynamic v3.1 GGUFs (preview), the most accurate for their size on nearly all benchmarks Blog
- 14 new languages for Unsloth
- App updates finish twice as fast
- Linux much less lag and improved performance
- Qwen-Image renders up to 2x faster under a 16 GB VRAM limit
- Updated interface with consistency and cleaner UI
- MoE fine-tuning runs compatible API jobs together
Customization and interface
- Move the chat box to the bottom of new chats with Composer at the bottom in Settings > Chat.
- Hide the greeting entirely for a simpler new-chat screen.
- The Library gets shorter chat cards, clearer tooltips and consistent sort and filter icons.
- Copy images between input slots by dragging a filled slot onto an empty one.
- Pinned models stay saved across Unsloth Desktop restarts.
- Each browser tab keeps its own unsent message.
- Scrolling long chats is smoother on Linux with NVIDIA, X11 and driver 610+. Our high-resolution test improved from about 17 to 60 fps.
Images and video
- FLUX.2-klein-9B now loads and renders on Linux with 12.7 GB of system RAM and a supported GPU.
- Qwen-Image-2512 renders up to 2x faster under a 16 GB VRAM limit.
- Qwen-Image-Edit-2511 renders about 1.3x faster under the same limit.
- MiniMax-H3 clips finish about 1.7x faster in our memory-limited NVIDIA test.
Performance
- App updates take about half as long by skipping Python precompilation. The tradeoff is a longer first launch afterwards, as before v0.1.912.
- Long replies stream more smoothly, even with unfinished math formatting. Parsing an 83 KB reply with a stray
$$ took 0.7 seconds instead of 71 seconds.
- Previewing a 1 GB local Parquet file uses about 300 MB of peak memory, down from 1.5 GB.
- Unsloth stays responsive as Transformers and MLX models finish loading.
Chat and API
- GGUF models reload in the background after a llama-server crash.
- Failed or cancelled GGUF downloads leave your current model loaded.
- Very long GGUF chats can compact and keep going.
- Claude Code connected directly to a local GGUF reuses cached prompts across new sessions.
- Rejected GGUF requests show llama-server’s explanation instead of a generic error.
Mac
- Claude Code, Codex and OpenCode requests can share an MLX batch. In our test, four simultaneous requests finished up to 2.3x faster.
- Experimental Neural Engine Prefill processes prompts up to 31% faster in our Qwen3.8-27B-4bit test on M3 Max. It is opt-in and can slightly change replies.
- Auto context starts GGUF models at no more than 65,536 tokens, reducing upfront memory use. You can still set a larger context manually.
- Send LFM3-Audio or LFM3-Omni a voice clip on MLX and hear its answer alongside the text.
Training
- Compatible LoRA and QLoRA jobs on MoE models such as Qwen3.6-35B-A3B train together through the fine-tuning API, each with its own adapter.
- Use via API on the Train page opens Python, JavaScript and curl examples for your setup.
- Single-column text datasets are recognised automatically, with no manual column mapping.
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.10.10, unsloth-zoo>=2026.10.10 by @danielhanchen in #15785
- Tensor parallel x FSDP2: average trainable TP parameters left out of FSDP2 over the data parallel ranks by @danielhanchen in #15748
- Flash impl: warn about an explicit fa3 / fa4 fallback on the Trainer path too by @danielhanchen in #15750
- FSDP2 block CUDA graphs: free the gathered weights of flex BlockMask blocks by @danielhanchen in #15756
- Installer downloads: report progress on whole 1 MiB chunks again by @danielhanchen in #15789
- Studio export: skip the GPU cache clear when nothing was loaded since the last one by @danielhanchen in #15737
- Studio video: read an LTX-2 checkpoint header once per file when probing for 2.3 by @danielhanchen in #15738
- Tensor parallel: batch_rebalance and group_by_length samplers give tp peers the same rows by @danielhanchen in #15752
- CI: hold the unpinned version-compat lanes below torch 2.15 until torchvision 0.30 is published by @danielhanchen in #15774
- Studio: give each batched fine-tuning job its own fp16 loss scale by @danielhanchen in #15741
- Studio: list a Qwen-Image-2.1-Turbo base pipeline cached in its FP8 mirror On Device by @danielhanchen in #15772
- Multi-LoRA: per-adapter LoRA on fused MoE experts by @danielhanchen in #15742
- Frontend tests: follow the desktop quit hiding the window by @danielhanchen in #15801
- Cross entropy: 8192-wide chunks at 4 warps for the chunked forward on sm120 by @danielhanchen in #15744
- Run packed rows of head-dim-routed flex decoders through varlen SDPA by @danielhanchen in #15514
- Tests: allow the zoo's padded logits row stride in the fused linear adapter check by @danielhanchen in #15803
- studiobench: seed the browser with update notifications off by @danielhanchen in #15805
- Flex small-smem tiles: keep float32 Gemma 3 off flex on sm86 / sm89, tile forced no-grad calls by @danielhanchen in #15529
- SDPA decode: keep the caller's backend policy when avoiding cuDNN by @danielhanchen in #15525
- MoE heuristic dW config: 128-wide N tile for gpt-oss K = 2880 by @danielhanchen in #15505
- FP8: skip the compiled wrapper for rowwise FP8 inference linears by @danielhanchen in #15584
- Studio: size FLUX.1 Kontext guard, preview and compile shape from its ~1 MP render by @danielhanchen in #15797
- Keep image and video models loaded beside chat models on Apple Silicon by @Lyxot in #15693
- Block CUDA graphs: turn on automatically for fixed-shape, launch-bound LoRA runs by @danielhanchen in #15768
- Studio: batch MoE fine-tuning jobs with per-job expert LoRA by @danielhanchen in #15809
- Studio: raise the startup bundle budget by the Trick or treat row's growth by @danielhanchen in #15822
- Studio: test that a batched fine-tune stays in its own account by @danielhanchen in #15825
- Studio: keep MiniMax-H3's streamed top-level group on the card between denoise steps by @danielhanchen in #15796
- Studio native cache write: recapture when an offload moves weights before the live-read swap by @danielhanchen in #15776
- checkpoint_skip_layers="auto": skip the planning collective under DDP.join() by @danielhanchen in #15779
- FP8 scaled_mm backend: send 17-64 rows to torch._scaled_mm when the 16-bit weight spills L2 (sm89) by @danielhanchen in #15791
- CI: turn update checks off in every job that drives a browser by @danielhanchen in #15815
- Studio tests: drain the background sandbox mover between tests by @danielhanchen in #15830
- Studio: emit no legacy load flag when the llama-server --help probe is inconclusive by @danielhanchen in #15828
- Mamba LoRA: apply a trained dt_proj / x_proj / out_proj adapter in eval and cached decode by @danielhanchen in #15730
- Studio diffusion: load the int8 GEMM operands through TMA descriptors on sm120 by @danielhanchen in #15829
- Block CUDA graphs: only release the cudagraph pool for tree functions the block backend compiled by @danielhanchen in #15777
- Tests: FP8 routing tests pin the NVIDIA path so they pass on ROCm runners by @danielhanchen in #15838
- Studio: skip the Keep resident page-lock when the llama-server --help probe is inconclusive by @danielhanchen in #15833
- Backend CI: split the fsdp2 Repo tests shard in two by @danielhanchen in #15851
- Fix OpenCode Go session headers in Studio by @Aafimalek in #15780
- Desktop: re-enable GPU compositing on NVIDIA X11 with driver 610 or newer by @oobabooga in #15546
- Studio tests: skip rag_conn where this Python's sqlite3 cannot load extensions by @danielhanchen in #15862
- GRPO: take the per-step host syncs out of the loss path by @danielhanchen in #15855
- Studio: keep refusing a symlinked spill where there is no O_NOFOLLOW (Windows) by @danielhanchen in #15887
- Studio: show the real error when a Responses stream fails by @NilayYadav in #15816
- Studio: show why llama-server rejected a chat request by @NilayYadav in #15817
- Packed attention: varlen probes under fullgraph + dynamic=True compile by @danielhanchen in #15891
- Studio tests: keep GGUF loads off the host's Metal budget unless a test asks by @danielhanchen in #15910
- Studio tests: measure the int8 / fp8 dequant and nibble-swap peaks in a fresh process by @danielhanchen in #15912
- Studio: restore the #15731 login layout by @shimmyshimmer in #15903
- Studio: lead the Live monitor tiles with the reading, unrounded by @shimmyshimmer in #15897
- Studio: put a just-created API token in the Agents command and API examples by @shimmyshimmer in #15890
- Studio: Images icon for Reference, file search icon for Chat with files by @shimmyshimmer in #15806
- Studio: Qwen-Image-2.1 eager renders before the deferred compile now match ComfyUI by @danielhanchen in #15908
- Studio diffusion: let a 12.7 GB host load FLUX.2-klein-9B by spilling the int8 denoiser to a scratch file by @danielhanchen in #15911
- Studio: stop the first Wan2.2-A14B render from waiting for the second expert's pin by @danielhanchen in #15906
- Studio tests: give managed engines ports another worker cannot be handed by @danielhanchen in #15915
- Studio: add a Quickstart heading over the API example tabs by @shimmyshimmer in #15898
- Studio: one text and control width for every settings row by @shimmyshimmer in #15905
- Studio: Decision tab loads at once, System and settings polish, main-theme borders restored by @shimmyshimmer in #15919
- Studio: decode format-check preview rows once per request by @danielhanchen in #15867
- Studio: index the training history's resumed-later check by @danielhanchen in #15872
- Studio: copy Whisper timestamp tokens to the host once per window by @danielhanchen in #15860
- Studio: fetch up to four Hub files at once over HTTP when partials resume by @danielhanchen in #15781
- Studio: reuse the VLM URL probe's downloads in the conversion by @danielhanchen in #15870
- Studio: fetch ShareGPT+image row images concurrently, in row order by @danielhanchen in #15786
- Studio desktop: ask desktop-capabilities in the launch probe on a capability cache miss by @danielhanchen in #15823
- Studio: find a code block's backtick runs by regex when picking its fence by @danielhanchen in #15913
- GRPO PrefixGrouper: import cleanly on torch 2.6 and keep it off below 2.7 with a log line by @danielhanchen in #15836
- Studio: write transcoded WAV blocks raw and fix the header once on close by @danielhanchen in #15917
- Studio: find VLM rows without an image or caption from Arrow validity by @danielhanchen in #15787
- Studio: score unclosed Markdown link destinations in linear time by @danielhanchen in #15811
- Studio: write each training metrics flush and its run progress in one transaction by @danielhanchen in #15871
- GRPO PrefixGrouper: build the shared-prefix layout from one host copy instead of per-token loops and per-segment device fills by @danielhanchen in #15835
- Studio: reuse recipe shard row counts while no shard changed by @danielhanchen in #15869
- Studio: make Recipes lint validators run on Windows and under a gitignored temp root by @danielhanchen in #15929
- Studio: wake admission waits on queue state changes instead of their next poll by @danielhanchen in #15885
- Studio: treat unknown parent liveness as alive in the llama-server reaper by @danielhanchen in #15921
- Studio: stop re-hashing kept spills and re-reading the record on every prune by @danielhanchen in #15884
- Studio: adopt the WAV save_from_media already transcoded instead of decoding it again by @danielhanchen in #15916
- Cleanup: remove 5 redundant pass statements that leave bytecode unchanged by @danielhanchen in #15790
- Studio setup.ps1: install bun only when the frontend is built by @danielhanchen in #15933
- Studio: keep the Markdown block split linear after an unmatched $$ by @danielhanchen in #15886
- Tokenizer loading: skip the unused slow tokenizer load when the fast one is returned as is by @danielhanchen in #15834
- Import fixes: disable a torchao too new for the installed torch instead of failing import unsloth by @danielhanchen in #15850
- Studio: make the install-time bytecode precompile opt-in by @danielhanchen in #15923
- Studio: read the file digest cache once per reuse estimate by @danielhanchen in #15914
- GGUF export: write the intermediate conversion inside the output folder so placing it is a rename by @danielhanchen in #15783
- Studio: build the MCP apps on first use instead of at backend import by @danielhanchen in #15814
- Studio: read only the run state for chunk-only chat run event batches by @danielhanchen in #15807
- Studio: skip the article and main scope passes when the page has no such tag by @danielhanchen in #15812
- Studio: preview local Parquet from its leading rows instead of loading it whole by @danielhanchen in #15868
- Studio: store float32 RAG vectors from their buffer and pack the query once by @danielhanchen in #15859
- Studio: share one in-flight /api/health read between the startup and route platform checks by @danielhanchen in #15794
- Studio tests: use a portable fake llama-server in the load cancel tests by @danielhanchen in #15826
- install-kernels: skip the torch import when a kernel's extension is absent, and probe torch only when a wheel is needed by @danielhanchen in #15896
- Studio: validate a recipe job's OXC batches in one Node process by @danielhanchen in #15925
- Studio: walk the sandbox once per tool call boundary for the files card and file history by @danielhanchen in #15793
- Studio: keep audio gallery operations in the folder they resolved by @danielhanchen in #15875
- Studio: skip the escaped-math parse when no escaped dollar pair can be math by @danielhanchen in #15808
- Studio: quantise an offloaded native int8 denoiser on the card, one linear at a time by @danielhanchen in #15936
- GRPO PrefixGrouper: fit the flex kernel on 101 KB shared-memory GPUs and stop its silent eager fallback by @danielhanchen in #15854
- Studio: skip the route's GPU probe when the GGUF fits in RAM by @danielhanchen in #15902
- Studio desktop: skip the device type read while the backend port is still unknown by @danielhanchen in #15824
- Studio Desktop: sync pinned models and overrides after the backend port is known by @danielhanchen in #15821
- Studio: matching Hugeicons permission icons, larger and top-aligned by @shimmyshimmer in #15944
- Tests: baseline the torchao import probe from #15850, gate the PrefixGrouper CUDA test on a real card by @danielhanchen in #15948
- Tests: follow the media header's MediaHeaderActions row from #15919 by @danielhanchen in #15946
- Studio: accent update buttons, standard switches, one icon per meaning by @shimmyshimmer in #15939
- Studio: greeting setting hides the whole greeting, composer at the bottom option, no model disclaimer by @shimmyshimmer in #15904
- Studio: write plain recipe export rows with one json.dumps call by @danielhanchen in #15926
- Studio: reuse the cached TLS context for llama-server health probes by @danielhanchen in #15792
- Studio: read the run history once per checkpoint listing by @danielhanchen in #15873
- Studio: keep an appearance edit made while the personalization load is in flight by @danielhanchen in #15953
- Studio diffusion: run both guidance branches per streamed block upload for Qwen-Image-Edit under a VRAM budget by @danielhanchen in #15930
- Tests: read _gpu_init.py as UTF-8 in the torchao-too-new test by @danielhanchen in #15957
- Studio: encode a batch's gallery PNGs concurrently by @danielhanchen in #15909
- Studio: skip the audio gallery prune's sidecar pass under both caps and list prepared inputs once per sweep by @danielhanchen in #15874
- Tests: mac tab walk waits for the sidebar to mount before judging a pinned row by @danielhanchen in #15959
- Studio video: MiniMax-H3 conditioner pin yields to a streamed denoiser on a small host by @danielhanchen in #15955
- Studio video: MiniMax-H3 unfused Q / K / V share one ConvRot rotation and act quant by @danielhanchen in #15956
- CI: split Repo tests (CPU, rest) and (CPU, gloo) before they reach their 2100 s cap by @danielhanchen in #15951
- Studio: say when remote access Start automatically opens a public URL by @NilayYadav in #15849
- Studio: encode each recall query once per compaction and let archive widening widen by @danielhanchen in #15960
- Studio: answer dense RAG search from an in-memory numpy matrix kept in sync by SQLite triggers by @danielhanchen in #15961
- Studio: match linked-folder paths against .gitignore runs, not rule by rule by @danielhanchen in #15949
- Studio: link to image training from the Train page by @NilayYadav in #15391
- Studio diffusion: a first load downloads the weights before the small-host decision reads them by @danielhanchen in #15974
- Let decision models export to GGUF on a fresh install by @NilayYadav in #15864
- Studio: stop Auto context from reserving a model's whole window on a Mac by @NilayYadav in #15843
- Tests: keep tqdm's monitor thread out of the ShareGPT no-threads count by @danielhanchen in #15992
- Studio: keep the user's git identity and gh login in unsloth start pi by @NilayYadav in #15865
- Studio: let unsloth start vibe start with smaller context windows by @NilayYadav in #15863
- Studio: restart a crashed GGUF model instead of showing it loaded by @NilayYadav in #15847
- Tests: make unsloth_cli/tests/test_start.py pass on Windows by @danielhanchen in #15987
- Studio: keep the loaded model if a GGUF download fails or is cancelled by @NilayYadav in #15846
- Studio: test that escaped currency keeps long replies streaming fast by @NilayYadav in #15820
- Studio: stop re-uploading the whole chat while a reply streams by @NilayYadav in #15818
- Studio: nvfp4 safetensors twins: converter 0-dim compare, refuse a twin the installed torchao cannot unflatten by @danielhanchen in #15977
- Studio: keep the app responsive as an MLX or Transformers load finishes by @NilayYadav in #15842
- Studio: stop the KV cache type following the last model to the next one by @NilayYadav in #15819
- Studio: share one edge index for Recipe Studio node connection status by @danielhanchen in #15942
- Studio: load downloaded models with fewer Hugging Face requests by @NilayYadav in #15844
- Tests: plant uv.exe on Windows in the MLX repair minimal-PATH lookup test by @danielhanchen in #15995
- Studio: reuse lexical passes and branch checks across a compaction and prune branch-run starts by @danielhanchen in #15972
- Studio: recommend a Hub GGUF quant that fits the Mac's Metal budget by @NilayYadav in #15848
- Studio: stop the Claude CLI billing line from breaking prompt caching by @NilayYadav in #15845
- Studio video: stage an fp32 encoder on the card when its dense cast would not fit host RAM by @danielhanchen in #15975
- Studio setup: skip the OXC validator npm ci when its installed tree is unchanged by @danielhanchen in #15947
- Studio diffusion: use an installed HIP SDK for the Windows ROCm sd.cpp build when its bin dir is not on PATH by @oobabooga in #15853
- Studio: train single-string-column datasets as raw text by @YakshithK in #15899
- Unsloth Studio: LFM3-Audio / LFM3-Omni on MLX, with spoken replies by @Lyxot in #15889
- fix(studio): attach an explicitly chosen MLX drafter even when it is priced not to fit by @Lyxot in #15813
- Tests: keep the RAG query-packing test on vec0 while the in-memory cache builds in the background by @danielhanchen in #16013
- Studio: load the chat page on first use instead of in the startup bundle by @danielhanchen in #15943
- Move the Unsloth Studio MLX pins to mlx-vlm 0.7.11 by @Lyxot in #15861
- Tests: price the auto-context fit floor as the layer-split path on any host by @danielhanchen in #16014
- Collapse blank line runs with a literal-led pattern (about 10x faster) by @danielhanchen in #15950
- Studio diffusion: Qwen-Image text-to-image activation seeds keep part of the int8 DiT resident under a VRAM budget by @danielhanchen in #15985
- Studio video: request a hosted .safetensors twin before each declared prequant .pt by @danielhanchen in #15980
- Studio: batch MLX tool-protocol, response_format and video replies; several clips and Gemma 4 video on MLX by @Lyxot in #15920
- Studio: Use via API button on the Train page by @danielhanchen in #15996
- Studio: say why AI Assist cannot map a dataset with no prompt/response split by @danielhanchen in #15991
- T4: hand batch-4 NF4 decode to the bitsandbytes gemm_4bit where it runs by @danielhanchen in #15988
- Tests: read the training API job bodies fixture as UTF-8 by @danielhanchen in #16025
- Studio: hand the audio route's heal gate the request's contract, and follow the hoisted audio_base64 in the turn-scope check by @danielhanchen in #16023
- Studio: Neural Engine Prefill toggle for MLX models by @Lyxot in #15954
- Studio video: compare streamed frames without chunk-sized temporaries (H3 export stalls) by @danielhanchen in #16024
- Studio video: streamed mp4 byte-identical to the stock export on every render (cap libx264 at AVX2 on AVX-512 hosts) by @danielhanchen in #16030
- Studio: int8 Qwen-Image text stream when the denoiser is streamed (1.24x under a 16 GiB budget) by @danielhanchen in #16027
- Studio MCP: bound get_job wait_s with a fixed limit, not the patchable MAX_WAIT_S by @danielhanchen in #16033
- Batched MoE LoRA: every job's expert LoRA in one grouped pass on Zoo's kernels by @danielhanchen in #16012
- Studio: toast icons centred on one line, top-aligned on longer toasts by @shimmyshimmer in #16050
- Studio: one set of sort and filter icons, shorter chat cards, toolbar tooltips by @shimmyshimmer in #15958
- Desktop: Add GPU rendering setting with a Linux launch-crash fallback by @Etherll in #15482
- GRPO: keep masking completions cut by the vLLM context limit by @danielhanchen in #16057
- Packed mRoPE flash attention: cover a padded tail, same decision when compiled by @danielhanchen in #16058
- Cross entropy: trace under torch.compile(dynamic=True) by @danielhanchen in #16059
- Scope WavLM's 4-bit attention skip to WavLM's own layers by @danielhanchen in #16060
- gpt-oss: accept an absolute transformers_weights inside the local model dir by @danielhanchen in #16061
- MXFP4 torch decode fallback: run ldexp on the operands' GPU by @danielhanchen in #16062
- FP8 scaled_mm: keep native fp16 output on torch >= 2.14 by @danielhanchen in #16063
- Context parallelism: refuse it beside tensor parallelism instead of training the wrong loss by @danielhanchen in #16068
- Studio video: batch the CFG pair into one call on a compiled resident Wan denoiser by @danielhanchen in #16067
- Context parallel: allow text-only Qwen3.5 checkpoints that carry a vision_config by @danielhanchen in #16072
- Studio: keep the composer still when switching chats in WebKit by @shimmyshimmer in #16076
- Studio: stop the chat composer draft mirroring into other open tabs by @debojyoti-dev in #15795
- float16: agree on GradScaler skips across pipeline stages, scale the CP start, probe the float16 FP8 GEMM by @danielhanchen in #16070
- Studio: scale the token count timeout so long chats can compact by @oobabooga in #15900
- fix(studio): list approved custom-code models in /v1/models by @Lyxot in #15945
- Studio: drag an image from one slot to another by @NilayYadav in #15876
- Studio: name a too-short context length when completion masking drops rows by @danielhanchen in #16000
- Studio: align the Images and Video preset dropdown with the title's top by @shimmyshimmer in #16081
- Tests: stub @/lib/folder-icons in the Hub GGUF card Metal budget test by @danielhanchen in #16082
- Studio: fill locale gaps and translate the sign-in, consent and Desktop startup screens by @shimmyshimmer in #16069
- Studio: no text selection from the clicks that follow a dropdown dismissal by @shimmyshimmer in #16077
- Studio: let conversation search return every earlier turn that fits by @NilayYadav in #16036
- Desktop: run the AppImage on the host's WebKitGTK 2.54+ when available by @Etherll in #15503
- Studio: add Spanish (Latin America) as a display language by @shimmyshimmer in #16089
- Studio: include Schema transform output in recipe dataset downloads by @NilayYadav in #16039
- Studio: strip only harmony protocol tokens from gpt-oss answers by @danielhanchen in #16004
- Studio chat: publish held stream text on the next frame instead of waiting for the next chunk by @danielhanchen in #15998
- Studio: stop skipping scheduled runs right after Studio starts by @NilayYadav in #16037
- Studio: batch the raw text blank row filter and EOS append for map-style datasets by @danielhanchen in #15978
- Studio: read a JSON body inside instead of running the call with no arguments by @danielhanchen in #16008
- Tests: run the MXFP4 operand device guard check on CPU-only torch too by @danielhanchen in #16088
- Report measured model loading and 4-bit conversion during image training by @Imagineer99 in #15536
- Studio: let managed accounts use local MCP servers when allowed by @NilayYadav in #16044
- Studio: int8 Qwen-Image streamed modulations through a fused GEMV (1.23x under a 16 GiB budget) by @danielhanchen in #16087
- Studio: size a cached DFlash sidecar from disk instead of asking the Hub on every load by @danielhanchen in #15986
- Bump trufflesecurity/trufflehog in / by @dependabot[bot] in #15968
- fix(studio): keep a long MLX vision chat's prompt snapshot past the cache budget by @Lyxot in #16079
- Bump swatinem/rust-cache in / by @dependabot[bot] in #15966
- Bump github/codeql-action init and analyze to v4.39.1 by @dependabot[bot] in #15964
- Bump actions/setup-python in / by @dependabot[bot] in #15963
- Bump the npm-oxc-validator group in /studio/backend/core/data_recipe/oxc-validator with 3 updates by @dependabot[bot] in #15962
- Studio: keep a resident GGUF's repo identity for Hub shared-blob cache files by @danielhanchen in #16086
- fix(eval): reserve explicit YAML task names by @hsusul in #15984
- Studio: offer video input only when llama-server can launch ffmpeg and ffprobe by @danielhanchen in #16094
- Tests: follow the localized update banners from #16069 by @danielhanchen in #16090
- Studio: keep attached documents in Deep Research reports by @NilayYadav in #16019
- Desktop: switch the theme without a view transition on Linux by @oobabooga in #16040
- Studio: recover Deep Research from provider JSON validation failures by @alkinun in #15788
- Studio: ask llama-server again with its tool parser off when it rejects a reply before streaming by @danielhanchen in #16002
- Studio: default Deep Research to no time limit per model request by @NilayYadav in #15983
- Studio installer (Windows): avoid unavailable CUDA torchao wheels by @oobabooga in #16016
- Studio: share one in-flight media model index build so the startup checks do not scan twice by @danielhanchen in #16075
- Add custom hourly intervals for scheduled tasks by @Imagineer99 in #15799
- Studio Images: enable GGUF LoRAs on MLX and diffusers, and explain when unavailable by @oobabooga in #16053
- Studio: read streamed dataset slices in batches instead of row by row by @danielhanchen in #16083
- Studio diffusion: test-launch sd.cpp binaries without the Windows missing-DLL box by @oobabooga in #16031
- Studio diffusion: Qwen-Image text-to-image streamed placement uses its own activation figure under a VRAM budget by @danielhanchen in #16095
- Studio: download the commit the manifest was planned from by @danielhanchen in #16047
- Studio: vector cache in float32 unit rows with streamed builds, in-place appends and bounded block scans by @danielhanchen in #16093
- Studio: add customizable chat background images and effects by @wasimysaid in #15973
- Studio: keep a bare-JSON tool call out of the final answer after the tool loop by @danielhanchen in #16003
- Studio: add OpenCode Zen and OpenCode Go to Connections by @NilayYadav in #16010
- Studio: honour speed on /v1/audio/speech by @NilayYadav in #16020
- Studio: compile the SDXL U-Net per block so the 4th image no longer waits for the whole compile by @danielhanchen in #16085
- Studio: stop offering the VibeVoice q4-ios GGUF that audio.cpp cannot load by @oobabooga in #16048
- Studio: recover a closed tool call whose single code argument has unescaped quotes by @danielhanchen in #16006
- Studio: add MiniMax to Connections by @NilayYadav in #16011
New Contributors- @YakshithK made their first contribution in #15899
- @hsusul made their first contribution in #15984
Full Changelog: v0.1.912-beta...v0.1.913-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: