Unsloth v0.1.910-beta Release Notes: Recursive's Flint, MOSS-Image and NVIDIA's Nemotron Bolt 4B are here! Run them locally in Unsloth. Also new: a chat-only Unsloth Desktop install, MLX MoE models bigger than your Mac's memory and an OpenAI-compatible fine-tuning API.
Highlights
- Bigger MoE models on Mac: MLX MoE models too big for memory keep experts on SSD, so Qwen3.8-Flash-Next runs on a 32 GB Mac.
- Chat-only install: a much smaller Unsloth Desktop for GGUF chat; add training later in Settings.
- Flint: Recursive's 40B coding-agent MoE, runs in 24 GB at 3-bit Guide
- MOSS-Image: 5.1B image model designed for top-tier generation GGUF + FP8
- NVIDIA Nemotron 3.5 Bolt E4B: NVIDIA's new Gemma 4 E4B fine-tune, 63.2 on Tau2-Bench vs the original's 38.7 Guide
- MoE expert pruning: Export a smaller MoE model by removing 25% or 50% of its least useful experts with REAP.
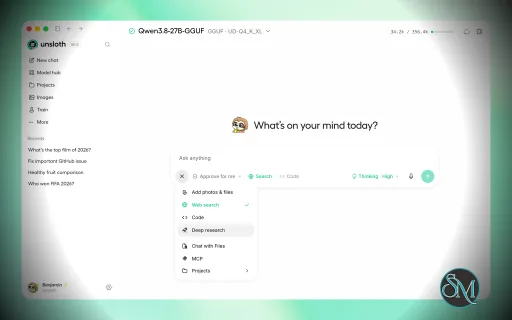
- UI overhaul: More consistent UI across Unsloth
Images + video
- Generate images containing English or Chinese text with OpenMOSS's 5.1B MOSS-Image, SFT or Base. GGUF · Base GGUF
- MOSS-Image, the new image model, runs on 16 GB GPUs; its GGUFs also run on Macs and computers without a supported GPU.
- Most image and video models too big for one GPU now split across your NVIDIA GPUs, if they fit, instead of streaming from system memory.
- The new Hires fix upscales and refines a render in one step on SDXL, FLUX.1, Qwen-Image and Z-Image.
- The new Compare grid renders one prompt while varying up to three settings, such as seed, CFG or LoRA weight, in labelled grids.
- SDXL safetensors get AUTOMATIC1111-style prompt weighting, CLIP skip, CFG rescale, variation seeds and textual inversion.
- Pasted AUTOMATIC1111, Forge or Civitai parameter blocks fill in the Images page settings.
- If SAM 3 isn't already downloaded, the Mask from text tool now uses SAM 3.1: smaller, with no Hugging Face login.
Chat + Desktop
- Pick Chat only (GGUF) when first launching Unsloth Desktop for a much smaller install; add training later in Settings.
- Settings > Chat now lets you view, edit, clear or turn off the memory notes Unsloth sends to every chat.
- In document-search chats, Show passages lists the exact text the model got and opens each passage at its page.
- The Audio page can speak and transcribe via a saved API connection, such as OpenAI or a local server.
- Unsloth installs, updates and
pip install -U unsloth now reject eMudhra's compromised emSign certificates, which let attackers impersonate websites. The optional vLLM and SGLang engines still trust them.
Flint
- Run Recursive's Flint, a 40B MoE model with 2.5B active parameters for coding agents, with reasoning, tool use and 256K context. Guide · GGUF
- At 3-bit, Flint fits in 24 GB at short contexts.
- On SWE-bench Pro v2, Flint scores 89.7 vs Qwen 3.6's 73.8.
NVIDIA Nemotron 3.5 Bolt E4B
- Run and fine-tune NVIDIA's Gemma Nemotron 4B, a Gemma 4 E4B reasoning tune for tool calling and instruction following.
- Gemma Nemotron 4B beats Gemma 4 E4B on 16 of 21 NVIDIA tests, gaining most in tool use and multi-turn chat.
- DPO on Gemma 4 E2B and E4B, including Gemma Nemotron 4B, no longer crashes.
Training
- Fine-tuning Whisper, Canary, Moonshine, Dia and CTC speech models with
FastModel no longer fails.
- Parakeet, Canary and CTC speech training uses up to 55% less memory.
- The new Books & Documents to Text recipe in Data Recipes turns ebooks and documents into a pretraining text dataset, no model needed.
- On Windows and Linux, the Export page can now prune 25% or 50% of a MoE model's least useful experts with REAP, at some quality cost.
- In Python,
reap_prune runs REAP expert pruning up to 54x faster than llm-compressor's.
unsloth train now trains vision and, except on Mac, audio models.
- Unsloth now supports OpenAI's fine-tuning API, so OpenAI's SDK can upload datasets and run supervised fine-tuning of local models.
Performance
- MLX MoE models too big for your Mac keep experts on SSD, with slower replies. Qwen3.8-Flash-Next fits a 32 GB Mac; DeepSeek-V4-Flash and GLM-5.3-Flash need far less memory than their size.
- DPO and other training that pads sequences runs up to 3.8x faster with less memory on NVIDIA Ampere or newer.
- Qwen3-MoE, Gemma 3 and Gemma 4 training on GPUs without bf16 now uses up to 7x less attention memory with torch 2.13 or older.
Coding agents + API
- In chat, models can now read text files and documents on connected MCP servers, not just use their tools.
- When launching coding agents,
unsloth start no longer sends its Unsloth API key in plain text through your HTTP proxy to a local Unsloth.
- On Windows,
unsloth start no longer breaks Claude Code hooks or Codex sign-in when launching them.
- Requests with an Unsloth API key can no longer run Python and terminal tools unsandboxed; only the Unsloth UI can allow that.
- The new Save for this model button in Chat settings makes your sampling settings that model's default for new chats and API requests.
Models + hardware
- A BF16 gpt-oss checkpoint loaded with
load_in_4bit = True no longer gets random expert and router weights.
- The model picker again lets you run models on Ryzen AI 300-series and newer NPUs, with no environment variable.
- On some Linux AMD PCs with a system-wide ROCm, GGUFs that ran on the CPU now run on the GPU again.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
 -- Platform
 -- Link


 -- Windows
 -- Download


 -- macOS
 -- Download


 -- Linux x64 / Ubuntu (deb)
 -- Download


 -- Linux ARM64 / Ubuntu 24.04+ (deb)
 -- Download


 -- Linux x64 (AppImage)
 -- Download


 -- Windows ARM64
 -- Download
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.10.7, unsloth-zoo>=2026.10.7 by @danielhanchen in #14276
- Studio: accept a quoted local training base and name single-file checkpoints in the refusal by @danielhanchen in #14236
- QLoRA quant-state fallback: gate per weight, not a process-global flag by @danielhanchen in #14231
- GatedDeltaNet fla op engages in training; large-head self-check survives a non-reentrant checkpoint by @danielhanchen in #14233
- gpt-oss MXFP4 without triton_kernels on transformers 4.x: keep dense expert biases in the model dtype by @danielhanchen in #14275
- FSDP2: gather for push_to_hub, refuse GGUF / torchao exports, size offloaded state and 4-bit counts per shard by @danielhanchen in #14205
- Large head attention follow-ups: compiled kill switch, 4-bit shard self check, forced float32 skip by @danielhanchen in #14188
- Optimizer parking outside inference mode; refuse fp16 params with unquantized adamw_flash moments by @danielhanchen in #14201
- Review follow-ups: fused LoRA dropout/bias under compile and 4-bit, Q-GaLore offload, GRPO truncated support, CP save on transformers 4.x by @danielhanchen in #14226
- CI: raise the Core zoo job cap from 25 to 35 minutes by @danielhanchen in #14240
- Studio: change Parallel Slots from the API page's Slots readout by @danielhanchen in #14225
- FSDP2 QLoRA: keep packed 4-bit bytes out of the loader dtype pass, fix merged_4bit save by @danielhanchen in #14165
- GRPO: reduce the IS ratio metric per sequence for geometric modes and the env override by @danielhanchen in #14192
- Retry the audio.cpp server on a new port when its port is taken by @danielhanchen in #14294
- fix(rag): avoid long CPU stalls when archiving tool calls by @ATAMAH in #14098
- Avoid unnecessary attachment reindexing on chat generation by @Imagineer99 in #14217
- Studio: update external llama.cpp default port to 9931 by @oobabooga in #14266
- Import fix: torchao 0.17+ on torch 2.6 (torch.utils._pytree.register_constant) by @danielhanchen in #14299
- whisper.cpp: skip the macOS release walk when llama.cpp is ahead of every release by @danielhanchen in #14302
- Studio: Library chat cards keep their column width and equal padding by @shimmyshimmer in #14305
- Baseline the unsloth-zoo 2026.10.7 scan findings after review by @danielhanchen in #14311
- Studio: SAM 3.1 for Mask from text, with pre-quantized INT8 / FP8 files by @danielhanchen in #14310
- Studio: serve /v1/completions from managed vLLM and SGLang engines by @danielhanchen in #14227
- Studio: logprobs on /v1/completions and /tokenize for MLX models by @danielhanchen in #14229
- Studio: fix FLUX.3 workflows, controls, LoRAs and download progress by @oobabooga in #14312
- Add a vLLM backend to unsloth eval by @danielhanchen in #14228
- Model catalog network check: judge FLUX.3 Klein by the mirror the backend fetches by @danielhanchen in #14316
- SAM 3 skeleton test: compare against a float32 load and find the RoPE tables by any spelling by @danielhanchen in #14318
- Raise the startup bundle budget for the FLUX.3 controls (#14312) by @danielhanchen in #14319
- Studio: open the Unsloth docs and Next.js sites in the browser panel by @NilayYadav in #14279
- Studio: load ComfyUI fp8mixed text encoders (nvfp4 / mxfp8 layers) by @danielhanchen in #14321
- Studio: fix Claude API reference pages in the browser panel by @wasimysaid in #14323
- Studio: let the browser agent tick radios and checkboxes by their label by @NilayYadav in #14282
- Native FSDP2: fully_shard per block and root for every model, LoRA, QLoRA and full finetuning (UNSLOTH_FSDP2=1) by @danielhanchen in #14273
- Studio: suggest Unsloth Docs in the web UI browser panel by @shimmyshimmer in #14324
- Studio Hub: rank Latest by trending against creation date, not last modified by @shimmyshimmer in #14329
- Studio: modern toggles, 34 x 20 with a flat centred thumb by @shimmyshimmer in #14322
- Raise the startup bundle budget for the modern toggles (#14322) by @danielhanchen in #14331
- Point Unsloth docs links at unsloth.ai/docs instead of docs.unsloth.ai by @shimmyshimmer in #14333
- Distributed tests: pick MASTER_PORT outside the ephemeral range, write vision results atomically by @danielhanchen in #14334
- Studio: keep project sources when a knowledge base is picked by @danielhanchen in #14255
- Desktop: offer a chat-only (GGUF) install and keep it through repairs by @danielhanchen in #14245
- Studio: let the model read MCP server resources by @danielhanchen in #14243
- Move the Unsloth Studio MLX pins to mlx-vlm 0.7.9 by @Lyxot in #14307
- Prebuilt wheels: build causal-conv1d and mamba-ssm for Linux torch 2.10 to 2.12 by @danielhanchen in #14336
- PEFT MoE conversion snapshot: add the Qwen3-Omni MoE text type and thinker aliases by @danielhanchen in #14344
- OpenAPI loop test: build the real schema outside the measured window by @danielhanchen in #14346
- Studio diffusion: multi-GPU component placement and CFG-parallel by @danielhanchen in #13725
- Studio: honor UNSLOTH_HOME in installers by @oobabooga in #14293
- Studio: make copy buttons on web pages work in the browser panel by @NilayYadav in #14284
- fix(studio): MLX memory estimate no longer allocates the model, and sizes DeepSeek V4 / V4.1 by @Lyxot in #14325
- Studio: keep runtime flash-attn installs wheel-only by @oobabooga in #14287
- Studio: keep text typed into a browser panel page when switching tabs by @NilayYadav in #14280
- Normalize role names when converting ChatML to Alpaca by @ShryukGrandhi in #14304
- fix(studio): align Whisper training labels with decoder prefix by @taking-lying-flat in #14244
- Studio: skip causal-conv1d for Qwen3.5 / 3.6 / Qwen3-Next when unsloth-zoo covers decode by @danielhanchen in #14148
- Studio: warn before downloading a program sent without an extension by @NilayYadav in #14278
- unsloth start (Windows): pass the sub-agent task over stdin so non-npm .cmd shims don't mangle it by @LeoBorcherding in #14300
- Studio: open each Settings tab at the top instead of the previous tab's scroll offset by @danielhanchen in #14353
- Studio: keep the page open when saving a bookmark by @NilayYadav in #14286
- Studio: download prebuilt kernel wheels once by @oobabooga in #14051
- Studio: honor width, height, steps, guidance, seed and negative_prompt on /v1/images/generations by @danielhanchen in #14351
- Studio: API keys run tools in the sandbox; Full access needs the Unsloth UI by @danielhanchen in #14345
- fix: preserve padding-free DPO sample boundaries in fast Llama/Qwen2 by @taking-lying-flat in #14251
- Unsloth Studio: a JSONL reply that quotes no longer stalls the tool parser and fails the turn with RecursionError by @LeoBorcherding in #14097
- Studio diffusion: pin Triton libdevice before the first compile so restarts hit the FX graph cache by @danielhanchen in #13713
- Studio: stop recipe dialogs opening a hint tooltip on open by @keyiyu0331 in #13668
- Studio: size sd.cpp's thread pool from the Apple fast cores by @danielhanchen in #13349
- Studio: prune dead startup records and preserve process identity by @oobabooga in #14301
- Studio diffusion: single-card CFG batching for a DiT streamed from host memory by @danielhanchen in #13787
- Studio: Mamba-2 hybrids use the extension-free mamba-ssm wheel when unsloth-zoo runs their conv on Triton by @danielhanchen in #14160
- Keep SFT kwargs passed beside a plain TrainingArguments instead of falling back to trl's defaults by @LeoBorcherding in #14094
- Unsloth Studio (AMD/Windows): show an iGPU's own memory on Settings > About, not the system RAM it can borrow by @LeoBorcherding in #14317
- Studio compile cache: keep every graph across re-saves, and save under torch's compile lock by @danielhanchen in #14341
- fix: preserve sentence encoder adapters and export dense 16bit weights by @taking-lying-flat in #14246
- Studio diffusion: cache runtime-quantized denoisers as local pre-quant checkpoints by @danielhanchen in #13715
- load_in_fp8=True quantizes a model with no FP8 repo instead of silently loading it in bf16 by @LeoBorcherding in #14093
- check_tokenizer: repair out-of-vocab added tokens on transformers 5.x, and raise when one can't be repaired by @LeoBorcherding in #14096
- save_pretrained_gguf: stop rewriting a reused local checkpoint's tokenizer with a BOS-stripped template by @LeoBorcherding in #14095
- Studio sd.cpp: explicit VRAM budget for MiniMax-H3 and a CUDA capability fallback by @danielhanchen in #13714
- MoE grouped GEMM: require sm90 on every visible card for TMA and launch on the operands' device by @danielhanchen in #14358
- Studio diffusion: run FLUX.3 base conditioning blocks once per render by @danielhanchen in #14367
- Fix chat context counts and token usage details by @Sneakr in #14076
- Installers: do not install generic aarch64 CUDA torch on Jetson before CUDA 13 by @danielhanchen in #14363
- Stop fix_executorch from hiding an installed torchtune by @danielhanchen in #14375
- Tests: keep gloo FSDP2 test ranks on the CPU on GPU hosts by @danielhanchen in #14383
- fix: release the device cache through the active accelerator on the vLLM resume/teardown paths by @li-lizhe in #13438
- Fix phone-deployment QAT for Gemma3 and LoRA, and write the matching ExecuTorch export config by @danielhanchen in #14376
- Studio: run Ada FP8 precise accumulate through a unit-scale GEMM plus a fused scale epilogue by @danielhanchen in #13793
- Studio: pin the FLUX.3 prompt upsampler to the image model's card under HIP masks and on Vulkan builds by @danielhanchen in #14356
- NF4 decode on T4: use the bitsandbytes 4-bit GEMM above the GEMV row cap by @danielhanchen in #14386
- Studio diffusion: record a prompt length's CUDA graph on the first render only by @danielhanchen in #14387
- Studio: Load anyway for the unified-memory diffusion refusal, and a capacity fix for its pre-download check by @danielhanchen in #14379
- Studio/CLI: report Rosetta, skip audio.cpp CUDA on pre-Turing GPUs, pass doctor on MPS/XPU, hide XPU from token preview by @danielhanchen in #14374
- llama.cpp prebuilt: accept upstream win-rocm bundles, run native arm64 under Rosetta, source-build on Jetson by @danielhanchen in #14373
- Gate XPU bf16 on native support, hint CUDA_DEVICE_ORDER on mixed NVIDIA hosts, read the Metal GPU family for MLX bf16 by @danielhanchen in #14371
- Raise the startup bundle budget for the Rosetta chat-only messages (#14374) by @danielhanchen in #14407
- Block compile: keep the stock forward under DeepSpeed ZeRO-3 by @danielhanchen in #14396
- Studio: prefer discrete GPUs over unified-memory APUs in automatic GGUF placement; clamp Vulkan free to total by @danielhanchen in #14372
- Refuse load_in_8bit with fast_inference instead of silently loading vLLM in 16-bit by @danielhanchen in #13019
- Studio: retry json_object as json_schema when a custom provider (LM Studio) refuses it by @cedric66 in #11813
- Studio: fix First Block Cache on FLUX.2 (dual-stream head, single-stream tail) by @danielhanchen in #14401
- Studio: offload-first retry for an OOM VAE decode, fuse GroupNorm+SiLU on uncovered VAEs by structure by @danielhanchen in #13802
- FP8 block dequant below sm89: decode e4m3fn bytes in one Triton pass by @danielhanchen in #14408
- int4 packed: trace the training dequantize inside torch.compile by @danielhanchen in #14385
- Block compile: find decoder layers structurally and wrap mixed stacks per class by @danielhanchen in #14397
- Native FSDP2: keep blocks that share parameters in the root unit (Zamba2) by @danielhanchen in #14384
- Studio: pick ROCm flash attention by a whole-block timing probe instead of a model table by @danielhanchen in #13792
- Studio: encode Wan clips while the VAE decodes by @danielhanchen in #14405
- FastLanguageModel LoRA / QLoRA: compile each decoder block as one region by @danielhanchen in #14398
- Studio: run MiniMax-H3 PDD checkpoints with their 32-head output bank, refuse the ones that cannot run by @danielhanchen in #14410
- DeepSpeed ZeRO-2 / ZeRO-3: stage detection at load, MoE and fused LoRA leaves, precision resync, reentrant checkpointing by @danielhanchen in #14394
- Fuse the decode residual add into RMSNorm (one Triton launch per norm) by @danielhanchen in #14382
- Tests: read checked-in sources as UTF-8 in three new test files by @danielhanchen in #14414
- QAT test: spoof CUDA in the unpickling child on GPU-less runners by @danielhanchen in #14415
- Studio: show the retrieved passages behind a document search by @yejonz in #13987
- Studio video stream encode: a failed final flush falls back instead of hanging the render by @danielhanchen in #14413
- GRPO under DeepSpeed ZeRO-3: score with the gathered head, no_grad instead of inference_mode by @danielhanchen in #14395
- FP8 byte dequant: pass enable_fp_fusion at the launch by @danielhanchen in #14416
- Studio: decode the Rosetta sysctl probe as UTF-8 by @danielhanchen in #14419
- DDP: gradient_as_bucket_view for full finetuning, opt-in bf16 / fp16 gradient all-reduce by @danielhanchen in #14399
- Studio no-torch runtime: pin certifi 2026.10.19, the floor fastmcp-slim now requires by @danielhanchen in #14418
- Tests: run the precision template in one namespace, keep the block-compile packing test off leaked env by @danielhanchen in #14425
- RoPE: multi-head tiles, Q and K in one launch, no clones (2-2.7x per call) by @danielhanchen in #14417
- gpt-oss: load_in_4bit from a BF16 checkpoint no longer loads random experts and router by @danielhanchen in #14400
- Studio Hub: list every image and video model under Recommended by @shimmyshimmer in #14421
- Studio diffusion: VAE OOM under a component split, expanded timesteps in the CFG routers, and test fixes by @danielhanchen in #14420
- Studio diffusion: match family keywords only on a local model's own path, and undo the torch 2.13 slice patch in the speed tests by @danielhanchen in #14435
- Studio: split one diffusion denoiser across GPUs by block ranges by @danielhanchen in #14412
- Installers (ROCm on WSL): no empty LD_LIBRARY_PATH entry in the profile drop-in by @danielhanchen in #14433
- Studio: retire the seeded password on Desktop and keep API callers on Sandbox High by @danielhanchen in #14422
- Studio: harden Data Recipe engine inputs by @danielhanchen in #14424
- Studio: harden the server against stalled bodies, long login names, readable logs and managed-account fetches by @danielhanchen in #14426
- Studio: managed dataset media decodes stay on readable files, and Arrow data files are validated by @danielhanchen in #14430
- Studio: managed accounts cannot use another account's loaded model or export worker by @danielhanchen in #14432
- ROCm: eager batch-1 NF4 decode takes the Triton GEMV (1.8x decode on gfx1151) by @danielhanchen in #14440
- Dependabot: hold cairo-rs and windows-core with the GTK3 / WebView2 pins by @danielhanchen in #14441
- Bump the npm-oxc-validator group in /studio/backend/core/data_recipe/oxc-validator with 3 updates by @dependabot[bot] in #13832
- Bump the actions group across 1 directory with 8 updates by @dependabot[bot] in #13835
- Studio: approval waits free their slot, Deep Research honours --disable-tools, first-run shutdown survives a read error by @danielhanchen in #14434
- Studio: tighten managed-account tool confinement by @danielhanchen in #14423
- Installers (ROCm on WSL): fetch the helper from the commit with the LD_LIBRARY_PATH fix by @danielhanchen in #14449
- Studio: Linux torch 2.10 to 2.12 take our causal-conv1d and mamba-ssm wheels by @danielhanchen in #14338
- Studio diffusion: hand compiled blocks the recorded tensor kind on graphless steps (no recompile on a new prompt length) by @danielhanchen in #14448
- Studio Train: clearer selected tabs, toggles and target modules in dark mode by @shimmyshimmer in #14451
- Studio: harden the tool sandbox around host launches, probes and workdir paths by @danielhanchen in #14429
- Studio: show the Auto download reason only when it falls back to HTTPS by @shimmyshimmer in #14454
- Studio: keep diagrams, redirect links and approval cards honest by @danielhanchen in #14427
- Studio: Projects new-chat button, Projects home in the sidebar menu, even menu padding by @shimmyshimmer in #14456
- Honour every_n_layers and drop redundant offload in gradient_checkpointing_enable by @danielhanchen in #14403
- Gradient checkpointing: checkpoint_skip_layers = "auto" and UNSLOTH_GC_KEEP_LAYERS by @danielhanchen in #14404
- Bump the npm-oxc-validator group in /studio/backend/core/data_recipe/oxc-validator with 3 updates by @dependabot[bot] in #14467
- Studio: managed-account paths are checked as they are opened by @danielhanchen in #14428
- Studio and Core: close remote-code gate gaps in Sentence Transformers, GGUF export, scans and tokenizer paths by @danielhanchen in #14437
- Call the app Unsloth or Unsloth Studio, never a bare Studio by @shimmyshimmer in #14473
- unsloth start dsh: warn when the loaded context leaves replies no room by @danielhanchen in #14352
- Studio: truncate over-length /v1/embeddings inputs instead of failing by @danielhanchen in #14364
- Studio: managed accounts keep the configured Decision checkpoint; signed-out Hub relay hides upstream errors by @danielhanchen in #14462
- Studio: one slider look everywhere, filled with the accent by @shimmyshimmer in #14471
- Unsloth Studio: redesigned API page, multi-model support and a Run settings fix by @shimmyshimmer in #14455
- Studio: let browser pages open target=_blank links and show alerts by @danielhanchen in #14360
- Bump the cargo-tauri group in /studio/src-tauri with 26 updates by @dependabot[bot] in #14468
- Studio Images: say why LoRAs vanish after Speed=Auto compiles, offer a reload by @danielhanchen in #14359
- Studio: train the system column of an Alpaca dataset by @NilayYadav in #14392
- Studio: point Desktop Chat only users at Repair installation on the Export page by @oobabooga in #14438
- Studio: count reclaimable active file cache as available host RAM under a cgroup limit by @danielhanchen in #14475
- Studio: Z-Image unload test works on diffusers without ROPE_PER_DEVICE by @danielhanchen in #14478
- Studio: keep Insert > Symbol characters when reading Word files by @NilayYadav in #14393
- Core: per-user fp8 cache, SyntheticDataKit binds vLLM to loopback by @danielhanchen in #14460
- Desktop and Windows installer: browser-panel capture prompt, private ACL for a custom Studio home by @danielhanchen in #14464
- Studio: keep the chat model loaded when an API request loads a speech model by @danielhanchen in #14369
- Studio: initialise the CUDA driver off the GIL so load-progress polls stay responsive by @danielhanchen in #14452
- Fix: [Bug] Installer hard-codes PyPI.org instead of respecting PIP_INDEX_URL / UV_INDEX_URL by @SIDDARTHAREDDY8 in #13748
- Dependabot: leave hand-kept pins to the version matrix and hold the GTK3 and deep-link crates by @danielhanchen in #14470
- Studio: honor completion-only training for audio VLMs by @taking-lying-flat in #14402
- Studio: never walk init's descendants when stopping a server by @danielhanchen in #14486
- Studio: save files from download buttons inside browser panel pages by @NilayYadav in #14285
- Studio: keep tools working after opening a chat file in its app by @NilayYadav in #14390
- Studio: stop two Studio windows undoing each other's browser data by @NilayYadav in #14277
- Sample Qwen3 models for the turn's thinking mode in unsloth chat by @NilayYadav in #14388
- MoE grouped GEMM: accumulate expert dW into an existing param.grad by @danielhanchen in #14480
- Studio: trim the runtime update card to one summary line and two actions by @oobabooga in #14436
- Studio: keep lone asterisks and backticks in finished chat replies by @NilayYadav in #14391
- Studio: picking a preset no longer overwrites a model's remembered sampling by @danielhanchen in #14128
- FP8 block dequant: ragged / rectangular e4m3fn blocks take the byte decoder on every NVIDIA GPU (4-16x) by @danielhanchen in #14450
- Studio: let the owner share a connection with every account by @danielhanchen in #14365
- Studio diffusion: allow the multi-GPU layer split on discrete ROCm cards by @danielhanchen in #14479
- Studio: make Back in the browser panel work like a browser's by @NilayYadav in #14283
- Studio: same diffusion pixels on every B200 server for FLUX.2 Klein and Z-Image by @danielhanchen in #14483
- Studio: per-user temp folders, tighter tool sandbox grants, no UNC paths for managed accounts by @danielhanchen in #14461
- Studio: MCP widget approval cards show the arguments being sent by @danielhanchen in #14458
- Unsloth Studio / Desktop: keep floating panels where they were left across resizes, minimize and restarts by @danielhanchen in #14355
- Studio: view, edit and turn off chat memory in Settings > Chat by @danielhanchen in #14357
- Studio: login limiter and keyless access behind a reverse proxy by @danielhanchen in #14459
- Studio: make CPU RAG embedding fast on Windows ROCm torch and honour Windows CPU affinity by @danielhanchen in #14354
- Studio: media decodes open no protocols, Data Recipe names stay inside their folder by @danielhanchen in #14463
- Train vision and audio models from unsloth train by @NilayYadav in #14389
- Tests: real-accelerator skip guards and utf-8 read in the gpt-oss and gc-skip tests by @danielhanchen in #14504
- Block compile: test that checkpoint early-stop does not demote the layer by @indrajeetapache in #14065
- Keep has_internet from setting the process-wide socket timeout by @vineethsaivs in #14378
- Dequantize FP8 weights in the activation dtype for fp16 LoRA by @danielhanchen in #14495
- Cross entropy: 16384 / 8 warp chunked forward on T4 and A100 by @danielhanchen in #14498
- GRPO: opt-in rollout logprobs as the old policy (UNSLOTH_GRPO_ROLLOUT_LOGPROBS_AS_OLD) by @danielhanchen in #14489
- Studio diffusion: keep a model-offloaded denoiser's step eager instead of re-recording its CUDA graph every render by @danielhanchen in #14497
- Studio: route krea2 GGUFs to Images instead of opening them as chat models by @indrajeetapache in #14477
- Copy uv constraint files to a space-free path on Windows volumes without 8.3 names by @danielhanchen in #14507
- Fix main's red CI after #14437, #14455 and #14473 by @danielhanchen in #14517
- CLI: --parallel help describes the shared KV cache by @danielhanchen in #14340
- FSDP2 gloo tests: stub every helper the trainer wrapper calls, not a fixed list by @danielhanchen in #14518
- Windows installer: restore the split-layout comment in setup.ps1 (Defender ML false positive) by @danielhanchen in #14520
- Tests: follow #14473's Unsloth wording in the sandbox, xformers and autoopt parity checks by @danielhanchen in #14522
- Add REAP expert pruning for MoE models by @danielhanchen in #13834
- Studio: opt-in REAP expert pruning on the Export page by @danielhanchen in #14130
- Studio: send the TTS language to Supertonic and add a Speak language picker by @danielhanchen in #14511
- unsloth start openclaw: stop writing the legacy exec-approvals.json that OpenClaw 2026.8.1+ refuses to run with by @danielhanchen in #14343
- Studio: whisper.cpp updates ride along with llama.cpp instead of opening the update card by @danielhanchen in #13862
- QAT: qat_scheme = "nvfp4", and strip NVFP4 / MX QAT linears before saving by @danielhanchen in #14512
- Studio diffusion: key learned peaks on the unsloth mirror a fresh install downloads by @danielhanchen in #13847
- Dequantize fine-grained fp8 checkpoints on a 16bit load in FastLanguageModel, and save them as 16bit by @danielhanchen in #14516
- Studio diffusion: place bf16 and GGUF / int8 packed denoisers from their learned peak by @danielhanchen in #13860
- Load FP8 checkpoints dequantized to 16-bit on GPUs below sm89 by @danielhanchen in #14531
- Cast float32 activations into the float16 projections of Falcon-H1 / Nemotron-H fp16 loads by @danielhanchen in #14532
- NVFP4 fused dX: skip split K on sm89 when the output already fills the GPU by @danielhanchen in #14536
- MoE grouped GEMM: share autotuners across identical cards; fix the TMA test on one-GPU hosts and macOS by @danielhanchen in #14490
- Jetson / Rosetta follow-ups: an explicit GPU index beats the Jetson CPU record, JetPack 7 off the CPU note by @danielhanchen in #14494
- Studio diffusion: compile group-offloaded blocks below their hooks on the deferred profile and for planned-offload video by @danielhanchen in #14528
- Wait for the Unsloth-managed folder label in the project folders browser smoke by @danielhanchen in #14542
- Studio: Z-Image guided steps run at the guidance-off batch so turning CFG on recompiles nothing by @danielhanchen in #14541
- Keep two Backend CI tests valid on uv 0.13 and on runners with no accelerator by @danielhanchen in #14535
- Format the grouped GEMM single-flight wrapper so pre-commit.ci passes again by @danielhanchen in #14544
- Studio: refuse a single-file diffusion load that would exhaust host RAM instead of crashing by @danielhanchen in #14510
- XPU bf16 on the current device, keep explicit bf16 on XPU, MLX full finetuning keeps its default dtype by @danielhanchen in #14493
- Load the real loader_utils helpers into the precision conflict test harness by @danielhanchen in #14545
- Studio: FLUX.3 upsampler pin follows torch's vendor, single-GPU hosts launch as before, non-blocking Vulkan probe by @danielhanchen in #14491
- Studio: discrete-first GGUF placement keeps explicit device picks, matching context ceiling; in-process Rosetta check by @danielhanchen in #14492
- MoE grouped GEMM: per-expert dW kernel by @danielhanchen in #14550
- Studio Images: paste generation parameters, inpaint mask blur and only-masked area, seed buttons by @danielhanchen in #14508
- Count the context ceiling's per-device reserve gate from #14492 in the compute buffer wiring test by @danielhanchen in #14560
- MoE autotune: run the kernel tuning eagerly when called from a compiled block by @danielhanchen in #14559
- Studio: Z-Image CFG split under static step skip and CFG-parallel by @danielhanchen in #14551
- Take the least of three RssAnon peaks in the block dequant host RAM check test by @danielhanchen in #14561
- Studio: show the AMD NPU by default again, with a clearer setup notice by @danielhanchen in #14524
- Studio Images: per-generation Shift for flow-matching models and SDXL textual inversion embeddings by @danielhanchen in #14563
- Pin Lemonade 2026.43.3 by @danielhanchen in #14567
- Studio: pin the master-982 stable-diffusion.cpp prebuilt so MOSS-Image GGUFs load by @danielhanchen in #14565
- Give the startup transfer budget headroom again after #14524 set it to its own build by @danielhanchen in #14571
- Skip the compiled MoE autotune test on the recorded real CUDA, not the spoofable probe by @danielhanchen in #14577
- MoE autotune cache: compare device capability as a tuple so saved configs are reused by @danielhanchen in #14578
- Measure the block dequant peak in a fresh process by @danielhanchen in #14579
- MoE fallback kernel configs: fit the device shared memory for float32 operands by @danielhanchen in #14576
- Studio diffusion: keep fp8 single-file weights stored in fp8 where widening would offload or crowd host RAM by @danielhanchen in #14549
- Studio: keep CFG-parallel on the default speed tier and run Z-Image's guidance branches on two cards by @danielhanchen in #14564
- Studio diffusion: turn on the measured-safe optimizations by default (fused FLUX RoPE, CFG batching, Blackwell native attention, BF16 small DiTs) by @danielhanchen in #14566
- Studio video: export GIFs with one clip-wide palette (about 3x faster) by @danielhanchen in #14581
- Studio diffusion: latch failed fused fp16 RoPE and AdaLN launches for the load by @danielhanchen in #14583
- RoPE cache: build cos/sin outside inference_mode so GRPO keeps the compiled decoder block by @danielhanchen in #14584
- Keep Unsloth Studio data after docker rm on CPU-only Docker hosts by @NilayYadav in #14540
- Fast decode: rotate Q and K in one launch, and fuse Qwen3 q/k norm with RoPE by @danielhanchen in #14599
- Honor requested languages for Studio Qwen3-ASR transcription by @tompipe in #14548
- Studio: show relative and blob Hugging Face images in Hub model cards by @shimmyshimmer in #14602
- Studio: chat fork fixes and clearer fork affordances by @shimmyshimmer in #14587
- Studio: Projects recency by chat activity, less polling behind projects and sources by @shimmyshimmer in #14586
- QAT: qat_scheme = "mxfp8", and let MX QAT linears take float32 activations under autocast by @danielhanchen in #14607
- unsloth start: fix Studio discovery, proxy, Hermes context, Claude hooks and Codex login by @shimmyshimmer in #14591
- Studio: faster, clearer model folder management by @shimmyshimmer in #14588
- MoE grouped GEMM: no lock on cached autotuner launches; read the SM count once per card by @danielhanchen in #14605
- Studio: token activity shows a year of quartile-shaded days, with accurate counts behind it by @shimmyshimmer in #14600
- Studio: shortcut fixes for non-US layouts, Esc and Cmd-K, plus clearer settings by @shimmyshimmer in #14597
- FLUX.3 upsampler: name older NVIDIA Vulkan devices as NVIDIA, probe an empty answer once per window by @danielhanchen in #14604
- Studio: more accurate connection checks and clearer errors by @shimmyshimmer in #14594
- Studio Run settings: restore saved settings on a fresh editor, show save state, group Advanced rows by @shimmyshimmer in #14589
- Fast LayerNorm backward: no aliased gradient buffers when only one of weight / bias trains by @danielhanchen in #14609
- Fused decode RoPE: drop the per-layer host drain on split models by @danielhanchen in #14611
- Studio: resize the sliding pill with transforms, so it keeps pace with the move by @Etherll in #14361
- Studio: OpenAI-compatible fine-tuning jobs API (/v1/files, /v1/fine_tuning/jobs) by @danielhanchen in #14496
- MoE autotune cache: version disk entries and refit loaded configs by @danielhanchen in #14617
- Studio Images: SDXL prompt weighting, CLIP skip, CFG rescale and variation seeds by @danielhanchen in #14562
- NF4 bitsandbytes GEMM gate: return before its lazy setup under torch.compile by @danielhanchen in #14608
- Studio: say when an attached image is over the 20 MB limit by @NilayYadav in #14538
- Studio: accept skills whose description has an unquoted colon by @NilayYadav in #14537
- Studio: keep Decision API models out of the chat model picker by @NilayYadav in #14580
- Studio: refuse Laya choice questions whose options would be cut short by @NilayYadav in #14558
- Give the single-row cached attention harness CPU stand-ins for the fused decode RoPE kernels by @danielhanchen in #14632
- Studio: shortcut follow-up to #14597 for Swiss/Turkish digit chords and Esc-to-stop by @shimmyshimmer in #14633
- Studio: busiest day keeps the darkest token activity shade (follow-up to #14600) by @shimmyshimmer in #14630
- Studio: keep Projects page renames and deletes from waiting out a streaming reply by @shimmyshimmer in #14634
- Studio: keep folder identity lookups inside the scan budget (follow-up to #14588) by @shimmyshimmer in #14638
- Studio: name an untitled chat's fork after its first reply (follow-up to #14587) by @shimmyshimmer in #14636
- unsloth start: hard-link only auth.json into the Codex parent overlay (follow-up to #14591) by @shimmyshimmer in #14635
- Studio: default scheme-less public provider URLs to https (follow-up to #14594) by @shimmyshimmer in #14629
- NVFP4 fused GEMM: honor autocast dtype and check K alignment for dX by @danielhanchen in #14625
- MoE LoRA: widen gate_up_proj to split gate_proj / up_proj experts when down_proj already matches by @danielhanchen in #14628
- Studio: engine versions and updates in Settings, Use via API for Images and Video, shorter Notifications, rounder waveforms by @shimmyshimmer in #14590
- Studio Settings: stop forcing a GitHub release lookup on every Settings open by @shimmyshimmer in #14649
- Studio: stop long MLX chats from re-reading the whole chat every turn by @NilayYadav in #14574
- Studio diffusion: test First Block Cache on a two-card FLUX.2 layer split by @danielhanchen in #14620
- Studio: load GGUF models faster by skipping the vocabulary read by @NilayYadav in #14573
- Fix save_pretrained_torchao for full finetuning QAT on transformers 5 by @danielhanchen in #14639
- RMSNorm: enable the narrow-row kernels on ROCm with the DPP reduction order by @danielhanchen in #14637
- Studio: stop a Clef decision model from outliving a crashed Unsloth by @NilayYadav in #14556
- Unsloth Studio: serve an MLX model through the library that loaded it by @Lyxot in #14612
- Studio composer icon check: re-measure a case when the dev page reloads mid-case by @danielhanchen in #14647
- Trim comments in the Studio frontend tests by @danielhanchen in #13859
- Trim comments in the Studio backend tests by @danielhanchen in #13874
- Studio: open localhost addresses typed in the desktop browser panel by @NilayYadav in #14290
- Gate the fused decode RoPE tests on a real CUDA device, not the spoofable probe by @danielhanchen in #14661
- Windows UI lane: retry the permission suite's auth wipe while the stopped server releases auth.db by @danielhanchen in #14658
- Studio: speak through a saved connection on the Audio page by @NilayYadav in #14288
- Native FSDP2 float16: fix fused AdamW crashing at the first step by @danielhanchen in #14663
- Chat: the composer dock stops searching the whole thread on every com… by @Sneakr in #14585
- Studio: keep the image info stamp off by default, recipe stays in the metadata by @danielhanchen in #14669
- Studio: cut polled-probe cost and release memory sooner by @shimmyshimmer in #14595
- Studio: stop showing a crashed chat model as loaded by @NilayYadav in #14575
- feat: add EPUB and optional MOBI dataset loading by @HughScott2002 in #14453
- Studio: optional reply times in Settings > Chat by @danielhanchen in #14500
- Studio: unload an idle decision model when another model loads by @NilayYadav in #14555
- FastSentenceTransformer: non-reentrant gradient checkpointing under DDP for encoder models by @danielhanchen in #13639
- Studio: stop the SDPA probe reporting fused attention on MPS by @Lyxot in #14488
- Studio: extract ebooks, Office files and email in Data Recipes document seeds by @danielhanchen in #14499
- FP8: keep every scoped converter and clean up every dequantizing load before save by @danielhanchen in #14678
- Attention routing tests: follow torch's own GQA kernel choice (fixes two failures on torch 2.14) by @danielhanchen in #14672
- Studio: lighter system polling and clearer unified-memory monitor by @shimmyshimmer in #14592
- Studio settings: fix API, Connections, Remote access and LAN issues by @shimmyshimmer in #14596
- Studio: lower the VRAM budget floor to 10% for multi-GPU spreading by @Shooter3k in #13427
- MoE grouped GEMM: keep the legacy dW kernel when an explicit tile overflows per-expert shared memory by @danielhanchen in #14723
- Studio: warn when a GGUF is tight for Apple unified memory by @shimmyshimmer in #14598
- Studio: transcribe audio through a saved connection on the Audio page by @NilayYadav in #14289
- Studio: let the owner turn off the Decision API while a model loads by @NilayYadav in #14557
- tests: restore transformers' Fp8Dequantize after the fp8 save policy tests by @danielhanchen in #14741
- FP8 dequant: multiply per-tensor and rowwise scales in fp32 for fp16 output by @danielhanchen in #14677
- Studio: upgrade a Desktop Chat only install to the full install from Settings by @oobabooga in #14593
- NVFP4: keep fast decode callers in the activation dtype under autocast by @danielhanchen in #14750
- feat(studio): MLX PLE and expert offload in Unsloth Studio by @Lyxot in #14326
- Unsloth Studio (Vulkan): fill the discrete GPU before a shared-memory iGPU in a mixed pin by @LeoBorcherding in #12650
- CFG-parallel: treat a changed Python number, storage offset or autocast as a cold call by @danielhanchen in #14614
- Studio diffusion: keep CFG batching off for a resident denoiser with no device timer (CPU, MPS) by @danielhanchen in #14652
- Images: refuse Flux base / max shift values that build NaN sigmas by @danielhanchen in #14613
- Studio diffusion: give stored-fp8 denoisers their own planner label instead of dense by @danielhanchen in #14631
- Studio sd.cpp: BF16 text encoders by default (Q8_0 / Q4_K_M changed pixels), opt-in lower precision by @danielhanchen in #14697
- NVFP4 QAT: require in_features divisible by 32 by @danielhanchen in #14703
- Studio diffusion: report compile and CUDA graph engagement in the image and video status by @danielhanchen in #14656
- Studio diffusion: replay a model-offloaded denoiser's CUDA graph across renders and pin torchao int8 host weights by @danielhanchen in #14666
- Studio diffusion: arm FLUX.1 prompt-length dynamic shapes so int8 does not recompile on a long prompt or new size by @danielhanchen in #14689
- FSDP2 QLoRA: keep 4-bit merge operands on one device in push_to_hub_merged by @danielhanchen in #14724
- Studio diffusion: arm Z-Image's prompt-length inputs for an int8 / fp8 compile by @danielhanchen in #14715
- Block compile: let an enclosing torch.compile own wrapped decoder layers by @danielhanchen in #14704
- Studio sd.cpp: one CPU thread per usable physical core on Linux by @danielhanchen in #14694
- Studio: clamp the top_k a model passes to search_knowledge_base by @roydonsequeira in #14222
- Studio NVFP4: keep ungated and gate-failing video builds out of Auto, check flashinfer against the gate record by @danielhanchen in #14659
- Compiled blocks: packed GatedDeltaNet op, flex main kernel in training blocks, PrefixGrouper calls skip the block (0 graph breaks) by @danielhanchen in #14782
- 4-bit decode: no recompile from the eager setup, one output dtype under autocast, refresh the cached LoRA cast by @danielhanchen in #14754
- MoE LoRA targets: keep a requested router sibling when attention modules are also listed by @danielhanchen in #14745
- Two-GPU decode RoPE test: check the copy bitwise and the rounding at 2 ulp by @danielhanchen in #14752
- Studio Images: Hires fix and ESRGAN model upscalers by @danielhanchen in #14651
- Studio diffusion: change baked LoRA subsets and weights without recompiling or recapturing by @danielhanchen in #14692
- Studio: build the CFG-parallel replica outside inference mode and catch in-place edits of inference weights by @danielhanchen in #14626
- perf(studio): prefill MLX loads in the planned step while experts are on disk by @Lyxot in #14466
- tests: keep the fused-NVFP4 env in place after the split-reduction hook override by @danielhanchen in #14789
- FP8 rowwise decode: one multi-row GEMV launch for 2 to 16 tokens by @danielhanchen in #14791
- FP8 block decode: fused act_quant and narrow-N GEMM for 1 to 16 tokens by @danielhanchen in #14792
- RMSNorm kernels: do not specialize on the row count and row stride by @danielhanchen in #14786
- MoE autotune cache: pick kernel configs for the operands' GPU by @danielhanchen in #14751
- Studio: show a checkpoint's training loss when that step also evaluated by @MohammadHijjawi97 in #13879
- Studio Images: run Krea 2 GGUFs on stable-diffusion.cpp on CPU-only hosts by @danielhanchen in #14627
- Studio diffusion: Automatic multi-GPU placement fixes and a placement decision in status by @danielhanchen in #14657
- Studio: size auto-quantised text encoders at the hosted file in the image picker by @danielhanchen in #14735
- GRPO routing replay: prime router formulas before compile and score the PEFT reference without replay by @danielhanchen in #14756
- MoE dW accumulation: fall back when autograd Node hooks can rewrite dW by @danielhanchen in #14759
- Gemma 4 vLLM fallback: check the engine's GPU, not the current one by @danielhanchen in #14778
- Fused preference loss: fall back when lm_head has module backward hooks by @danielhanchen in #14788
- Studio Images: Compare grid (X/Y/Z plot) by @danielhanchen in #14624
- MXFP4 packed Linear: bound the below-sm_80 weight decode by free memory by @danielhanchen in #14784
- Studio diffusion: one host read per guided step in the CFG-batch and CFG-parallel argument checks by @danielhanchen in #14734
- Studio Images: detect v-prediction SDXL fine-tunes from their own config, not their name by @danielhanchen in #14746
- Studio: resolve torchao's int8 GEMM home before the int8 fused install returns by @danielhanchen in #14771
- Studio diffusion: read ROCm from the wheel tag in every fast-path gate by @danielhanchen in #14654
- Studio diffusion: seed dense fp16 denoisers on the default and max tiers from measured peaks by @danielhanchen in #14720
- Studio video: stream-encode Wan clips under the ROCm bf16 VAE decode by @danielhanchen in #14653
- MoE grouped GEMM: skip kernel-info logging work unless debug logging is on by @danielhanchen in #14787
- Studio MLX images: tile the VAE decode when the untiled one would not fit by @danielhanchen in #14796
- QAT: fake quantize Gemma embeddings on the float32 and Accelerate-hooked paths by @danielhanchen in #14702
- FP8 block decode: weight-only GEMV where it beats the block GEMM, fused small-M called directly by @danielhanchen in #14813
- Studio MLX images: convert Q4_K / Q5_K / Q6_K and Q5_0 / Q5_1 GGUFs by @danielhanchen in #14794
- Studio MLX images: plan text encoder and dense bits from the Metal working set by @danielhanchen in #14793
- Studio: cap Pillow below 13 for the MLX image engine by @danielhanchen in #14802
- Studio tests: pin the card name in the learned-peaks store fixture by @danielhanchen in #14804
- Studio diffusion: fast whole-component swap for low_vram offload by @danielhanchen in #14767
- Fused LoRA: fall back to PEFT for variants, disabled or merged adapters, trainable bases and autocast dtype mismatches by @danielhanchen in #14806
- Attention: let the SDPA GQA probe trace under torch.compile(dynamic=True) by @danielhanchen in #14779
- FSDP2 NF4 saves: stage packed bytes on the CPU, restore QuantState on full DCP load by @danielhanchen in #14739
- Studio tests: compare MLX snapshot paths as paths, not posix strings by @danielhanchen in #14809
- Studio tests: skip the two-card fast pin test on ROCm instead of erroring by @danielhanchen in #14618
- Apply the repo formatter to 26 files merged without it by @danielhanchen in #14817
- Studio MCP: drop a queued video's request and caller once it settles by @danielhanchen in #14825
- Studio images: keep the resident GGUF's base repo on Reapply and native reload by @danielhanchen in #14828
- Studio video: keep the stream encode hook out of a compiled VAE decode graph by @danielhanchen in #14822
- Studio: restore a kept media model's price after a failed replacement by @danielhanchen in #14826
- Format test_video_stream_encode.py, merged without the repo formatter in #14822 by @danielhanchen in #14852
- Studio diffusion: onload torchao int8 / fp8 weights through the pinned chunks by @danielhanchen in #14832
- Studio: pick the vision projector precision per device, and never F16 for MiMo-VL by @danielhanchen in #14679
- Studio MLX images: list Q5_0 / Q5_1 in the unsupported GGUF refusal by @danielhanchen in #14839
- Studio diffusion: hold cudnn.benchmark off for FLUX.2 klein so a seed decodes the same image in every process by @danielhanchen in #14770
- Studio: budget HunyuanImage-2.1's automatic int8 text encoder at its hosted file by @danielhanchen in #14833
- Studio: hold the image render slot while a cold FLUX.3 upsampler start comes up by @danielhanchen in #14830
- Studio: API keys can't make a Data Recipe read credentials from the server environment by @danielhanchen in #14699
- Studio: only trust llama-server's /health when our own child holds the port by @danielhanchen in #14706
- Fix Gemma 4 E2B / E4B DPO CheckpointError after the ref adapter switch by @danielhanchen in #14705
- Studio: fetch VLM dataset row image URLs through the SSRF-guarded fetch by @danielhanchen in #14701
- GPT-OSS template: keep earlier answers on the final channel when the turn has thinking by @danielhanchen in #14700
- Studio MLX images: release MLX's buffer cache after each generation by @danielhanchen in #14795
- Studio diffusion: keep the CFG-parallel weight probe inside large inference weights by @danielhanchen in #14844
- Studio Images: run the Hires fix latent encode where an offloaded SDXL VAE computes by @danielhanchen in #14851
- Studio: read the prequant source etag from the repo blob under the shared Hub blob store by @danielhanchen in #14819
- Studio updater: install a matched unsloth + unsloth-zoo pair when the index lags by @danielhanchen in #14834
- Desktop: keep the environment when WEBKIT_DISABLE_COMPOSITING_MODE=0 leaves compositing on by @danielhanchen in #14837
- Studio browser: keep a temporary chat's hidden pages out of history by @danielhanchen in #14855
- Studio diffusion: latch the CFG-batch verdict per load and across processes so a seed keeps one path by @danielhanchen in #14849
- Format two files merged without the repo formatter in #14834 and #14819 by @danielhanchen in #14878
- Studio: account management needs a UI session by @danielhanchen in #14872
- Studio diffusion: free the failed group offload setup before the OOM retry by @danielhanchen in #14821
- Studio: Install Training button in the Train hint and the Export banner by @danielhanchen in #14861
- Tests: name text encodings and gate CUDA skips on has_real_cuda by @danielhanchen in #14871
- Studio diffusion: compile MiniMax-H3 with torchao float8 weights by @danielhanchen in #14621
- Studio H3: let Auto residency see the card again on ROCm and NVIDIA without nvidia-smi by @danielhanchen in #14820
- Studio diffusion: pool SDXL textual inversion prompts at EOS by @danielhanchen in #14846
- Studio: flag a modules.json folder of only dots and slashes that leaves the model by @danielhanchen in #14527
- Studio: a mermaid style statement after a semicolon or mid-line cannot fetch either by @danielhanchen in #14526
- Studio: refuse a chained dataset media path whose first hop is not an archive by @danielhanchen in #14529
- Studio: chat audio's librosa fallback refuses playlists too by @danielhanchen in #14530
- Studio: a managed account's own Hub token covers a resident loaded from the Hub cache by @danielhanchen in #14533
- Studio: read every forwarded header field behind a trusted proxy by @danielhanchen in #14534
- Studio: approved host calls keep chat-installed packages, helper modules and CLIs by @danielhanchen in #14543
- install.sh: repair a stale ROCm-on-WSL drop-in without an interactive password prompt by @danielhanchen in #14641
- Studio: let the browser agent follow search-result redirect links shown on the page by @danielhanchen in #14642
- Desktop: write the Windows login entry for the current user only by @danielhanchen in #14643
- Studio: Data Recipe column names with a slash run again; the validator file name is made safe instead by @danielhanchen in #14644
- Studio: registered model folders and HF cache on /run/media drives stay silent for the owner by @danielhanchen in #14646
- Desktop: reject the compromised eMudhra/emSign intermediates (rustls-webpki 0.103.16) by @danielhanchen in #14879
- Studio and Core: certifi 2026.10.19 and pip 26.2.2 floors (drop the compromised emSign root) by @danielhanchen in #14887
- Studio diffusion: store request peaks for Wan pipelines with an empty transformer_2 slot so measured residency runs by @danielhanchen in #14864
- FP8 per-tensor / rowwise dequant: one Triton pass over the e4m3fn bytes by @danielhanchen in #14886
- Format two files merged without the repo formatter in #14821 and #14886 by @danielhanchen in #14885
- Studio NVFP4: tag the compile cache key with the one-pass activation quantiser so a warm cache cannot bypass its switch by @danielhanchen in #14853
- Studio sd.cpp: load a cached earlier text encoder quant when the BF16 default cannot be fetched by @danielhanchen in #14862
- Studio: use a cached earlier FLUX.3 upsampler quant when the default is missing by @danielhanchen in #14842
- Studio: install the dataset image URL guard when datasets loads, not at startup by @danielhanchen in #14888
- Studio: MOSS-Image (in-tree port, quantised builds, GGUF through stable-diffusion.cpp) by @danielhanchen in #14552
- Studio diffusion: stop flushing the CUDA allocator on every prompt encode under block offload by @danielhanchen in #14777
- Studio sd.cpp: stage server-mode image LoRAs as hard links so sd-server lists them by @danielhanchen in #14860
- Studio diffusion: stop recording CUDA graphs once the VMM arena has failed, and detach it by @danielhanchen in #14867
- Keep Gemma 3n AltUp coefficients out of on-the-fly 4-bit quantization by @danielhanchen in #14729
- Load Qwen3-ASR checkpoints saved in the qwen-asr package layout by @danielhanchen in #14716
- Fine-tune Whisper, Canary, Moonshine, CTC, audio classification, Dia and Higgs Audio through FastModel by default by @danielhanchen in #14744
- Load VibeVoice-ASR, MusicGen, Audio Flamingo 3 and Music Flamingo through FastModel by @danielhanchen in #14781
- XPU bf16: judge the XPU in use, not every visible one by @danielhanchen in #14769
- gpt-oss bnb 4-bit: probe the checkpoint transformers loads and keep fused expert quant state on save by @danielhanchen in #14740
- Studio Images: Hires fix latent upscale interpolates the base latents directly, as ComfyUI's LatentUpscale by @danielhanchen in #14863
- Studio Images: run ESRGAN upscalers through the spandrel descriptor by @danielhanchen in #14876
- Tests: rewrite the remote_images import in the no-torch format_conversion harness by @danielhanchen in #14903
- Studio: rework the keyboard shortcuts page by @shimmyshimmer in #14896
- Security audit: baseline the pandas 3.1.0 find_stack_level test by @danielhanchen in #14870
- Format two files merged without the repo formatter in #14769 by @danielhanchen in #14908
- Studio ROCm: keep stored flash-attention verdicts from recompiling per bucket, and gate the CFG replica too by @danielhanchen in #14869
- Fetch get_statistics repos concurrently so from_pretrained does not wait on four HF round trips by @danielhanchen in #14476
- FP8 per-tensor / rowwise dequant under torch.compile below sm89: one opaque byte-decode op by @danielhanchen in #14913
- Studio: hover label on the composer + button by @shimmyshimmer in #14927
- Studio video: fit per-request residency on the streaming tier and for HunyuanVideo-1.5 by @danielhanchen in #14865
- Studio diffusion: seed FLUX.2 klein residency from its measured peak on the first load by @danielhanchen in #14866
- Studio Images: Compare grid counts Hires CFG when sending the negative prompt and records Hires settings by @danielhanchen in #14875
- FSDP2 QLoRA merged saves: stage the packed 4-bit base on the CPU and merge one layer at a time by @danielhanchen in #14823
- Studio: steadier run settings controls, grey sliders, 18px thumbs by @shimmyshimmer in #14926
- Format four files merged without the repo formatter in #14913 and #14823 by @danielhanchen in #14930
- Installers: pin uv 0.13.5 and replace uv older than 0.13.4 (emSign root) by @danielhanchen in #14894
- Studio: tell websites the macOS browser panel is Safari by @NilayYadav in #14797
- Studio Images: keep v-prediction detection on cache-only SDXL loads by remembering the online markers per snapshot by @danielhanchen in #14873
- Studio: horizontally scroll long API usage examples by @NilayYadav in #14798
- Studio: list imatrix-weighted quants named --imatrix.gguf by @danielhanchen in #14931
- Studio: remove the New badge from the Browser settings tab by @shimmyshimmer in #14939
- Large head attention: keep CUDA graph capture off the mask scan and bound int32 row offsets by @danielhanchen in #14790
- GRPO: sync LoRA weights to TRL's own vLLM engine on TRL < 0.28, refuse quantized bases by @danielhanchen in #14831
- Native FSDP2: keep accelerate FSDP2 for custom Accelerator loops, support unsharded generation on torch 2.6 / 2.7 by @danielhanchen in #14882
- Keep the checkpoint_skip_layers="auto" planner out of torch.compile regions by @danielhanchen in #14928
- Studio: gate saved Connection keys on a stamped key purpose, not the key name by @danielhanchen in #14824
- FP8 block dequant on gfx11 ROCm: ragged / rectangular e4m3fn blocks take the byte decoder by @danielhanchen in #14936
- Studio: model picker hides empty uploads and fades models this device cannot run by @shimmyshimmer in #14935
- Studio: save sampling defaults per model and use them for API requests by @danielhanchen in #14515
- Keep HTML previews visible when requesting edits by @NilayYadav in #14810
- FP8 gfx11 byte decoder: tighten comments from #14936 by @danielhanchen in #14947
- Studio chat: go back to a chat's model when it is still loaded by @debojyoti-dev in #14568
- Studio: one fixed radius scale, applied to the shared primitives by @shimmyshimmer in #14919
- Studio: preserve conversation archive order for turns with attachments by @oobabooga in #14768
- Fix delayed playback of generated audio by @Imagineer99 in #14671
- Studio: raise the chat template limit from 64 KiB to 512 KiB by @danielhanchen in #14934
- DiffusionGemma: build the prefix cache per DataParallel replica by @danielhanchen in #14942
- Attention: keep packed fp32 on one xformers call, read the fp32 downcast from Q's device by @danielhanchen in #14805
- Studio: pin managed dataset media URLs to the Hub and scope extracted archive members by @danielhanchen in #14840
- Tests: follow the radius scale in the titlebar and remote access contracts by @danielhanchen in #14957
- Check the weight index of dot-named Sentence Transformers module folders by @danielhanchen in #14952
- Format dataset_media.py, merged without the repo formatter in #14840 by @danielhanchen in #14963
- CodeQL: run weekly and on dispatch only by @danielhanchen in #14953
- Studio: reuse Model Hub filter metadata between searches by @alkinun in #14265
- fix(export): pass trust_remote_code for checkpoint exports by @ryder777777 in #14722
- Studio (Windows): pair a kept torch 2.12 with triton-windows 3.7 by @danielhanchen in #14684
- Studio: keep causal-conv1d for Qwen3.5 / Qwen3-Next remote implementations by @danielhanchen in #14685
- Studio setup: keep the extension-free mamba-ssm in the stale kernel check by @danielhanchen in #14687
- Installer (Windows): fall back to the python-build-standalone mirror for uv-managed Python by @danielhanchen in #14686
- Studio (AMD Linux): keep the bundled ROCm runtime when the system ROCm prepend hides the GPU by @danielhanchen in #14933
- Fix centering of audio and music results by @Imagineer99 in #14718
- Studio: simpler API usage examples, and no Pi / Mistral Vibe outbound links by @shimmyshimmer in #14914
- CI: skip Windows, macOS and Tauri jobs on draft pull requests by @danielhanchen in #14971
- Studio: tidy the Logs viewer and let it resize by @shimmyshimmer in #14965
- Studio diffusion: report the split's primary card as the execution device for diffusers ModularPipeline (FLUX.3 on two cards) by @danielhanchen in #14917
- Studio: neutral grey tints instead of green ones by @shimmyshimmer in #14938
- Studio: give Intel XPU Triton a working C++ toolchain on Windows by @debojyoti-dev in #14814
- Studio: no divider above the Live monitor's Detailed view row by @shimmyshimmer in #14972
- Studio: remove unused image assets by @shimmyshimmer in #14967
- Pin FastFlowLM v1.0.10 by @danielhanchen in #14978
- Studio: keep renamed audio.cpp options at generation time by @danielhanchen in #14901
- Studio: drop file toolbar controls that repeat a visible button by @shimmyshimmer in #14976
- Studio: trim file toolbar comments by @shimmyshimmer in #14980
- Load and QLoRA-train Moonshine Streaming checkpoints by @danielhanchen in #14945
- Studio: attach duplicate-named text files like LICENSE(1), and say why a file can't be attached by @shimmyshimmer in #14977
- Studio: stop the macOS desktop app typing stray control characters for unhandled keys by @debojyoti-dev in #14815
- Unsloth Studio: browser use fixes and clearer agent progress by @shimmyshimmer in #14681
- Studio diffusion: CFG-parallel router keeps the wrapped forward's signature (FLUX.3 under CFG-parallel) by @danielhanchen in #14918
- Studio: show when a chat is waiting for tool approval by @oobabooga in #14877
- Tests: stub _unmerge_flags_on_error in the merged hub destination harness by @danielhanchen in #14961
- FP8 e4m3fn scale dequant: pass enable_fp_fusion like every other launch by @danielhanchen in #14969
- Studio: dataset image guard keeps owner flows working (opt-in, WSL paths, unencoded spaces) by @danielhanchen in #14966
- Studio diffusion: record each card's CUDA graphs on its own capture stream, so compiled renders on a second GPU are correct by @danielhanchen in #14915
- Studio: let HTTP/SSE MCP tool calls run for the whole Max Tool Call Duration by @SauravBellam in #14308
- Studio: keep turns an external provider's compaction drops searchable by @debojyoti-dev in #14731
- Studio: refuse to start Claude Code or OpenCode on a context too small for their own prompt by @NilayYadav in #14799
- Studio sd.cpp: keep sd.cpp's all-CPU thread count on small SMT hosts nothing restricts by @danielhanchen in #14847
- Studio: fix host memory checks and improve logging for GGUF image loads by @VTplus in #14514
- Windows: read safetensors shards with pread on transformers 5.0 - 5.16 by @danielhanchen in #14856
- Studio: split Z-Image guided steps only while the denoiser is compiled or replaying graphs by @danielhanchen in #14868
New Contributors- @ATAMAH made their first contribution in #14098
- @ShryukGrandhi made their first contribution in #14304
- @keyiyu0331 made their first contribution in #13668
- @cedric66 made their first contribution in #11813
- @yejonz made their first contribution in #13987
- @SIDDARTHAREDDY8 made their first contribution in #13748
- @tompipe made their first contribution in #14548
- @Shooter3k made their first contribution in #13427
- @roydonsequeira made their first contribution in #14222
- @ryder777777 made their first contribution in #14722
- @SauravBellam made their first contribution in #14308
- @VTplus made their first contribution in #14514
Full Changelog: v0.1.909-beta...v0.1.910-beta |
Post a Comment/Report Broken Link: