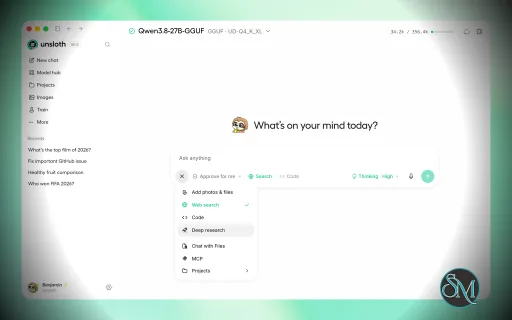
Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.917-beta - Software Mirrors |
|---|
Unsloth v0.1.917-beta for WindowsUnsloth-Desktop-Windows.exe | 20.78 MB Unsloth-Desktop-Windows-ARM64.exe | 20.16 MB |
Unsloth v0.1.917-beta for macOSUnsloth-Desktop-MacOS.dmg | 21.28 MB |
Unsloth v0.1.917-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 22.64 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 22.39 MB Unsloth-Desktop-Linux.AppImage | 169.68 MB |
Others Download related to Unsloth v0.1.917-betaUnsloth-Desktop-ARM64.app.tar.gz | 21.04 MB |
Unsloth v0.1.917-beta Source Code
Unsloth v0.1.917-beta Source code (zip)
Unsloth v0.1.917-beta Source code (tar.gz)
|
Unsloth v0.1.917-beta Release Notes: Qwen3.8-27B is here with Dynamic v3.1 GGUFs, ready to run locally with Unsloth. This release also brings major performance improvements, smoother Glass rendering, revamped code blocks and Thinking UI, HTML/PDF chat exports, and new image generation and coding agent features.
Highlights
- New Qwen3.8-27B Dynamic v3.1 GGUFs.
- Faster chats: Major performance improvements to streaming, scrolling, menus and dialogs, especially in long conversations.
- Smoother Glass: Reduced lag while typing, scrolling and generating.
- Revamped code blocks and Thinking: Independently scrolling, expandable panels with improved syntax highlighting.
- HTML and PDF exports: Export chats directly from the chat menu.
- Image queue: Queue upcoming image generations while another is rendering.
- Claude Code and Codex on MLX: Run coding agents with MLX models through
unsloth start.
Chat & UI
- Streaming performance no longer degrades as conversations grow.
- Smoother scrolling with background images, with or without Glass.
- Faster menus, dialogs and browser pane loading.
- Read aloud starts after the first sentence instead of waiting for the entire response.
- Chat preferences, time format and spell check now sync with your account.
Images & Video
- FLUX.2 and FLUX.3 use 36–43% less VRAM during image decoding at the same speed.
- Queue image generations from the Images page or API.
- INT8 and FP8 image models now load on older NVIDIA GPUs, including T4.
- Fixed black image outputs with FLUX.3.
- LTX-2.5 FP8 now runs on 24 GB GPUs.
- Cosmos3-Nano can continue video clips from their first or last frames.
Coding Agents & API
- Run Claude Code and Codex with MLX models on Mac using
unsloth start.
- New Unsloth MCP preset lets coding agents access Unsloth tools.
- Claude API models without an explicit token limit no longer stop at 1,024 tokens.
- MLX models now return a proper context-length error instead of an empty response.
Training
model.generate() is now 2–8x faster on T4 GPUs by default across FastModel models.
- Video columns are now correctly supported when training vision models.
- Ulysses context parallelism now supports Kimi-Linear, DeepSeek, MiniMax and Gemma 4 text models.
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.11.3 by @danielhanchen in #16920
- Studio GGUF: keep the stock Q8_0 forward on torch below 2.7 by @danielhanchen in #16911
- Studio: merge LoRA and LoKR adapters into ComfyUI-quantized weights by @oobabooga in #16874
- Studio: restore WebKitGTK offscreen code fences in batches and on any pointer release by @danielhanchen in #16919
- Studio: warm the compile workers and Triton / inductor keys during a load that compiles inline by @danielhanchen in #16918
- Studio: pre-seed the float specialisations of an image load's first compiled render by @danielhanchen in #16917
- Studio diffusion: reuse the early quant probe's result instead of spawning a second child by @danielhanchen in #16910
- Studio: keep Glass fast on WebKit by giving glass surface contents their own layers by @danielhanchen in #16921
- Studio: release a streamed encoder's safetensors mapping once its weights are pinned by @danielhanchen in #16914
- Studio: load long chat history faster on Linux by mounting parked history in larger steps by @danielhanchen in #16924
- Studio: decode escaped spreadsheet text during RAG indexing by @DimitriChrysafis in #16712
- Studio: refuse MLX prompts longer than the served context by @Lyxot in #16821
- Studio: preserve Unicode across continued XLS strings by @DimitriChrysafis in #16713
- Studio: classify MLX repos by name or model-card tag everywhere by @Lyxot in #16883
- Studio: blur the glass Settings dialog on its own layer so scrolling it stays cheap by @danielhanchen in #16942
- Studio CI: long-chat gate measures every interactive area under every appearance mode by @danielhanchen in #16931
- Studio: keep Glass cheap on the Linux app by dropping its live blur except the sidebar's by @danielhanchen in #16957
- Studio: stop menus, sidebar and browser pane from restyling the whole chat by @danielhanchen in #16938
- Studio: stop WebKit restyling the whole page when dialogs, menus and the browser pane open or close by @danielhanchen in #16961
- Studio CI: tighten long-chat gate allowances after the :has() rewrite by @danielhanchen in #16978
- Studio: preserve S3 dataset files with colliding names by @DimitriChrysafis in #16830
- Studio CI: long-chat gate measures the dialog lock again before failing by @danielhanchen in #16985
- Studio: stop dialog open and close from rescanning a long chat for every shortcut by @danielhanchen in #16983
- Studio: skip layout of distant messages so the browser pane opens fast on long chats by @danielhanchen in #16986
- Studio diffusion: return the heap a finished image load freed to the OS by @danielhanchen in #16934
- Scan baseline: re-review the seven unsloth-zoo sites 2026.11.3 moved by @danielhanchen in #16922
- CI: run the Playwright WebKit jobs on ubuntu-24.04 while ubuntu-latest is 26.04 by @danielhanchen in #16987
- Studio: ship built-in float specialisations so a fresh install's first compiled render traces once by @danielhanchen in #16939
- Studio diffusion: faster returning first render and first clip (reuse tuned reductions, warm video compile keys) by @danielhanchen in #16981
- Inline images: give a slow sandbox image load a bounded grace and say why it timed out by @danielhanchen in #16923
- Diffusion route tests: pin a compiling host for the tests that expect fp8 to be admitted by @danielhanchen in #16993
- Studio sd.cpp: image render failures carry sd-server's own output by @danielhanchen in #16815
- Studio: show long thinking in a capped box that scrolls on its own instead of Expand thinking by @shimmyshimmer in #16876
- Studio: keep compacted turns searchable when the archive embedder fails by @debojyoti-dev in #16718
- Studio: realtime option for speed and context stats, shorter Chat defaults by @shimmyshimmer in #16888
- Studio RAG: embed the documents of one ingest together instead of one call per document by @debojyoti-dev in #16727
- Studio images: render on the NVIDIA card when torch drives no GPU by @debojyoti-dev in #16853
- Studio CI: long-chat gate Glass ceilings back to 10x (areas) and 18x (Settings scroll) by @danielhanchen in #17003
- Studio: quantise the hosted int8 leftovers on the GPU on offloaded loads by @danielhanchen in #17002
- Studio: start a first video load's cache writes after its first render by @danielhanchen in #17001
- Studio: let unsloth start attach to a loaded Ollama model by @NilayYadav in #16944
- Studio: show DeepSeek Harness as installed on Windows by @NilayYadav in #16954
- Studio: stop OpenAI chats failing on earlier replies sent as parts by @NilayYadav in #16945
- Studio: keep messages from another window when deleting in a stale one by @NilayYadav in #16926
- Studio: size the popular audio.cpp TTS and music models from measured peaks on each runtime backend by @oobabooga in #16984
- Studio: block more metadata host spellings for approved Python by @NilayYadav in #16937
- Studio: offer ChatGPT Reconnect for reused or revoked refresh tokens by @NilayYadav in #16946
- Studio: Agents tab says unsloth start claude needs a GGUF model by @NilayYadav in #16952
- Studio: stop Export all chats from saving an empty or stale backup by @NilayYadav in #16930
- Studio CI: guard the long-chat gate Glass ceilings against runner noise by @danielhanchen in #17012
- Studio: auto-start the server from the same install as unsloth start by @NilayYadav in #16948
- Studio: show an error when ChatGPT sign-in is denied by @NilayYadav in #16950
- Studio: cap chat code blocks at a scrollable height and keep them coloured while scrolling by @shimmyshimmer in #16865
- Studio: stop cutting Claude answers at 1,024 tokens without a limit by @NilayYadav in #16953
- Studio: keep Codex AGENTS.md, skills and rules in unsloth start codex by @NilayYadav in #16947
- CI: key the Playwright browser caches on the OS release, and move the WebKit jobs back to ubuntu-latest by @danielhanchen in #17009
- Studio: reload an idle-unloaded GGUF with its original launch settings by @NilayYadav in #16927
- Studio: keep the base URL query string on connection requests by @NilayYadav in #16951
- Studio: key the modal pointer-lock rules off attributes that never sit above the thread by @danielhanchen in #17006
- Studio: keep same-second fine-tuning jobs in submission order across restarts by @oobabooga in #16835
- Studio: accept zstd-compressed requests from the TypeSafe SDK by @NilayYadav in #16929
- Studio: keep Hermes MCP servers in unsloth start hermes by @NilayYadav in #16949
- Studio: report the LTX-2.5 encoder worker host memory on macOS and Windows too by @danielhanchen in #17014
- Studio: pick which LoRA to add from a searchable list instead of cycling through them by @oobabooga in #16964
- Run Claude Code and Codex on MLX models by @Lyxot in #16811
- Studio: hide the Model hub list under an open model page by @danielhanchen in #17021
- Tests: let the install damage and reinstall hint tests run on Windows by @danielhanchen in #17022
- Studio: keep search icons sharp under the Glass theme on non-chat pages by @debojyoti-dev in #16989
- Studio: keep the first in-loop cut for later tool rounds in chats without a saved thread by @NilayYadav in #16936
- Unsloth Studio: keep tabs signed in on plain-HTTP origins when two refresh at once by @LeoBorcherding in #16755
- Studio: keep chat, time format and spell check settings per account by @NilayYadav in #16958
- Unsloth Studio: shorter new-architecture dialog, one Update button, custom code under Other by @LeoBorcherding in #16966
- Studio: refuse sandbox connects to cloud metadata addresses at runtime by @danielhanchen in #17024
- Unsloth Studio: LFM3 spoken replies and read aloud on the transformers backend by @LeoBorcherding in #16972
- Studio: switch light and dark without starting a transition on every element under Reduce motion by @LeoBorcherding in #16977
- Unsloth Studio: read aloud starts speaking after the first sentence instead of after the whole reply by @LeoBorcherding in #16955
- Unsloth Studio: AMD: skip LFM3's Triton conv and flex attention on ROCm cards Triton cannot build for by @LeoBorcherding in #16974
- fix(studio): heal tool calls in the model's own format on the in-process route by @Lyxot in #16824
- Unsloth Studio (AMD): retry an unpinned llama-server arch crash on the cards the build has kernels for by @LeoBorcherding in #16513
- Block Swap blocker: offload_layers never engages on Qwen3.8-Flash-Next, the CPU-kept n-gram table makes the map look like two devices by @LeoBorcherding in #15633
- Studio: memory-map an oversized load on an integrated GPU and read its lookup tables from disk by @oobabooga in #16857
- Studio: answer shortcut availability checks from registered surfaces, not the whole document by @danielhanchen in #17005
- Unsloth Studio: Cosmos3 guardrail refusal names the gated nvidia/Cosmos-1.0-Guardrail repo by @LeoBorcherding in #16742
- Studio: stream the LTX-2.5 text encode on the card under a VRAM budget, no per-prompt encoder copy back by @danielhanchen in #17000
- Unsloth Studio: show why a video generation failed instead of only "Video generation failed." by @LeoBorcherding in #16744
- Tests: update two contract tests that #16953 and #16927 left red on main by @danielhanchen in #17040
- Unsloth Studio: train and export LFM3-Audio-2B (LoRA, merged 16-bit, GGUF) by @LeoBorcherding in #16973
- Studio diffusion: race the unlisted-arch int8 GEMM tiles held under load (RTX 3090 class: Qwen-Image-2.1 -10%, MiniMax-H3 -9%) by @danielhanchen in #17026
- Studio: name the Cosmos guardrail module outright so the risky-loader lint passes on main by @danielhanchen in #17041
- Tests: let the RAG re-embed and embedder alias tests run on macOS and Windows by @danielhanchen in #17037
- Unsloth Studio / Desktop: the Images page Compare grid, for API callers (server-rendered X/Y grid, no UI change) by @LeoBorcherding in #15169
- Studio: Live monitor with CPU, memory and per-GPU rows, Unsloth's share by model, and a refresh rate by @LeoBorcherding in #15630
- Studio int8 GEMM: keep sm8x GPUs on cuBLAS under Triton 3.8+, where every shipped tile spills by @danielhanchen in #17036
- Studio: auto runs compiled int8 W8A8 for Qwen-Image families on RDNA by @danielhanchen in #17013
- Studio int8 GEMM: read and write the tile race cache as UTF-8 by @danielhanchen in #17044
- Refuse fp8 training layers under tensor parallel instead of silently training in 16 bit by @danielhanchen in #16881
- Context parallel: Unsloth's fast Mistral, Granite and Cohere attention, and DPO / GRPO on fast Qwen3 by @danielhanchen in #16893
- Studio tests: drain deferred work before the auth refresh fixture restores window by @danielhanchen in #17055
- TP x FSDP2 save: one writer when only tp-mesh DTensors remain by @lonexreb in #15257
- Tensor parallel sharded loading: allow init_lora_weights = "orthogonal" by @lonexreb in #15218
- ORPO / CPO / DPO / KTO chunked head: fall back under torch's global module hooks by @lonexreb in #15259
- Studio diffusion: decode image VAEs into one expandable allocator segment (SDXL holds 1.15 GiB less VRAM) by @danielhanchen in #17045
- FSDP2 sharded loading: allow orthogonal LoRA init by @danielhanchen in #17038
- PPO / RLOO fused log-probs: fall back under torch global module hooks by @danielhanchen in #17043
- Context parallel: Ulysses for Kimi-Linear (KDA + MLA), and fix Kimi-Linear MoE gate backward by @MegaGimen in #15880
- GRPO: score a hooked output head through its own forward by @danielhanchen in #17050
- Tests: skip the compiled half of the fp8 codes layer test on Windows without MSVC by @danielhanchen in #17073
- Studio diffusion: Automatic CFG-parallel no longer refuses an idle card over its own CUDA context by @danielhanchen in #17057
- Context parallel: register the Qwen3.5 hybrid cp x native FSDP2 cell, add coverage tests by @danielhanchen in #17039
- Studio: offloaded native int8 denoisers release their safetensors file once pinned (LTX-2.5 holds ~23 GiB less host mapping) by @danielhanchen in #17065
- Studio tests: keep two Linux-host assumptions off the Windows and macOS legs by @danielhanchen in #17107
- Studio tests: skip pre-quant tests without torchao and pin the Mac memory reading by @danielhanchen in #17117
- Studio MiniMax-H3: run int8 / fp8 denoisers where torchao's runtime does not (Ampere fp8, ROCm, MPS) by @danielhanchen in #17064
- Studio: widen stored fp8 / int8 weights without full float32 temporaries by @danielhanchen in #17068
- Studio: keep nvfp4 / mxfp8 layers packed when no native runtime runs them by @danielhanchen in #17067
- Studio sd.cpp: pass the Windows core count to MiniMax-H3 when sd.cpp would halve it by @danielhanchen in #17089
- Studio: AUTO W8A8 on ROCm RDNA keeps bf16 when the int8 plan still offloads by @danielhanchen in #17104
- Context parallel: Ulysses for MiniMax (M1 Lightning hybrid, M2) by @MegaGimen in #15881
- Studio sd.cpp: pick the Q8_0 BF16 cuBLAS route from the diffusion GGUF, not its companions (1.57x on A100) by @danielhanchen in #17098
- Backend CI: retry the ruff-unsloth wheel install on a release-asset 504 by @danielhanchen in #17130
- Studio tests: keep the multi-GB fake checkpoints sparse on Windows by @danielhanchen in #17119
- Studio diffusion tests: plan as Linux does whatever the host can compile by @danielhanchen in #17135
- Studio tests: import the new test helpers top-level when a sibling imports the module that way by @danielhanchen in #17139
- Studio: run single-file fp8 on torchao under group offload, and keep Qwen-Image-2.1's timestep table in fp32 by @danielhanchen in #17127
- Studio: read GPU metadata from the CUDA driver API, not torch.cuda.get_device_properties by @danielhanchen in #17120
- Studio video: spool encoded stream chunks instead of holding a second raw clip by @danielhanchen in #17066
- Studio MiniMax-H3: reuse the conditioner output when only the seed of a reference / keyframe render changes by @danielhanchen in #17094
- Studio desktop: steady floating browser window on drag, resize and float by @shimmyshimmer in #17027
- Studio: keep the lora_adapter_metadata strength of a rewritten LoRA file by @danielhanchen in #17088
- Unsloth Studio: train video-capable VLMs on a dataset's video instead of dropping it by @LeoBorcherding in #16965
- GRPO PrefixGrouper: engage only when the model's forward applies prefix_seg_info by @danielhanchen in #17058
- Studio: skip QKV fusion when projections are kept packed by @danielhanchen in #17132
- Studio: streamed torchao weights no longer crash after a compile (Cannot swap t1 ... weakref) by @danielhanchen in #17141
- MoE DDP negative control: accept the idle rank's missing gradient, whichever rank fails first by @danielhanchen in #17151
- Studio Qwen-Image-2.1: reuse an unchanged condition image's VAE latents across renders by @danielhanchen in #17092
- Studio: no strip behind Back to Hub over a background image by @shimmyshimmer in #17152
- Studio: keep fp32 timestep and RoPE tables in fp32 on single-file loads by @danielhanchen in #17142
- Studio LTX-2.5: one denoiser lease per CFG request, upload the next streamed encoder layer while this one runs by @danielhanchen in #17123
- Studio SSM kernels: read the loaded torch build instead of a torch-import child per load by @danielhanchen in #16996
- unsloth chat: parse the streamed Markdown when a frame is drawn, not on every chunk by @danielhanchen in #16994
- Studio cached models: keep parsed README front matter per unchanged file by @danielhanchen in #17034
- Studio VLM conversion: fetch repo image files on a pool, settle rows in order by @danielhanchen in #17029
- Deep Research: keep a clean attachment inventory clean when inserting the terminal fallback by @danielhanchen in #16997
- Studio diffusion runs: keep a passing full-load verdict per unchanged bundle for the run listing by @danielhanchen in #17033
- Studio: load the chat runtime on use instead of in the startup bundle by @danielhanchen in #16999
- Studio /v1/embeddings: count tokens in one batch and serialize float rows with tolist by @danielhanchen in #17030
- Studio downloads: skip the GGUF requirement lookup on scoped progress polls by @danielhanchen in #17028
- Studio chat: skip the transcript read when no message recorded a context fit by @danielhanchen in #16995
- Studio tool output: strip ANSI in plain runs and find the tail without splitting the whole text by @danielhanchen in #16998
- Studio llama.cpp: remember the positive reasoning budget probe per binary by @danielhanchen in #17031
- Unsloth Studio / Desktop: queue image generations from the Images page and the API by @LeoBorcherding in #15005
- Unsloth Studio: refuse Cosmos3 on diffusers 0.39 and 0.40 instead of failing at load or generate by @LeoBorcherding in #16745
- Studio: each model's compile bundle holds only its own artifacts by @danielhanchen in #17110
- Studio RAG: clip re-embedded chunks and embeddings API inputs with batched token counts by @danielhanchen in #17032
- Studio: packed nvfp4 / mxfp8 layers follow a module dtype cast by @danielhanchen in #17131
- Studio: run FLUX.3 in float32 on fp16-only GPUs (T4 renders were black) by @danielhanchen in #17124
- Studio: bit-identical one-kernel RoPE for FLUX.3 eager attention (L4: -12% s/step) by @danielhanchen in #17136
- Studio CLI tests: keep the --secure re-exec tests off the cloudflared download by @danielhanchen in #17129
- RoPE: rotate Q and K in one launch each way under torch.compile by @danielhanchen in #17109
- Studio: let peft 0.19 attach a LoRA to torchao int8 / fp8 weights of quantised single files by @danielhanchen in #17087
- Studio MLX convert: pack 3 / 5 / 6-bit codes from Fortran-order or strided arrays by @danielhanchen in #17082
- Studio diffusion: expandable VAE decode keeps a runtime allocator opt-in and restores the exact settings by @danielhanchen in #17076
- Studio GGUF: load IQ1_S / IQ1_M / IQ2_XXS / IQ2_XS / IQ2_S / IQ3_XXS / IQ3_S on the diffusers path by @danielhanchen in #17071
- Studio: re-merge only the layers of the LoRA adapters whose weight changed by @danielhanchen in #17102
- Studio MiniMax-H3: normalise a reference video one VAE chunk at a time by @danielhanchen in #17096
- Studio LTX-2.5: keep a fixed negative prompt in the encoder cache (refresh entries on a hit) by @danielhanchen in #17138
- Studio diffusion: FLUX.3 modulation heads project once per sample; offloaded Base edits reuse the conditioning streams by @danielhanchen in #17059
- Studio LTX VAE: keep only the open tile band on the card during tiled decode by @danielhanchen in #17060
- Studio text encoders: keep the fp8 storage across a layerwise-cast forward instead of re-casting it by @danielhanchen in #17103
- Context parallel: Ulysses for DeepSeek (V2 / V3 MLA, V3.2 indexer, V4 sink attention) by @MegaGimen in #15882
- Studio: per-tool MCP switches at the end of Settings > Agents by @Etherll in #15629
- Studio diffusion: keep single-file int8 weights as int8 on T4 / pre-Ampere NVIDIA and Intel XPU under offload by @danielhanchen in #17079
- Studio: a denoiser-only LoRA change keeps the cached text embeddings by @danielhanchen in #17105
- Studio: run the int8 / fp8 Triton widen on the operand's GPU by @danielhanchen in #17133
- Studio MiniMax-H3: keep only the conditioner hidden state H3 reads (about 2 GiB less at 4096 tokens) by @danielhanchen in #17095
- Studio: keep the LoRA fuse host backup off integrated GPU pins and inside the host RAM reserve by @danielhanchen in #17086
- Studio video: fall back to the tiled VAE decode when the Linux / macOS CPU allocator refuses by @danielhanchen in #17075
- Studio: queued image generations wait on their own pool, not the default executor by @danielhanchen in #17108
- Studio: judge the compiled ROCm W8A8 linear per card, not once per process by @danielhanchen in #17078
- Studio: let chat call Unsloth's own MCP tools by @Etherll in #15631
- Studio diffusion: pair Qwen-Image-2.1's guidance branches per streamed block by @danielhanchen in #17111
- Studio int8: fused MLPs and v2 Linears quantize their input with the probed one-pass kernel by @danielhanchen in #17114
- Studio: the load prefetch skips chunks already in the page cache and budgets its read buffers by @danielhanchen in #17112
- Studio image postprocess: convert to uint8 in row strips with one float32 copy each by @danielhanchen in #17091
- Studio diffusion: launch the VAE and MOSS Triton kernels on the input's own card by @danielhanchen in #17099
- Studio NVFP4: the protected branch compiles once from a cold decode table and accepts fp16 inputs by @danielhanchen in #17081
- Studio upscaler: normalise seams and finalise uint8 in place on the host result by @danielhanchen in #17083
- Studio GGUF: cast K-quant and legacy weights to bf16 in their own buffer by @danielhanchen in #17080
- Studio MiniMax-H3 VAE: stitch batched decoder tiles into the frame as they arrive by @danielhanchen in #17097
- Studio Sol-H3 VAE: decide window masks from the geometry, build each RoPE table once per decode by @danielhanchen in #17100
- Studio int8 GEMV: wide scale groups tile inside shared memory, a grouped miss no longer demotes per-row Linears by @danielhanchen in #17106
- Studio int8 GEMM: the unlisted-card race switch acts between loads by @danielhanchen in #17084
- Studio FLUX.3: keep bf16 weights as stored on fp16-only GPUs and compute in float32 per layer by @danielhanchen in #17173
- FSDP2 save: compose the writer across equal meshes, not only identical ones by @danielhanchen in #17158
- Studio: run INT8 on T4 and other Turing GPUs instead of refusing it by @danielhanchen in #17167
- Studio Qwen-Image-2.1: encode prompts without the text encoder's unused K/V cache by @danielhanchen in #17118
- Studio Wan fused blocks: one Triton binary per kernel for every sequence length by @danielhanchen in #17101
- Studio: fp8 denoisers on sm_89 no longer hang on the first render (CUDA graph replay under torch < 2.12) by @danielhanchen in #17166
- Context parallel: Ulysses for Gemma 4 text models by @MegaGimen in #15883
- Studio: install FlashInfer's prebuilt kernels into the vLLM engine env by @danielhanchen in #17063
- Studio llama.cpp: the token-count memo renders again on a new day by @danielhanchen in #17090
- Context parallel: Ulysses evidence for gpt-oss (attention sinks, MoE, aux off) by @danielhanchen in #17183
- Studio video: log an automatic text-encoder pick after the load retries its hosted encoder by @danielhanchen in #17093
- Studio tests: make the compiled-wrapper onload test hold its own weakref (follow-up to #17141) by @danielhanchen in #17189
- Studio tests: the two-card compiled W8A8 test judges each card on its own arch (follow-up to #17078) by @danielhanchen in #17195
- Context parallel: patch DPO / GRPO even when context_parallel is imported before the models by @danielhanchen in #17185
- Studio diffusion: reload a released text encoder from its own safetensors files, no snapshot write by @danielhanchen in #17184
- Studio: no header strips on macOS glass or over a plain background image by @shimmyshimmer in #17154
- Backend CI: split the g-r pytest shard into g-l and m-r by @danielhanchen in #17187
- Studio: read the hosted LTX-2.5 int8 checkpoint when the load's own plan offloads the denoiser by @danielhanchen in #17143
- Backend CI: back off for about five minutes before giving up on the ruff-unsloth wheel by @danielhanchen in #17211
- Studio MiniMax-H3: run the text stream once per render, pack the sequence in place, look up the streamed conditioner's vocabulary rows on the host by @danielhanchen in #17203
- Studio diffusion: read the XPU's float64 support from the device (Arc A-series LTX RoPE) by @danielhanchen in #17070
- Studio MiniMax-H3 Sol VAE: free expired Q/K/V slots before building the next, at most two live by @danielhanchen in #17085
- Frontend CI: back off for minutes before giving up on the Bun download by @danielhanchen in #17221
- Studio GGUF: dequantise bit-identical to llama.cpp, rounded once to the compute dtype by @danielhanchen in #17204
- Studio: int8 ConvRot by default for FLUX.2 klein and FLUX.3 klein (LPIPS 0.10 to 0.04) by @danielhanchen in #17209
- Studio diffusion: size CPU / MPS VAE decode tiles from free host memory (CPU 512 px decode 2.1x faster) by @danielhanchen in #17186
- Studio: decode the FLUX.2 / FLUX.3 VAE in row strips (36-43% less decode VRAM, same speed) by @danielhanchen in #17202
- Studio Qwen-Image-2.1: one GEMM for the dense gate + value and Q / K / V projections by @danielhanchen in #17214
- Compiled RoPE: keep per-tensor launches when only Q or K needs a gradient by @danielhanchen in #17205
- Studio MiniMax-H3: keep the whole denoiser forward compilable with the render text cache (follow-up to #17203) by @danielhanchen in #17226
- Studio: keep segment CUDA graphs on unprotected NVFP4 steps by @danielhanchen in #17216
- Studio: run Detailer inpaints on the image-generation pool by @danielhanchen in #17188
- Studio LTX-2.5: auto text-encoder precision loads the hosted int8 ConvRot encoder by @danielhanchen in #17179
- Studio MiniMax-H3: keep the conditioner read capture and tile decode traceable under torch.compile (#17095, #17097) by @danielhanchen in #17190
- Studio compile cache: torch 2.7 keeps reused graphs in saved bundles (follow-up to #17110) by @danielhanchen in #17196
- Studio diffusion: keep a streamed denoiser's blocks resident for the denoise phase, not the whole render (A100 8 GiB Qwen-Image-2.1 -18%, FLUX.3 -21 to -24%) by @danielhanchen in #17207
- Studio FLUX.3 / Qwen-Image-2.1: prompt encodes keep only the hidden states they read by @danielhanchen in #17182
- Studio CUDA graphs: the sm_89 fp8 stream-K guard reads every split card, not only the primary (follow-up to #17166) by @danielhanchen in #17194
- Studio: install FlashInfer 0.7.3 prebuilt kernels for diffusion NVFP4 by @danielhanchen in #17215
- Studio sd.cpp: pin the prebuilt resynced with upstream master-1050 by @danielhanchen in #17148
- Studio: export chats as HTML and PDF by @shimmyshimmer in #17227
- Studio diffusion: keep Qwen-Image-2.1 CFG pairing through its first-render compile by @danielhanchen in #17177
- Studio LoRA fuse: charge the host RAM guard what the pinned backup really holds by @danielhanchen in #17191
- Studio FLUX.3 manual cast: keep LoRA adapters at the fp32 compute dtype and out of the bf16 fold by @danielhanchen in #17201
- Studio: give each rotated native int8 Linear its own ConvRot buffer (FLUX.3 INT8 on T4 failed its first render) by @danielhanchen in #17217
- Studio FLUX.3: run attention in float16 on fp16-only GPUs (T4: -15% per image GGUF, -34% INT8) by @danielhanchen in #17223
- Studio FLUX.3 on fp16-only GPUs: an explicit INT8 / FP8 quant reads the bf16 checkpoint as stored instead of widening the transformer to float32 by @danielhanchen in #17228
- Studio FLUX.3: price float32 compute on fp16-only GPUs from the measured activation table (x2), so a GGUF Q4 denoiser stays resident on a T4 by @danielhanchen in #17219
- Studio FLUX.3: keep reference-image modulation at one row per span in the joint blocks by @danielhanchen in #17181
- Studio Qwen-Image-2.1: encode a condition image again after load_state_dict(assign=True) on its VAE by @danielhanchen in #17197
- Tool activity gate: wait for each card to open before reading it, not a fixed sleep by @danielhanchen in #17234
- Studio: a streamed GGUF denoiser's top-level weights re-point to their host copy instead of copying back every step (FLUX.3 Q8_0 T4: -11% per image) by @danielhanchen in #17222
- Studio small-host INT8: armed layers compile once (eager-only call counters, follow-up to #17167) by @danielhanchen in #17193
- RoPE: no recompile per sequence length when a compiled backward hands over a seq-major gradient by @danielhanchen in #17212
- Studio FLUX.3: pass cuDNN attention the projections' strided Q/K/V instead of contiguous copies by @danielhanchen in #17180
- Studio diffusion: keep Qwen-Image-2.1 scoped LoRA prompt reuse after the no-K/V wrapper, and key callable helpers fully by @danielhanchen in #17192
- Studio: drop the live Glass blur while anything moves, on software-composited pages by @danielhanchen in #17007
- Studio: stop the autoscroll follow flag restyling the whole thread in WebKit by @danielhanchen in #17035
- Studio: open Settings and the shortcuts list with one panel render and one focus move by @danielhanchen in #17042
- Studio: hold mid-scroll code block work on WebKit, fixing the #16865 scroll regression by @danielhanchen in #17149
- Studio: run FP8 on T4 and other Turing GPUs as weight-only fp8 instead of refusing it by @danielhanchen in #17218
- Studio: stop the Windows Terminal from creating nul files through Git Bash by @danielhanchen in #17010
- Studio: save Image LoRA training settings as presets by @danielhanchen in #17019
- Studio RAG: pause linked-folder indexing while a local chat generates by @danielhanchen in #17018
- Studio LTX-2.5: compact conditioning transport and stage-two connector reuse by @danielhanchen in #17232
- Studio: load INT8 instead of NVFP4 on pre-Blackwell GPUs by @danielhanchen in #17229
- Studio: keep single-file int8 denoiser weights as int8 on CPU instead of expanding them to float32 by @danielhanchen in #17178
- Studio: fuse the int8 ConvRot rotation into its producers on FLUX.2 / FLUX.3 (ConvRot cost +8.7% to +0.5%) by @danielhanchen in #17230
- Studio diffusion: price a streamed Qwen-Image-2.1 edit's reference from its token count, not the flat allowance (A100 8 GiB edit -15%, ahead of the baseline) by @danielhanchen in #17233
- Studio chat: only a note followed by its wrapper starts an attachment by @YakshithK in #16915
- Studio LTX-2.5: use two CUDA cards, the sidecar text encoder priced on its own card by @danielhanchen in #17077
- Condense comments added since the last cleanup: Studio frontend and Tauri by @danielhanchen in #16109
- Condense comments added since the last cleanup: installers, scripts and CI by @danielhanchen in #16112
- Studio update: stop size-checking the managed Windows launcher by @debojyoti-dev in #16901
- Studio MiniMax-H3: keep the released bf16 denoiser resident beside a streamed conditioner on ~100 GB cards by @danielhanchen in #16877
- Add configurable voice context to reduce Qwen3-ASR memory by @Imagineer99 in #15810
- Fix file drops in new project chats by @Imagineer99 in #14472
- Studio video: run LTX-2.5 FP8 on a 24 GB card by streaming the hosted fp8 DiT instead of refusing it by @danielhanchen in #17238
- Studio: pause Glass blur through bursts of keys and presses under software compositing by @danielhanchen in #17237
- Condense comments added since the last cleanup: Studio backend by @danielhanchen in #16110
- Condense comments added since the last cleanup: core, CLI and tests by @danielhanchen in #16111
- [Feature] Unsloth Studio / Desktop: let the mic send audio straight to any audio-input model by @LeoBorcherding in #16976
- Studio: bake the blurred chat wallpaper once instead of re-running the blur on every scroll frame by @danielhanchen in #17253
- gloo-tp tests: a rank that finished is not failed by an abort in interpreter teardown by @danielhanchen in #17244
- Studio ROCm layer split: probe secondary cards read-only, at the attention dtype by @danielhanchen in #14655
- Studio ROCm VAE attention: math SDPA in the VAE's bf16/fp16 dtype, not an fp32 upcast by @danielhanchen in #17252
- Studio CFG-parallel: treat an NVFP4 precision-state flip as a cold call so the two branches never compile at once by @danielhanchen in #14854
- Studio: load image / video / text-encoder weights from .safetensors first, reuse a cached .pt / .bin when its sha256 matches the Hub by @danielhanchen in #17061
- Studio tests: stub stt-context when mic-target loads the voice settings store by @danielhanchen in #17293
- Make shared composer drafts opt-in by @Imagineer99 in #16548
- Studio: give FLUX.3's per-mode block stacks their own offload groups (5 GiB L4 int8: -17.6% per image) by @danielhanchen in #17122
- Studio: serve the hosted Wan2.2-A14B int8 pair to an offloaded load as torchao-free W8A8 layers by @danielhanchen in #15240
- Studio diffusion: auto attention keeps native flash SDPA on A100 / L4 class cards by @danielhanchen in #17290
- Studio tests: pin the H3 cached-prequant lookup offline and cover the online twin rule by @danielhanchen in #17309
- Studio diffusion: split the batch across two cards for LTX-2, Chroma, Qwen-Image, HunyuanImage and Krea-2, and pair Cosmos 3 guidance by @danielhanchen in #17278
- Studio tests: skip the FLUX.3 group-offload test where diffusers is not installed by @danielhanchen in #17317
- Studio ROCm: use the measured fastest GEMM solution table for diffusion denoisers on gfx1151 by @danielhanchen in #17299
- Long-chat gate: settle pointer targets before a trusted hover or click by @danielhanchen in #17274
- Long-chat gate: measure streaming a reply into the chat by @danielhanchen in #17269
- Long-chat gate: measure every appearance setting or allowlist it with a reason by @danielhanchen in #17262
- Studio native diffusion: run the text encoders on a second CUDA card when one card cannot hold the load by @danielhanchen in #17276
- Studio diffusion: keep the fused AdaLN census out of compiled FLUX.1 blocks (recompile limit on first render) by @danielhanchen in #17310
- Use one glass surface for the docked Windows browser by @Imagineer99 in #16754
- Studio: title tooltips stop walking the whole thread on every pointer move by @danielhanchen in #17304
- Studio: Glass Settings pane scrolls on the compositor; API monitor fade pauses its blur (software compositing) by @danielhanchen in #17308
- Studio: keep the view_image picture visible when its tool card is collapsed by @keyiyu0331 in #17174
- Studio: stream a reply without re-rendering every message client per token by @danielhanchen in #17305
- Studio: browser pane opens without per-frame thread work on long chats by @danielhanchen in #17282
- Windows install: keep typer below 0.29 so studio setup does not hold pydantic_core open by @danielhanchen in #17319
- Studio ROCm TunableOp: label the results file with the HIP build string, not a raw read by @danielhanchen in #17325
- Studio: colour chat code blocks from the worker while scrolling and streaming by @danielhanchen in #17160
- Studio: key group hover / focus-within / active on the group class (WebKit long-chat menus and dialogs) by @danielhanchen in #17323
- Studio: modal opens stop re-laying out long chats in WebKit by @danielhanchen in #17284
- Studio: WebKitGTK Glass drops the sidebar's live blur and Frosted's grain tile (long-chat scroll) by @danielhanchen in #17327
- Unsloth Studio: restyle a video with Cosmos3-Nano-Sim-Transfer on sd-server by @LeoBorcherding in #16975
- Fix Windows wallpaper titlebar and Transparent glass surfaces by @Imagineer99 in #16959
- Studio CI: WebKit leg for the long-chat gate, report-only paint / CPU length check, recheck gap fixed by @danielhanchen in #17331
- Studio ROCm RDNA int8: Triton W8A8 kernels and fused Qwen-Image-2.1 projections (gfx1151 INT8 -12% per step, explicit int8 -26% to -34%) by @danielhanchen in #17334
- Studio: open the browser pane without React's Suspense reveal hold by @danielhanchen in #17335
- Long-chat gate: block on CPU / paint growth with chat length, judged on fresh-page rechecks by @danielhanchen in #17336
- Studio: share the FLUX.3 joint block int8 ConvRot quant under the span forward by @danielhanchen in #17337
- Studio: reroute only official NVFP4 checkpoints to INT8 on pre-Blackwell GPUs by @danielhanchen in #17343
- Studio FLUX.3: probe strided cuDNN attention on every layer split card by @danielhanchen in #17341
- Studio diffusion: do not let functools.wraps copy the prompt-cache transparent-wrapper marker by @danielhanchen in #17348
- Studio sd.cpp: only block-split on builds whose --auto-fit takes on|off by @danielhanchen in #17346
- Studio ROCm layer split: apply the common SDPA guard only once the split fits by @danielhanchen in #17347
- Studio: an unverified cached .pt no longer demotes the baseline-format safetensors twin by @danielhanchen in #17342
- Studio sd.cpp: send MiniMax-H3 reference video and audio to the resident sd-server by @danielhanchen in #17349
- Studio: glass toast surface for the runtime, Studio and Desktop update cards by @shimmyshimmer in #17352
- Studio: restore ROCm TunableOp state when the last diffusion pipeline unloads by @danielhanchen in #17340
- Studio: compute ROCm VAE half-math SDPA per call instead of flipping the global flag by @danielhanchen in #17350
- Studio sd.cpp: retry an image render that sd-server refused for VRAM under half the budget by @oobabooga in #17339
- Studio: open a long chat at its latest message on Chromium by @danielhanchen in #17351
- Studio: open and close dialogs and menus in long chats without a full thread re-layout on Firefox by @danielhanchen in #17357
- Studio: fit a GGUF reload only after the stopped llama-server's VRAM shows as free by @oobabooga in #17345
- Studio MiniMax-H3: skip the up-front denoiser slab pin when every block will be resident (-16 GiB host peak on A100 40 GB) by @danielhanchen in #17354
- Studio MiniMax-H3: keep conditioner layers on the card beside a resident denoiser, size its host pins to their weights by @danielhanchen in #17355
- Studio MiniMax-H3: park the VAEs when a render returns, so later requests keep their residency budget by @danielhanchen in #17356
- Studio diffusion: keep no pinned host copy of a resident Qwen-Image-2.1 text encoder (L4 host RAM -8.1 GiB, peak RSS 25.3 -> 16.6 GiB) by @danielhanchen in #17359
- Studio sd.cpp: send the simple scheduler so flow families get the diffusers sigma grid by @danielhanchen in #17360
- Studio diffusion: keep a hosted checkpoint's header across processes, so an 8 GiB Qwen-Image-2.1 load skips its FP8 header read (L4 load -1.8 s) by @danielhanchen in #17353
- Long-chat gate: Firefox leg for dialogs, menus, browser pane and typing by @danielhanchen in #17361
- Unsloth Studio: Cosmos3 256p, NVIDIA's frame ranges and a per-model frame-rate picker by @LeoBorcherding in #16737
- Decode CUDA graphs on by default for every FastModel model (2-8x on T4, tokens equal to eager) by @danielhanchen in #16587
- Studio diffusion: price a Qwen-Image-2.1 edit's reference on the group tier so 16 GiB edits stop hooking the resident transformer (L4 first edit -19%, -8.4 GiB host RAM) by @danielhanchen in #17364
- Studio: reuse Windows ROCm Get-Counter readings for display polls like amd-smi by @danielhanchen in #17306
- unsloth CLI: check a Studio pid with psutil before spawning tasklist on Windows by @danielhanchen in #17271
- Studio Images X/Y plot: shrink grid cells off the event loop by @danielhanchen in #17265
- Studio debug logs: list log names instead of building a Path per file on each poll by @danielhanchen in #17302
- Studio library: cache Intl formatters for per-row dates and sizes by @danielhanchen in #17251
- Studio research: run each step's knowledge base and MCP lookups alongside its web search by @danielhanchen in #17287
- H3 rotation park test: read video.py as UTF-8 by @danielhanchen in #17370
- Unsloth Studio: Cosmos3-Nano video continuation (extend a clip from its last or first frames) by @LeoBorcherding in #16741
- Studio: keep the browser feature index out of startup by @danielhanchen in #17280
- Studio: reduce Liquid Glass paint cost when WebKit paints on the CPU by @oobabooga in #16960
- Studio embeddings: parse the GGUF body only when read and once, and serialize the Studio embedder payload off the event loop by @danielhanchen in #17286
- Studio dataset preview: hand a JSON file that is not JSON Lines to the loader without reading it whole by @danielhanchen in #17277
- Studio chat search: skip metadata_json when building the search index batch by @danielhanchen in #17249
- Studio GGUF variants: reuse the request's Hub listing for the MLX fallback by @danielhanchen in #17279
- Studio: skip superseded wallpaper writes and no-op history / bookmark persists by @danielhanchen in #17298
- Studio Windows tools: stop the trusted git lookup at the first trusted candidate by @danielhanchen in #17270
- Studio: memoize the nonce-free Content-Security-Policy on its inputs by @danielhanchen in #17246
- Studio: keep marked out of startup by moving the export format names to their own module by @danielhanchen in #17250
- Studio Data Recipes: keep unstructured seed upload file IO off the event loop by @danielhanchen in #17266
- Unsloth Studio: list Cosmos3-Nano in the Video picker and route it from the Hub by @LeoBorcherding in #16743
- Studio dataset detection: read only the still-missing columns when filling a sparse first row by @danielhanchen in #17248
- Studio: pause display-only training polls while the tab is hidden by @danielhanchen in #17294
- Studio: import HfApi on first use instead of at backend start by @danielhanchen in #17273
- unsloth studio stop: return as soon as the server exits instead of on the next half-second step by @danielhanchen in #17283
- Patch sentence_transformers when it is first imported instead of importing it with unsloth by @danielhanchen in #17267
- Studio Metal: read the Apple wired headroom once per GGUF placement by @danielhanchen in #17275
- Studio chat: skip the display strip chain for history text with no tool markup by @danielhanchen in #17264
- Studio RAG: delete a retired folder's or scope's chunks in batches instead of one index scan per document by @danielhanchen in #17281
- Studio: cache the native-template markup profile per tokenizer in renderable_tool_catalog by @danielhanchen in #17288
- Studio Anima LoRA: rule out kohya splits that name no registered module before probing by @danielhanchen in #17247
- Diffusion guard test: match the calibrated placement and ControlNet kwargs structurally by @danielhanchen in #17376
- Studio: resolve the nested Radix primitive / slot / context copies to one version by @danielhanchen in #17301
- Studio: keep speaker notes when a PowerPoint file is attached in chat by @NilayYadav in #17258
- Studio: keep searching the web past a lone Wikipedia result by @NilayYadav in #17242
- Studio Windows GPU inventory: run the PowerShell adapter scan only when AMD or Intel records need it by @danielhanchen in #17272
- Studio installers: ask for the latest llama.cpp / whisper.cpp release tag once per run by @danielhanchen in #17289
- Studio: read once per tab return instead of on both visibility and focus by @danielhanchen in #17300
- Studio: keep the Ask before downloading programs setting across browsers by @NilayYadav in #17240
- Studio: turn Reduce motion on by default by @shimmyshimmer in #17377
- Skip the duplicate tokenizer load on transformers 5 when it can only copy the fast tokenizer by @danielhanchen in #17318
- Studio: keep a user-set Hermes api_key in unsloth start hermes by @NilayYadav in #17320
- Studio: train Phi-4-mini on its own chat template by @NilayYadav in #17312
- Studio MiniMax-H3: run one denoiser forward per requested step (20 steps ran 19) by @danielhanchen in #17362
- Slot-clamp lint: accept the allow marker on any line of a wrapped assignment by @danielhanchen in #17384
- Fix CPU pipeline evaluation loss normalization by @0xalkinun in #17291
- Studio: keep hidden spreadsheet rows in chat attachments by @NilayYadav in #17314
- Studio: save LoRA and merged exports of a run to separate folders by @NilayYadav in #17260
- Decode CUDA graphs for Qwen3.5 / Qwen3.6 hybrid linear-attention caches by @danielhanchen in #17324
- Studio: stop audio models learning to answer None for blank transcripts by @NilayYadav in #17257
- Studio: hold the login rate limit on the Colab public link by @NilayYadav in #17259
- Studio: end plain-text training rows with EOS when Format is Auto by @NilayYadav in #17255
- Decision models on MLX: refuse a config.json model_file unless trusted by @danielhanchen in #17391
- AsyncGRPO: require a per-run secret on the local vLLM server; validate BF16 AdamW state on load by @danielhanchen in #17390
- Studio: cap request bodies on every route and decode zstd bodies one at a time by @danielhanchen in #17388
- Studio: do not start a queued fine-tuning job for a disabled or deleted account by @danielhanchen in #17392
- Studio: edit_file and Rewind write through an open chat-folder descriptor on POSIX by @danielhanchen in #17389
- Studio: open update-notes links in the Desktop app, treat .term and .tcsh downloads as code by @danielhanchen in #17394
- Long-chat gate coverage: measure forced motion now that Reduce motion is on by default by @danielhanchen in #17395
- Studio: make keyword search find Chinese, Japanese and Korean words by @NilayYadav in #17261
- Studio video: a stored peak no longer widens a new process's first render; an out-of-memory render retries streamed (LTX-2.5 16 GiB returning home) by @danielhanchen in #17373
- Studio: harden diffusion adapters, quant scales, prompt LoRA tags, Hub clips, short audio and restyle uploads by @danielhanchen in #17396
- Settings sync: save the shared composer draft preference with the account by @danielhanchen in #17399
- Notebook GGUF export: keep the converter to the load's trust_remote_code decision by @danielhanchen in #17397
- Bump trufflesecurity/trufflehog in / by @dependabot[bot] in #17243
- Studio: centre dialogs on whole pixels so their text stays sharp by @wasimysaid in #17383
- Studio: fix embedding fine-tunes failing at the first step by @NilayYadav in #17311
- Studio: make MLX and safetensors models call a forced tool by @NilayYadav in #17241
- Studio: say when a file added while creating a project fails to index by @NilayYadav in #17313
- Studio: open the managed account folder browser on symlinked installs by @NilayYadav in #17321
- Studio: remove Liquid Glass stripes and greeting rings, and the black browser tab strip on Linux by @wasimysaid in #17380
- Studio: keep every frame when downloading a video as WebM by @NilayYadav in #17239
- Studio GGUF vision chat: reuse the image normalization for history images sent again by @danielhanchen in #17263
- Studio: ask before Python shells out through asyncio or pty by @NilayYadav in #17254
- Studio: send video to custom OpenAI-compatible connections by @NilayYadav in #17322
- Studio: restore real Glass on the Linux app (live blur, fills, strength and the Windows-style title bar) by @wasimysaid in #17387
- Studio: keep deferred MCP tools in place when a listed tool runs again by @oobabooga in #17326
- [CS146S Stanford] Studio web fetch: a bare & stays as written, and escaped code stays in its code block by @mrityu75 in #17200
- Studio: stop image loads exhausting Windows commit on Intel Arc iGPUs by @danielhanchen in #17378
- Opt-in growable KV cache for generic decode graphs by @danielhanchen in #17296
- GGUF export: keep remote_code_approved out of the save_pretrained kwargs by @danielhanchen in #17404
- docker(rocm): run gfx103X cards as gfx1030 when the image's torch lacks them by @hMelchisedek in #17150
- fix(studio): align cached GGUF picker size by @Aafimalek in #17125
- Remove unreferenced private helpers, constants and an if False block by @danielhanchen in #16569
- Add retry button to download panel for failed/cancelled downloads (CS 146S) by @vijkomal in #17225
- fix(studio): support explicitly selected virtual bridge LAN addresses by @alanhuang05 in #17165
- Studio diffusion: load Qwen-Image-2.1's hosted int8 text encoder on float16 cards (T4 Turbo INT8 82.7 -> 31.9 s/image) by @danielhanchen in #17379
- Studio LTX-2: stream the text connectors under streaming offload so the denoise keeps more transformer groups resident (A100 16 GiB -16% per clip) by @danielhanchen in #17386
- Studio: set scrollbar-color in rgb so Reduce motion stops restarting a transition on every element by @danielhanchen in #17413
- Studio: leave room for thinking in a Custom connection's chat title request (#17332) by @indrajeetapache in #17363
- Installers: require unsloth-zoo>=2026.11.4 to match the pyproject floor by @danielhanchen in #17414
- Installer: clear damaged uv cache entries before retrying an install by @danielhanchen in #17398
- Studio: mount the API monitor inside a host that stays mounted, so opening it in Glass stops restyling the app by @danielhanchen in #17418
- Studio FLUX.3: keep float16 on fp16-only GPUs behind a residual rescale (T4 INT8 -24% per image, GGUF Q8_0 -73%) by @danielhanchen in #17385
- Scan baseline: re-review the seven unsloth-zoo sites 2026.11.4 moved by @danielhanchen in #17421
- Studio: keep more of a streamed FLUX.3 klein int8 transformer resident at small budgets (L4 6 GiB -4.2% per image, H2D 56.9 -> 43.9 GiB) by @danielhanchen in #17419
- Studio MiniMax-H3: feed the SwiGLU halves straight into the down projection's int8 activation quant (L4 -0.85% s/step, bit-identical) by @danielhanchen in #17422
- Update idempotency: let the offline test survive a version bump that is not on PyPI yet by @danielhanchen in #17428
- Studio: ask before running Python fed to Terminal through a heredoc by @NilayYadav in #17256
- Studio tests: read video.py as UTF-8 in the H3 fused SwiGLU test by @danielhanchen in #17437
- Unsloth Studio: show which models have saved run settings and reset them from the model menu by @LeoBorcherding in #12608
- Studio Terminal: give the heredoc quote scanner its own substitution helper by @danielhanchen in #17442
- Studio sd.cpp: pin the prebuilt resynced with upstream master-1056 by @danielhanchen in #17459
- Studio: stop Reduce motion turning on a transition for every element by @danielhanchen in #17466
- Studio NVFP4: tune mm_fp4 once per M bucket and keep the tactics on disk by @danielhanchen in #17467
- Studio: neutral NVFP4 gate field names and refreshed checkpoint hashes by @danielhanchen in #17469
- Studio NVFP4: 4over6 block scales at load and in the prequant builder by @danielhanchen in #17468
- Tests: clear the cached tensor parallel layout before every test by @danielhanchen in #17472
- Studio: MiniMax-H3-Image text to image and reference edits by @danielhanchen in #17453
- Flex attention decode steps for Gemma 4 and Qwen3.5 / Qwen3.6 under decode CUDA graphs by @danielhanchen in #17329
- Studio tests: give the llama-server owner tests a wait cap a loaded runner can meet by @danielhanchen in #17488
- Studio: keep chat text out of the header with Glass or a background by @NilayYadav in #17429
- Studio: ask before Python runs a shell command passed by reference by @NilayYadav in #17456
- Studio: let MCP run_recipe set a row count by @NilayYadav in #17427
- Studio: stop web results crowding attached files out of Deep Research by @NilayYadav in #17434
- Studio: wrap long unbroken text in PDF chat exports by @NilayYadav in #17425
- Studio: make Gemma 4 call a forced tool by @NilayYadav in #17432
- Studio: keep the seeded admin password out of pages relayed by a proxy by @NilayYadav in #17454
- Studio: stop showing a stray after an OpenAI model calls a tool by @NilayYadav in #17455
- Studio: fit max_tokens to the window on vLLM and SGLang tool requests by @NilayYadav in #17426
- Studio: keep the LoRA on in Chat after a Base vs LoRA compare by @NilayYadav in #17433
- Studio: let managed accounts use gated models with their own HF token by @NilayYadav in #17172
- Studio: keep built-in tools on when an MLX chat has several images by @NilayYadav in #17423
- Studio: compact long chats on an Ollama connection to its loaded window by @NilayYadav in #17457
- Studio: reconnect a chat reply whose connection died silently by @NilayYadav in #17416
- Studio: always show loaded GGUF weight placement by @oobabooga in #17449
- Studio MiniMax-H3: opt-in 4-bit GGUF text encoder for hosts that cannot keep int8 resident by @danielhanchen in #17479
- Studio: edit images through an external connection's /images/edits endpoint by @oobabooga in #17448
- Gemma 3 generate test: find the non-flex scope by call, not by its exact text by @danielhanchen in #17497
- Studio sd.cpp: pin the prebuilt with the aarch64 K-quant GEMM and macOS Accelerate routing by @danielhanchen in #17489
- TP / FSDP2 saves: pass results between ranks as JSON, not pickle by @danielhanchen in #15510
- Studio: accept chat videos up to 256 MB by @danielhanchen in #17400
- Context parallel: eval loss is the sequence's token mean, not cp_size times it by @lonexreb in #17049
- Mask GRPO completions cut by the vLLM server's context limit by @danielhanchen in #16650
- Pipeline parallel on the CPU backend: weight the MoE router aux loss as TRL's SFTTrainer does by @debojyoti-dev in #17072
- Ulysses: dynamic and longrope RoPE see the whole sequence's positions by @lonexreb in #17051
- Studio desktop: serve the web UI behind an allowlisted reverse proxy (fixes #17420) by @debojyoti-dev in #17435
- RoPE: compile stock positions without full-context caches by @danielhanchen in #16182
- Studio: train jobs targeting embed_tokens or lm_head alone, not batched by @danielhanchen in #16653
- Multi-LoRA: keep the backward dH buffer in fp32 by @danielhanchen in #16647
- Studio: MLX chats with a picture keep going when the context fills by @NilayYadav in #17424
- Multi-LoRA: refuse 8-bit bitsandbytes base layers by @danielhanchen in #16648
- Studio: no RAM fallback mark in the model picker when there is no GPU by @shimmyshimmer in #17516
- Studio: pin MiniMax-H3-Image (Fast FP8) at the top of the image picker by @danielhanchen in #17502
New Contributors- @MegaGimen made their first contribution in #15880
- @0xalkinun made their first contribution in #17291
- @hMelchisedek made their first contribution in #17150
- @vijkomal made their first contribution in #17225
- @alanhuang05 made their first contribution in #17165
Full Changelog: v0.1.916-beta...v0.1.917-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: