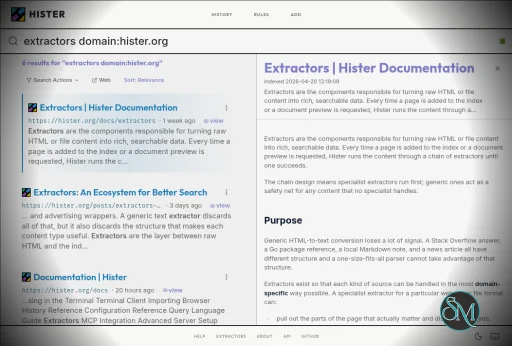
Hister is a free and open-source personal search engine that indexes the contents of web pages and local files so they can be searched later. It runs on infrastructure you control, provides a web interface and terminal search, and can also connect to AI assistants through MCP.
Features
Hister performs full-text indexing rather than searching only page titles and URLs. It can index pages visited through its Firefox and Chrome browser extensions and can also index local directories and imported browser history.
Its search system supports phrases, wildcards, field filters, negation, aliases, and result priorities. This provides more control than a basic keyword search when working with a large personal archive.
Hister also supports optional semantic search through a configurable embeddings endpoint. This allows searches based on meaning rather than exact words, although using a remote embeddings service means document text may be sent to that service.
The software can crawl websites recursively and import existing content. Recent releases have also added unified imports for browser history, local files, bookmarks, and archived content from services such as Linkwarden, Karakeep, and Shaarli.
Hister can be accessed through its web interface, terminal interface, TUI, command line, or an AI assistant using MCP. Multi-user support allows separate documents and search results to be maintained on a shared server.
Download Hister v0.22.0 - Software Mirrors |
|---|
Hister v0.22.0 for Windows |
Hister v0.22.0 for macOS |
Hister v0.22.0 for Linux |
Others Download related to Hister v0.22.0 |
Hister v0.22.0 Source Code |
Hister v0.22.0 Release Notes:Hister Is Now NogonThis is the first release under the Nogon name. The rename follows a trademark complaint about the previous name. Development continues with the same purpose: saving and searching your content on a server you control. Read Hister Is Now Nogon for the background and what the transition means for your installation. The project website is now nogon.eu, and new release downloads usenogon names. The application, terminal client, documentation,
and browser extensions use the new branding. Existing extension installations
receive the rename through their normal store updates and retain their settings.
Nogon reuses existing Hister configuration and data. The rename itself requires
no data move, import, or reindex. Follow the upgrade notes below before replacing
an existing installation.
New FeaturesSettings in the Web InterfaceThe new Settings page edits application preferences, watched directories, indexing, crawler options, extractors, semantic search, hotkeys, and supported server and authentication settings. It shows where values come from, marks unsaved changes, and reports validation errors beside the affected fields. Settings supplied by the main configuration file, environment variables, or startup flags remain locked. Administrator access is required in multi user mode. Save and apply persists web selections without rewriting the main configuration file and briefly interrupts service while applying them. Sensitive changes require review. Connection and authentication changes apply temporarily; reconnect and confirm working access within two minutes. Cancellation, timeout, or restart restores the last confirmed configuration.RSS and Atom Importsnogon import rss FEED_URL imports the full pages linked from an RSS or Atom
feed. Duplicate URLs are queued once, existing documents are skipped unless
--force is supplied, and interrupted imports can resume with
nogon index --job-id JOB_ID. The command runs once and exits; it does not
subscribe to future updates or import text embedded in the feed.
Richer File PreviewsLocal file results open in fullscreen previews with a download action. Code previews include syntax highlighting and a copy button, and plain text keeps its line breaks and indentation. PDF previews show readable extracted text with page divisions when available. DOCX previews preserve paragraphs, standard headings, and basic text formatting. PDF and DOCX previews do not reproduce the original page layout or images.Retained Data Cleanupnogon purge removes selected old document versions, unpinned history, and
completed crawl records before an explicit cutoff. For example,
nogon purge --versions --history --crawl-jobs --before 2026-01-01 --dry
previews the affected counts. Removing --dry asks for confirmation before
deletion. The operation applies across all users and requires administrator
access in multi user mode. Current searchable documents, pinned history, and
unfinished crawls remain intact.
OIDC Administrator GroupsConfigureadmin_groups to manage administrator access through OIDC group
membership, with groups_claim selecting the provider's group field. Each
successful OIDC login grants or removes administrator access according to the
current memberships. Keep an independent local recovery administrator in case
the provider becomes unavailable or revokes access. Leaving admin_groups
unset preserves manually managed roles.
Enhancements
Bug Fixes
(?i) and avoids duplicate rule requests while pages load concurrently.
Backward Compatibility NotesThe following changes require attention when upgrading from v0.21.0:
nogon, or nogon.exe on Windows,
and update scripts, shortcuts, service launch commands, and download URLs.
Windows releases also provide a ZIP containing only nogon.exe. Package
managers may retain Hister names during the transition; follow the
installation guide.
nogon config path and nogon config show with the service's usual
flags and environment. If multiple directories contain stored data, select
the intended one with app.directory or NOGON_DATA_DIR. Keep the same
server URL and credentials in your clients.
NOGON_DATA_DIR, and NOGON_PORT for new configurations. Their Hister
equivalents remain supported. A present Nogon configuration variable takes
precedence over its legacy equivalent, even when empty. Service import
credentials also accept NOGON_IMPORT_ while retaining HISTER_IMPORT_.
--full if scripts require active YAML values. Existing
explicit settings retain their meaning and lock the corresponding web
controls; comment out or remove a setting to manage it through the web page.
create-user, show-user, update-user, and delete-user with
user create, user show, user update, and user delete. These previously
deprecated aliases have been removed.
nogon reindex for watched local files. This is optional and separate from
the project rename.
|
Performance and Compatibility
Hister is written in Go and can run locally or on infrastructure controlled by the user. It supports SQLite and PostgreSQL as database backends, with PostgreSQL support added in version 0.12.0.
The application is designed for continuous personal indexing. Once the server is running, the browser extension can automatically send visited page content to the configured Hister server for indexing.
Hister does not require a cloud service or account for a local personal setup. The project states that it has no telemetry or mandatory cloud synchronization. Indexed documents and search indexes remain on the Hister server.
The current release series also includes features for public search deployments, documentation datasets, and additional import sources. Version 0.17.0 introduced a unified import interface and support for importing content from Linkwarden, Karakeep, and Shaarli.
System Requirements
Hister provides prebuilt binaries for supported platforms, including Windows, Linux, and macOS. The Windows version can be started directly from PowerShell using the hister.exe binary.
For normal use:
Windows, Linux, or macOS
Firefox or Chrome if browser history indexing is required
Storage for indexed documents and search indexes
A local or server environment where Hister can remain running
For building from source:
Go 1.26
npm
C compiler for CGO dependencies
Hardware requirements are not specified as a fixed minimum because resource usage depends on the amount of content being indexed and the selected database and search configuration.
Pros and Cons
Pros
Free and open source
Full-text personal search
Indexes web pages and local files
Firefox and Chrome integration
Browser history import
Website crawler
Powerful search operators
Optional semantic search
Web interface
Terminal and TUI access
MCP support for AI assistants
Multi-user support
No telemetry by default
No mandatory cloud service
Supports SQLite and PostgreSQL
Docker and Nix installation options
AGPLv3 licensed
Cons
Requires running and maintaining your own server
Initial indexing can consume significant storage and processing resources
Semantic search requires an embeddings endpoint
Browser integration requires an extension
More complex to configure than conventional desktop search tools
The AGPLv3 license may require consideration for organizations modifying and redistributing the software
How to Install
Download the Hister binary for your operating system from the project's releases. On Windows, rename the executable to hister.exe if necessary and start it from PowerShell with:
.\hister.exe listenOn Linux or macOS, make the binary executable and start it with:
chmod +x hister
./hister listen
Then open the local Hister web interface at http://127.0.0.1:4433 and install the Firefox or Chrome browser extension. After visiting pages with the extension enabled, their content can be indexed and searched through Hister.
Hister can also be installed using Homebrew, Docker, or Nix. Existing browser history, local directories, and files can be imported after installation.
Final Verdict
Hister is a useful personal search engine for users who want to build their own searchable archive of web pages and files. Its full-text indexing, browser integration, local deployment, advanced queries, semantic search option, and MCP support make it more than a simple browser history search tool.
The main tradeoff is that Hister is self-hosted software. Users need to keep the server running and manage the storage and indexing environment themselves. For users who want a private search index under their own control, that approach provides considerably more control over their data.
Developer:
Adam Tauber
Operating System:
Windows / macOS / Linux
Date Added:
2026-11-19T15:07:22.366Z
Categories:
Post a Comment/Report Broken Link: