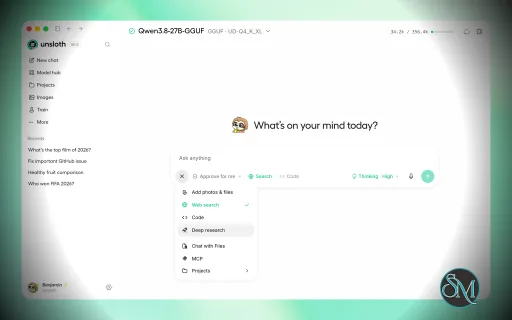
Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.907-beta - Software Mirrors |
|---|
Unsloth v0.1.907-beta for WindowsUnsloth-Desktop-Windows.exe | 22.66 MB Unsloth-Desktop-Windows-ARM64.exe | 22.12 MB |
Unsloth v0.1.907-beta for macOSUnsloth-Desktop-MacOS.dmg | 24.31 MB |
Unsloth v0.1.907-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 26.25 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 26.53 MB Unsloth-Desktop-Linux.AppImage | 172.98 MB |
Others Download related to Unsloth v0.1.907-betaUnsloth-Desktop-ARM64.app.tar.gz | 24.12 MB |
Unsloth v0.1.907-beta Source Code
Unsloth v0.1.907-beta Source code (zip)
Unsloth v0.1.907-beta Source code (tar.gz)
|
Unsloth v0.1.907-beta Release Notes: Unsloth has gotten major performance upgrades!
Highlights
- Large perf gains: all Unsloth UI/UX faster - up to 10x for multiple chats
- Up to 5x faster inference: 95% cache hit rate, MoE Strata style fixes, slowdown fixes
- Better Compaction - works for all API + better UI handling
- Drag and drop files: Desktop works again with more than 3× more supported files
- Browser use with scripts: click, move the mouse, drag, run approved scripts and set per-site browser rules.
- LTX-2.5 + Wan2.2 + Faster image LoRA training: new video generation, image-to-video and faster image training.
- NVIDIA RTX Spark: now supported with our Windows ARM64 downloadables
- Major Unsloth workflow upgrades: improved files, chat history, browser agent and document handling.
- Improved hardware compatibility: Windows AMD, Intel XPU and CUDA/PyTorch fixes.
- Faster image LoRA training with aspect buckets, fused AdamW and improved FP8/MXFP8 support.
Performance
- Large chat and training histories load in smaller batches, using less startup data and memory.
- Follow-up replies start sooner in long GGUF chats, including conversations with many tool calls.
- LTX-2.5 generation runs faster with the default two-stage settings when memory permits.
- Qwen3.5, Qwen3.6 and Qwen3.8 get faster prefill and speculative decoding with MLX.
Browser use
- Models can click at a point, move the mouse and drag page elements, including unlabelled targets such as canvases.
- Run scripts on a page with your approval each time, or set Run scripts to Never in Settings > Browser.
- Set per-site rules for unlabelled clicks, including Always allow for a site you trust.
- Better handling of compressed pages, client-side navigation and delayed content in the web UI. Models can also fill date and time fields.
- Pressing Enter in a form gets the same approval check as clicking its submit button.
Images + video
- Generate videos with LTX-2.5 from text or a start image, with synchronized audio. GGUF
- Add a Start frame with Wan2.2-TI2V-5B, LTX-2 or LTX-2.3 to animate an image on the same loaded model.
- Choose SDXL samplers and schedules on the Images page, and load v-prediction checkpoints correctly.
- Crop image inputs before generation. Large photo uploads and ordinary video frame uploads resize automatically.
Training
- Image LoRA training uses fused AdamW by default on NVIDIA GPUs, with aspect-ratio buckets for new supported runs.
- FP8 LoRA training for FLUX and Z-Image uses less memory on NVIDIA Ada, Hopper and Blackwell GPUs. MXFP8 handles aspect buckets on Blackwell with a compatible torchao stack.
- Set Sample every on the Train tab to see preview images during supported image training and in run history.
- Set caption dropout, LoRA dropout and checkpoint retention on the image Train tab. Random flipping is now opt-in.
- Fine-tune AWQ models with LoRA using Transformers 5 and GPTQModel, and export INT4 QAT models as quantized weights.
Chat + Desktop
- Drag files into Desktop chat again, including more Office documents, templates, EPUBs, README files, dotfiles and media.
- Upload supported PDF and Office documents up to 200 MB in the web UI.
- Linked folders honor common
.gitignore rules. Upload folders to project Sources from your browser, retry failed uploads and open completed sources.
- Type
/rewind, or choose Rewind from a message's More menu, to restore the conversation, tracked files in the chat folder, or both. Preview changes and undo a restore.
- Use
/compact in saved GGUF or MLX chats that support tools to compact context on the next message. Inline dividers mark compaction.
- Download model-created files from tool results, and enable notifications when a background reply finishes.
Models + settings
- Use local models in VS Code Copilot Chat with
unsloth start vscode.
- Coding agents can use Unsloth over MCP with an account API key to load models, generate, train and export.
- Choose a model download folder, and reveal or delete listed models from LM Studio, Ollama and your own folders.
Hardware compatibility
- Fix the PyTorch/Triton startup error on Windows AMD systems.
- Intel XPU recognizes native BF16 on supported Arc and Data Center GPUs without intel-ocloc, with improved GPU selection on single-tile Linux hosts.
- Avoid stale Triton launcher errors after switching Python versions on CUDA systems.
- Improved low-VRAM Gemma 4 E2B loading, including host-memory offload on Windows and WSL.
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.10.4 by @shimmyshimmer in #13433
- Key triton < 3.4 driver module cache by Python version by @danielhanchen in #13409
- Studio: linked folders honour .gitignore, folder uploads in the browser, queued drops and retry for failed sources by @shimmyshimmer in #13224
- Studio: image-to-video for Wan2.2-TI2V-5B and LTX-2 / LTX-2.3 by @danielhanchen in #13378
- fix(studio): preserve chat search position on close by @Sneakr in #13437
- Studio: refuse a text-encoder GGUF picked as the image or video model by @danielhanchen in #13423
- Studio: keep emoji split across tokens in MLX replies by @danielhanchen in #13416
- Studio: retry from the Hub when a cached snapshot has no tokenizer files by @danielhanchen in #13412
- Unsloth Studio (AMD/Windows): import PyTorch before Triton to avoid WinError 126 by @boobcactus in #10932
- Studio: list each on-disk quant of a multi-quant GGUF in GET /v1/models by @danielhanchen in #13422
- Studio: split DiffusionGemma across GPUs when one GPU cannot hold it by @danielhanchen in #13291
- Tests: catch up with four product changes that landed red on main by @danielhanchen in #13445
- fix(studio): show queued downloads consistently across media routes by @Imagineer99 in #13219
- Accept bf16 tie-flips in the batched left-padded generation guard by @danielhanchen in #13408
- fix: reshape noncontiguous gradients in fused LoRA backward by @MrCapricornLiu in #10712
- test_trl_cap_sites: unsloth_zoo 2026.10.4 admits trl 1.15.0, end the deferral by @danielhanchen in #13449
- Studio: keep Spark-TTS LoRA checkpoints exportable by @danielhanchen in #13424
- Keep uv, its cache and the uv-managed Python inside a custom UNSLOTH_STUDIO_HOME by @danielhanchen in #13373
- Studio: browser use follow-ups (safetensors nudge, date fields, disabled dropdowns, moved pages) by @danielhanchen in #13429
- Keep a user's UNSLOTH_RETURN_LOGITS=1 after for_inference() on FastModel by @danielhanchen in #13406
- Codex device-poll tests: fake asyncio.sleep only on the test's own thread by @danielhanchen in #13457
- Format two test files that #13378 and #13437 left off the formatter's fixed point by @danielhanchen in #13462
- Studio: run LTX-2.5 on the Video page by @danielhanchen in #13463
- Baseline the unsloth-zoo 2026.10.4 and trl 1.15.0 findings after review by @danielhanchen in #13472
- studio: restore file drops and composer drag feedback by @mahiatlinux in #13387
- Studio: optically centre the annotate button's icon by @shimmyshimmer in #13495
- Fix the three Backend CI reds LTX-2.5 left on main by @danielhanchen in #13496
- Studio: Open WebUI llama.cpp residency and explicit load/unload (#10610) by @debojyoti-dev in #10693
- studio: keep open thinking sized when the chat pane narrows by @shimmyshimmer in #13503
- Studio: nudge the dictate mic down 1px instead of 2px by @shimmyshimmer in #13504
- Studio: larger Browser use icon, more room and a shorter description in Settings by @shimmyshimmer in #13506
- tests: give each xdist worker one CPU share for torch by @danielhanchen in #13494
- Studio: close the LTX-2.5 two-stage speed gaps in a shared multi-stage layer by @danielhanchen in #13508
- Update README.md by @danielhanchen in #13512
- Studio: clip the browser page at the split handle while dragging it smaller by @shimmyshimmer in #13492
- Studio: composer accepts every document type chat with files parses by @shimmyshimmer in #13426
- studio: stronger light-mode Library card hover, centered time pill by @shimmyshimmer in #13509
- Studio: composer takes README-style files, dotfiles, Office templates and more media by @shimmyshimmer in #13493
- Studio: LTX-2.5 VAE fixture, catalog row and Video page defaults by @danielhanchen in #13500
- Make UNSLOTH_STUDIO_KEEP_LEGACY=0 work through docker/run.sh by @NilayYadav in #13488
- Studio: add --models-dir to unsloth studio for local model folders by @danielhanchen in #13435
- Studio: seed LTX-2.5 fp8 / int8 loads from hosted pre-quantized DiTs by @danielhanchen in #13516
- Studio: never follow a symlink when linking a file into a tool workspace by @danielhanchen in #13513
- studio: dim selected Library cards, slightly tighter card corners by @shimmyshimmer in #13518
- Studio: offer a download for files edit_file creates by @danielhanchen in #13448
- Studio: diffusion auto-optimizer core shared by the image and video load paths by @danielhanchen in #13520
- Studio: Regenerate title only in the Library's chat menu by @shimmyshimmer in #13491
- Add unsloth start vscode: put the served model in VS Code's Copilot Chat model picker by @danielhanchen in #13439
- Studio: mark where a chat was compacted with an inline divider by @oobabooga in #13502
- Studio: serve HTTPS from your own certificate (--ssl-certfile / --ssl-keyfile) by @danielhanchen in #13447
- Studio: show pending llama.cpp, whisper.cpp and audio.cpp updates on one card by @oobabooga in #13497
- Studio: open a project source from the Sources tab by @danielhanchen in #13441
- Studio: diffusion flow_shift is the effective shift, and min-SNR is recorded as unused for flow-matching runs by @danielhanchen in #13215
- Studio: random flip opt-in, plus checkpoint retention, caption dropout, LoRA dropout and timestep shift on the image Train tab by @danielhanchen in #13210
- Studio: scale the SDXL loss in fp16 and keep image LoRA training off devices it cannot use by @danielhanchen in #13278
- Studio: train image LoRAs with aspect-ratio buckets by @danielhanchen in #13218
- Format the diffusion auto-optimizer and LTX-2.5 prequant files by @danielhanchen in #13526
- Keep the saved Hugging Face login when from_pretrained gets a token by @NilayYadav in #13486
- test_packing_sdpa: take the loss path it reads labels from by @danielhanchen in #13434
- Studio: sample images during image LoRA training by @danielhanchen in #13220
- Turn off Granite 3.0-3.2 attention dropout on float16 loads by @danielhanchen in #13417
- Studio: train Z-Image LoRAs on attention and feed-forward by @danielhanchen in #13233
- Studio installer (AMD, Linux): no generic ROCm torch for RDNA 1 / Polaris when the arch is readable by @danielhanchen in #13419
- Studio: reveal and delete for LM Studio, Ollama, custom-folder and other local models by @shimmyshimmer in #13507
- Re-measure the Studio startup budget after the Library and composer merges by @danielhanchen in #13533
- Studio: per-family diffusion tables move into the family registries by @danielhanchen in #13536
- Studio: run the Shutdown cleanup off the event loop by @danielhanchen in #13534
- Save int4 QAT LoRA models as real int4 with save_pretrained_torchao by @danielhanchen in #13413
- Studio (AMD iGPU): split an iGPU row's total into VRAM and shared memory by @danielhanchen in #13421
- Fix the exec-literal, encoding and formatter gates left red on main by @danielhanchen in #13543
- Studio: transcribe with downloaded MLX speech-to-text models on Apple Silicon by @danielhanchen in #13443
- Studio: cap Qwen3.8 NPU context at 8192 by @oobabooga in #13525
- Studio: XPU native bf16 no longer depends on intel-ocloc by @danielhanchen in #13527
- Studio: rename the composer's Code toggle to Tools by @shimmyshimmer in #13402
- Studio: rounded-rectangle hover on the header model selector by @shimmyshimmer in #13546
- Studio: let a model loaded at a set context reload on Auto by @shimmyshimmer in #13555
- Studio: read ZE_AFFINITY_MASK the way Level Zero does by @danielhanchen in #13528
- unsloth start opencode: detect OpenCode V2 installed as plain opencode by @danielhanchen in #13550
- Studio: size music waits for Metal and Vulkan, not only CPU by @danielhanchen in #13551
- Skip bitsandbytes' per-parameter device sync in non-paged optimizer steps by @danielhanchen in #13389
- Studio: explicit XPU GPU ids on single-tile Intel hosts by @danielhanchen in #13540
- Studio: keep Hub Run settings open on a first Chat visit by @oobabooga in #13524
- Studio: run AutoRound checkpoints on vLLM, and tidy the engine dialog by @danielhanchen in #13405
- fix(studio): handle harmless Node helper stderr on Windows by @Imagineer99 in #13530
- Studio: faster image LoRA training (fused AdamW, compile nf4 bases) by @danielhanchen in #13236
- Studio: run LoftQ when the LoftQ variant is selected by @danielhanchen in #13535
- Fix int8-int4 QAT LoRA at low ranks and on tied-embedding models by @danielhanchen in #13552
- Studio: skip a DFlash drafter that an image would break under Auto by @danielhanchen in #13553
- Studio: stop LTX-2 loads crashing Windows with an access violation on 32 GB machines by @danielhanchen in #13432
- Studio: per-chat file history and /rewind by @danielhanchen in #13522
- Studio: browser agent can click at a point, move the mouse, drag, and run approved scripts by @shimmyshimmer in #13505
- Studio: list VS Code and Pi as coding agents and reorder the agent picker by @shimmyshimmer in #13547
- Studio: Regenerate title in the chat header menu by @shimmyshimmer in #13574
- Studio: rename sidebar chats in the Rename chat dialog by @shimmyshimmer in #13575
- Studio: translate the chat welcome greeting in every locale by @danielhanchen in #13549
- Studio: Run scripts setting and per-site Unlabelled clicks rule for the browser agent by @shimmyshimmer in #13529
- Studio: fp8 / mxfp8 image LoRA training on every aspect bucket, mxfp8 for biased linears, fp8 sm89 floor by @danielhanchen in #13317
- Re-measure the Studio startup budget after the file history and agent merges by @danielhanchen in #13586
- Studio: optional notification when a chat reply finishes in the background by @danielhanchen in #13554
- Prebuilt CUDA wheels: torch 2.11 for Windows x64 by @danielhanchen in #13563
- Studio: fix compressed pages, router paths and early empty reads in the browser panel by @oobabooga in #13532
- Studio: popups dim without blur, with a faint shadow; Settings a step darker by @shimmyshimmer in #13577
- Keep torch's bundled flash on Hopper for narrow models under UNSLOTH_FLASH_ATTENTION_IMPL=auto by @danielhanchen in #13544
- Parse each forward once in the per-step loss-kwargs walk by @danielhanchen in #13585
- perf(studio): enter Zoo's exact verify, NAX and packed gated-delta scopes on Unsloth Studio's own MLX paths by @Lyxot in #13404
- Fit Gemma 4 E2B on 8 GB cards on Windows and in Studio chat by @danielhanchen in #13425
- Let AWQ checkpoints train with LoRA by @danielhanchen in #13584
- Pass str target_modules (regex or "all-linear") to PEFT on the Llama path by @danielhanchen in #13567
- Patch TRL's served-teacher, GOLD and SDFT distillation trainers by @danielhanchen in #13580
- Studio: downscale oversized image uploads and add crop to image inputs by @danielhanchen in #13561
- Run non-LoRA PEFT adapters through their own forward in fast inference by @danielhanchen in #13578
- Make the weights_at_root call-site and diffusion autoopt parity tests host independent by @danielhanchen in #13582
- studiobench UI parity: report a UI change the PR declares instead of failing by @danielhanchen in #13583
- Studio setup: build the frontend in the background on source installs (setup.sh and setup.ps1) by @danielhanchen in #13442
- Studio: load sidebar chats, projects and training runs 20 at a time from the server by @danielhanchen in #13420
- Fix image inputs in Clef training and prediction by @Imagineer99 in #13471
- Studio: apply the tool output length setting to MCP tool results by @danielhanchen in #13588
- Tests: follow the sidebar rename dialog and run the H3 compile-order test without diffusers by @danielhanchen in #13590
- Studio: let coding agents use Unsloth Studio over MCP with API keys by @Etherll in #13118
- Studio: pick the sampler on the Images page and load v-prediction SDXL checkpoints correctly by @danielhanchen in #13569
- Studio: add a Download to folder for model downloads by @danielhanchen in #13557
- Studio: keep the Transcribe loaded state and Eject in step with the sidecar by @Etherll in #13514
- Studio: fix Spark-TTS training failing on None/config.yaml (BiCodec repo root unset) by @carlitogwapito in #13465
- Studio: add /compact and draw compactions where they happened by @danielhanchen in #13562
- Studio: keep the prompt cache across long tool chats and follow-up turns by @danielhanchen in #13456
- Keep Mistral Small 3.2 tool definitions in training rows by @danielhanchen in #13597
- Studio: video component sizes from safetensors headers, measured peaks for every video family by @danielhanchen in #13537
- Studio: fix audio.cpp partial downloads, aligner progress, CPU fallback by @Etherll in #13515
- Studio: faster browser agent page reads after a load, and leaner drags by @danielhanchen in #13602
- Studio: trim comments in the video header sizes code by @danielhanchen in #13610
- Studio: optional Chart view with labelled axes for weekly and cumulative token activity by @danielhanchen in #13558
- Studio: fit MiniMax-H3 GGUF to a Vulkan host's GTT pool before rendering by @danielhanchen in #13531
- Studio: LTX-2.5 GGUF quants (unsloth/LTX-2.5-GGUF) by @danielhanchen in #13573
- FastSentenceTransformer: reuse the loaded model for Transformer subclass modules by @danielhanchen in #13591
- Studio: list, reveal and delete audio.cpp umbrella models by folder by @Etherll in #13519
- Fix the diffusion scheduler, parity, formatter and bundle reds on main by @danielhanchen in #13612
- Studio: Auto drops serving slots before the MTP drafter by @danielhanchen in #13455
- tests: resolve every closure name in the restoreSettings sandbox by @danielhanchen in #13617
- Studio: inline message actions, matching response editor by @shimmyshimmer in #13615
- Studio: set thinking traces apart from the answer and give tool rows kind icons by @shimmyshimmer in #13545
- Studio: fix the audio model selector's list, labels and search by @Etherll in #13517
- Studio tests: restore stub, titlebar backdrop, and run the autoopt parity fixture with diffusers by @danielhanchen in #13608
- Studio: emit --moe-cache-mib auto only where the cache measured faster, price the spill micro-batch by @danielhanchen in #13600
New Contributors- @boobcactus made their first contribution in #10932
- @carlitogwapito made their first contribution in #13465
Full Changelog: v0.1.906-beta...v0.1.907-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: