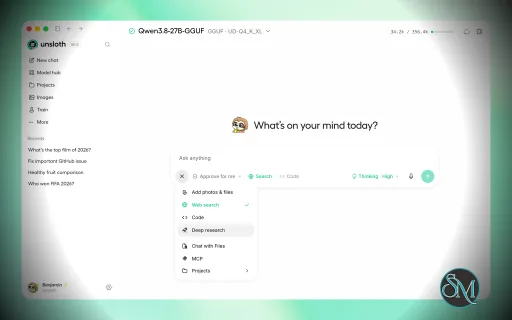
Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.905-beta - Software Mirrors |
|---|
Unsloth v0.1.905-beta for WindowsUnsloth-Desktop-Windows.exe | 22.02 MB Unsloth-Desktop-Windows-ARM64.exe | 21.48 MB |
Unsloth v0.1.905-beta for macOSUnsloth-Desktop-MacOS.dmg | 23.63 MB |
Unsloth v0.1.905-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 25.55 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 25.87 MB Unsloth-Desktop-Linux.AppImage | 172.29 MB |
Others Download related to Unsloth v0.1.905-betaUnsloth-Desktop-ARM64.app.tar.gz | 23.44 MB |
Unsloth v0.1.905-beta Source Code
Unsloth v0.1.905-beta Source code (zip)
Unsloth v0.1.905-beta Source code (tar.gz)
|
Unsloth v0.1.905-beta Release Notes: Turn any text or vision LLM into a Jev-style decision model in Unsloth, with decision accuracy going from 30% to 80%. Train, test, export and serve decision models directly from Unsloth. Also included: native ComfyUI models, diffusion improvements and a better Browser in Desktop.
Highlights
- 8th Oct Fixes - Better Browser + 100+ bug fixes + perf fixes
- Sandboxing with Bwrap for Linux, Seatbelt for Mac and MXC for Windows
- Turn any model into a Jev-style decision model. Accuracy went from 30% to 80%
- Load ComfyUI diffusion models natively in Unsloth
- Faster + more accurate diffusion with INT8 ConvRot and more
https://github.com/user-attachments/assets/92959172-d2a2-450b-a5bf-6369a1e5ae16
Decision models
- Train any text or vision LLM as a Jev-style decision model using QLoRA.
- Test trained models directly from the Decision API settings.
- Make decisions with confidence scores for every option.
- Export Clef models with Qwen3.5 backbones and Laya models to GGUF.
- Serve supported decision models through llama.cpp, including models that understand images.
- Save and resume smaller adapter and decision-head checkpoints.
- Guide at https://unsloth.ai/docs/basics/train-your-own-decision-model-with-unsloth

Diffusion + ComfyUI
- Run supported ComfyUI image and video models directly from Hugging Face.
- Unsloth now recognises ComfyUI checkpoints and local model folders automatically.
- Use your ComfyUI text encoders and VAEs in Unsloth.
- Run Krea-2, HunyuanImage-2.1 and Wan2.2 expert pairs, plus ComfyUI NVFP4 and MXFP8 models.
- Qwen-Image-2.1 now keeps more full-precision image detail with INT8 ConvRot enabled by default.
- Faster Qwen-Image-2.1 ConvRot generation on supported NVIDIA GPUs.
Training + performance
- Train Qwen3.5-35B-A3B up to 4.1x faster and Qwen3-30B-A3B up to 3.3x faster with QLoRA on A100 and RTX PRO 6000.
- Improved sample packing for gated-delta, Mamba2 and short-convolution models.
- Train prompt and completion message lists as one conversation.
- Vision datasets now keep each row's own question.
- Chat exports and training data now include the system prompt.
Browser + Desktop
- Ask about open pages in the Desktop Browser.
- Confirm Browser downloads and choose where files are saved.
- Reorder pinned pages in the sidebar like chats.
- Search continues past unusable results and can fall back to Wikipedia.
- Reply citations such as
[1] now open as links.
- Pick, pin or unload RAG embedding models directly from the RAG menu.
Sandboxing
- Bwrap on Linux, Seatbelt on Mac and MXC on Windows sandbox code the model runs.
- View sandbox status and choose protection levels in Settings.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
 -- Platform
 -- Link


 -- Windows
 -- Download


 -- macOS
 -- Download


 -- Linux x64 / Ubuntu (deb)
 -- Download


 -- Linux ARM64 / Ubuntu 24.04+ (deb)
 -- Download


 -- Linux x64 (AppImage)
 -- Download


 -- Windows ARM64
 -- Download
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.10.1, unsloth-zoo>=2026.10.1 by @danielhanchen in #12869
- Studio: list embeddinggemma-2 first in the embedding model picker by @shimmyshimmer in #12870
- Repair three checks that went red on main with the 10-06 Studio merges by @danielhanchen in #12868
- Studio: run ComfyUI-format video quants on the int8 / fp8 runtimes by @danielhanchen in #12851
- Studio: free PyAV's per-thread scalers before a fork so preexec_fn spawns still exec by @danielhanchen in #12863
- Tests: give the setup.ps1 download progress pwsh its own startup cache by @danielhanchen in #12882
- Studio: fill the Hebrew and Swedish strings that left the strict i18n check red on main by @danielhanchen in #12881
- Baseline the eight unsloth-zoo 2026.10.1 findings after review by @danielhanchen in #12884
- Support every PEFT init_lora_weights option, with fast PiSSA and MiCA init by @Suchitra-idu in #6879
- Sandbox test: wait for the cache scan workers before counting them by @danielhanchen in #12896
- Studio: keep browser panel tooltips, toasts and menus visible over desktop web pages by @oobabooga in #12895
- Studio: continue searching past unusable results and add a Wikipedia fallback by @oobabooga in #12892
- Studio: list every Transcribe ASR model in Voice settings by @Etherll in #12898
- Frontend test: give the cold Vite SSR render in reasoning-source-render room on a loaded runner by @danielhanchen in #12903
- Run shell suites and Windows browser checks in parallel by @oobabooga in #12899
- Studio: add a New badge beside Audio in the sidebar by @Etherll in #12891
- Composer settings driver: poll the submitted list instead of reading it once after the key press by @danielhanchen in #12920
- Studio: support current native builds and preserve CPU asset selection by @oobabooga in #12902
- Studio: pick the quant of a GGUF dictation model in Voice settings by @Etherll in #12900
- fix(studio): stop a managed runtime when the client drops its stream by @goodmai in #12266
- Studio: train prompt/completion message lists as one conversation by @NilayYadav in #12910
- Studio: keep each row's own question when training on a vision dataset by @NilayYadav in #12909
- Studio: train transparent PNG and WebP images on white instead of black by @NilayYadav in #12908
- Use the requested max_seq_length for encoder embedding models by @NilayYadav in #12915
- Studio: show the LAN address on the API page when LAN access is on by @NilayYadav in #12906
- Studio: hide the negative prompt on image models that ignore it by @NilayYadav in #12914
- Keep the notebook and saved model when unsloth-run runs a URL by @NilayYadav in #12907
- Studio: drag pinned pages in the sidebar like chats by @shimmyshimmer in #12927
- Studio: Ask about this page on every page, desktop included by @shimmyshimmer in #12926
- Docker: allow unsloth_root_shim.py into the build context by @danielhanchen in #12929
- Tauri transport test: start the late backend after the old ladder is spent, not at 3s by @danielhanchen in #12930
- Studio: simpler icons for the audio pages, one audio icon in the Library by @Etherll in #12890
- Desktop contract: count #12927's scaled sidebar row by @danielhanchen in #12931
- fix(studio): preserve skill mention intent and denied preload context by @wasimysaid in #12841
- Studio: embedding model picker, pins and eject in the RAG menu by @shimmyshimmer in #12875
- install-kernels: skip mamba_ssm below sm80 by @danielhanchen in #12921
- Gemma-4 26B/31B: train with the empty thought channel on non-thinking turns by @danielhanchen in #12867
- Studio: try a decision from the Decision API settings by @NilayYadav in #12916
- Studio: confirm browser downloads, choose the download folder by @shimmyshimmer in #12832
- Studio: default Qwen-Image-2.1 int8 to the hosted ConvRot file, with shared rotations by @danielhanchen in #12874
- Studio: recognise ComfyUI checkpoints by name and header, and list ComfyUI model folders by @danielhanchen in #12878
- studio: install the gstreamer recording plugins with the deb package by @mahiatlinux in #12905
- Studio: turn [1]-style citations in replies into links by @NilayYadav in #12912
- Studio: include the chat's system prompt in exports and training data by @NilayYadav in #12913
- studio: guard project submits during IME composition by @mahiatlinux in #12924
- studio: scope speech download cancellation to its attempt by @mahiatlinux in #12925
- studio: keep general settings from restoring stale tokens by @mahiatlinux in #12922
- Studio: show when Windows MXC already runs in the built-in container by @danielhanchen in #12938
- Studio: key the diffusion compile cache by the loaded quant variant by @danielhanchen in #12887
- Studio: rebuild an image / video GGUF from the cached copy when only its header changed by @danielhanchen in #12928
- Scope UNSLOTH_HIGH_PRECISION_LAYERNORM to the load that sets it by @danielhanchen in #12873
- fix(studio): honor llama.cpp update dismissal and snooze by @wasimysaid in #12934
- Keep flash attention from reading Qwen3.5 mRoPE position ids as packed sequences by @danielhanchen in #12856
- Studio: load Wan2.2-A14B expert pairs and tell LTX-2.3 distilled from dev by its weights by @danielhanchen in #12872
- Train a decision model from a plain language model by @danielhanchen in #12772
- Train any text or vision LLM as a Clef decision model from Studio, with FastDecisionModel.predict and adapter saves by @danielhanchen in #12876
- Studio: install transformers releases needing hub >= 1.31, and transformers main after consent by @danielhanchen in #12871
- Correct sample packing for hybrid models (gated-delta, Mamba2, short conv) by @kfastino in #9812
- Studio: read replies aloud without markdown symbols by @AzizMuminov in #12598
- Studio: finish an update with the setup script it installed by @Etherll in #12897
- Serve decision models through llama.cpp in Studio, and export them to GGUF by @danielhanchen in #12939
- studio: fix live monitor background in light mode by @mahiatlinux in #12904
- Studio: show the hosted text encoder download in image load progress by @Etherll in #12894
- Studio: update the audio.cpp runtime from the in-app update by @Etherll in #12893
- Settings contract: read the embedding picker's stacking classes inside cn() too by @danielhanchen in #12945
- install-kernels: install mamba_ssm on sm75 with Triton 3.4+ by @danielhanchen in #12944
- Studio: load Wan2.2 hosted FP8 / INT8 files, and hosted files under low_vram by @danielhanchen in #12888
- Studio: load a single .safetensors DiT from any Hugging Face repo by @danielhanchen in #12879
- fix(studio): remember per-GPU layer ratios by @Imagineer99 in #12774
- Studio: load ComfyUI Krea-2 and HunyuanImage-2.1 single-file DiTs by @danielhanchen in #12885
- Studio: load ComfyUI text encoder and VAE files beside a single-file DiT by @danielhanchen in #12883
- Studio: load ComfyUI nvfp4 and mxfp8 DiT single files by @danielhanchen in #12877
- Studio: keep $PATH, $HOME and other shell variables as text, not maths by @NilayYadav in #12911
- Studio: price the context meter off a tool loop's final pass, not the whole turn's completions by @sumingwang233 in #12889
- Studio: open Try a decision with the trained model after Use in Decision API by @NilayYadav in #12953
- Studio: harden browser downloads after #12832 by @danielhanchen in #12943
- Repair four checks that went red on main with the decision-model merges by @danielhanchen in #12954
- Bump install.sh / install.ps1 pins to unsloth>=2026.10.2 by @danielhanchen in #12960
- install-kernels: tidy the sm75 mamba_ssm follow-ups by @danielhanchen in #12948
- Studio frontend: bump proxy-addr, seroval and MCP SDK for npm advisories by @danielhanchen in #12932
- Studio: close managed-account and API-key gaps in owner-only routes by @danielhanchen in #12940
- Studio: harden S3 dataset keys, uv fallback, header reads and auth body cap by @danielhanchen in #12936
- Decision models: follow-up fixes after #12772, #12876, #12939 by @danielhanchen in #12949
- Fix the backend CI guards main fails after the decision and ComfyUI merges by @danielhanchen in #12958
- Baseline the two unsloth-zoo 2026.10.2 findings after review by @danielhanchen in #12956
- Installer differential: ignore winget spinner frames in the transcript by @danielhanchen in #12965
- tests: keep the Kaggle launcher's signal handlers out of the pytest worker by @danielhanchen in #12974
- Stop test_dataset_cache_safe leaking the Hub no-symlink switch into later tests by @danielhanchen in #12973
- Studio: keep Deep Research tables intact when a cited title has a pipe by @NilayYadav in #12990
- Studio: keep tool call arguments in Qwen3.5 safetensors and MLX prompts by @NilayYadav in #12988
- Fix linked-folder indexing of hidden subdirectories by @Imagineer99 in #12972
- Studio: compact long chats on self-hosted connections to the window the server reports by @oobabooga in #12975
- Studio: show project sources as unused on models without tools by @NilayYadav in #12993
- Studio: show a download card when the python tool edits an attached file by @NilayYadav in #12992
- Studio: stop crashing on a lowercase boolean in PYTORCH_ALLOC_CONF by @oobabooga in #12976
- Studio: decode pages in the browser panel the way browsers do by @NilayYadav in #12983
- Studio: use llama-server for embedding models the installed sentence-transformers cannot load by @oobabooga in #13005
- Studio: train vision datasets that have some rows without an image by @NilayYadav in #12991
- Support text attachments in per-chat prompt queues by @Imagineer99 in #12964
- Studio: make Thinking off and Preserve thinking work on Qwen3.6 by @NilayYadav in #12989
- Studio: smaller settings info icons, engine notes under the engine name by @shimmyshimmer in #13008
- Studio: static dark dropdown glow, and stop modal opens restyling the page by @shimmyshimmer in #13013
- Studio: open video attachments in the browser panel by @shimmyshimmer in #13007
- Studio: show a site's own error page in the browser panel by @NilayYadav in #12986
- Studio: list typed-decisions datasets first for decision training by @NilayYadav in #12982
- Keep the model a training script saves when it runs in Docker by @NilayYadav in #12994
- Skip the fast LoRA paths when lora_B has a bias by @vineethsaivs in #12981
- Studio: prefer llama-server for EmbeddingGemma in the embedding model picker by @oobabooga in #13006
- Studio: ask before numpy pickle loads, keep audio tags inline, cap the variable-prose regex by @danielhanchen in #13001
- Studio: parse Yahoo's newer result layout in web search by @oobabooga in #12980
- Update the flex large head dim mask tests to the unpadded causal-mask skip by @danielhanchen in #13018
- Studio: serve whisper-server under a random per-launch request path by @danielhanchen in #13002
- Studio: find nvidia-smi under WSL on every query, count Core Ultra Arc iGPUs as XPU, cut GPU masks at an invalid index by @danielhanchen in #12962
- Studio: make llama-fit-params executable after the macOS prebuilt install by @jayzhou2309 in #12917
- Studio: leave a bracketed IPv6 host unchanged in dial_host by @drakeo338 in #12733
- Studio: build VAE tile blend weights on CPU so MPS tiled encode works by @gokay-ai in #12937
- Studio: run llama-server with a per-launch API key by default by @danielhanchen in #13011
- Studio: keep new image sets from merging into an existing one by @NilayYadav in #12987
- install.sh: install for the discrete AMD GPU when an iGPU is listed first by @danielhanchen in #12963
- FastModel: fall back to Unsloth inference on GPUs older than Volta by @danielhanchen in #12959
- Unsloth Studio (AMD): show each GPU's live VRAM and utilization under its own HIP id by @danielhanchen in #12961
- Studio: Downloads button in the browser panel by @shimmyshimmer in #13009
- Studio: keep a chat's HTML pages with that chat by @NilayYadav in #12985
- Studio: make the browser's right-click downloads work on macOS by @shimmyshimmer in #13003
- Studio: put the skill row chevron next to the skill name by @shimmyshimmer in #13033
- Studio: close refused tool calls under tool_choice none by @Beverly621 in #12627
- Studio: keep browsing from a temporary chat out of browser history by @NilayYadav in #12984
- Studio: duplicate a past training run into a new Configure draft by @Padi142 in #12979
- Unsloth Studio / Desktop: show a cached image GGUF as Partial until Run has its text encoder and VAE by @LeoBorcherding in #12557
- Load one tensor at a time when quantizing a 16-bit checkpoint, so Qwen3.5-27B 4-bit loads without Block Swap by @LeoBorcherding in #12997
- Studio: show the real cause when a desktop install runs out of disk space by @huntersgordon in #12919
- Fix notebook failures on Kaggle T4x2 and duplicate import warnings by @danielhanchen in #13024
- Studio: skip the Xet probe's GPU-init-off zoo retry on GPU hosts by @arcusbuilds in #12478
- Studio: stop MXC read grants looping on a Microsoft Store Python by @danielhanchen in #13025
- Studio: avoid a TypeError after a tools module reload by @jiangLLM in #11506
- Studio: retry web search over HTTP/1.1 when the connection is reset by @danielhanchen in #13032
- Studio: stop a Git Bash nul file from blocking every Windows MXC tool call by @danielhanchen in #13037
- Decline the packed INT4 kernel when weight_scale has the wrong group count by @jayzhou2309 in #12957
- Studio: let another account join the resident GGUF instead of replacing it by @danielhanchen in #13038
- Studio: give the annotate comment box a visible shadow in dark mode by @shimmyshimmer in #13071
- Installer: read the venv's torch in isolation so a PYTHONPATH torch cannot break the install by @danielhanchen in #13041
- Studio: keep tensor split and MTP when Auto would pick a DFlash drafter that aborts it by @danielhanchen in #13040
- Allow backward through eval-mode and for_inference forwards by @danielhanchen in #13050
- Make Q-GaLore optimizer state resumable from checkpoints by @danielhanchen in #13051
- Studio: Docs links for Sandbox, Agents and the Decision API by @shimmyshimmer in #13076
- Studio: serve decision models through the MLX engine on Apple Silicon by @Lyxot in #13015
- Studio: pin FastFlowLM 1.0.7 for Qwen3.8 27B on the AMD NPU and keep Lemonade / FastFlowLM current by @danielhanchen in #13047
- Studio: report the real llama.cpp version for source builds by @danielhanchen in #13036
- Studio: name media companion downloads by component, and show what Run still fetches for an on-device GGUF by @danielhanchen in #13027
- Studio: keep a dragged annotate area the size it was drawn by @shimmyshimmer in #13070
- Studio: load a repo id from its scan-folder copy instead of re-downloading it by @danielhanchen in #13034
- Train EXAONE 3.5: name the token embedding remote code no longer exposes by @danielhanchen in #13058
New Contributors- @kfastino made their first contribution in #9812
- @sumingwang233 made their first contribution in #12889
- @drakeo338 made their first contribution in #12733
- @Beverly621 made their first contribution in #12627
- @Padi142 made their first contribution in #12979
- @huntersgordon made their first contribution in #12919
- @arcusbuilds made their first contribution in #12478
- @jiangLLM made their first contribution in #11506
Full Changelog: v0.1.903-beta...v0.1.905-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: