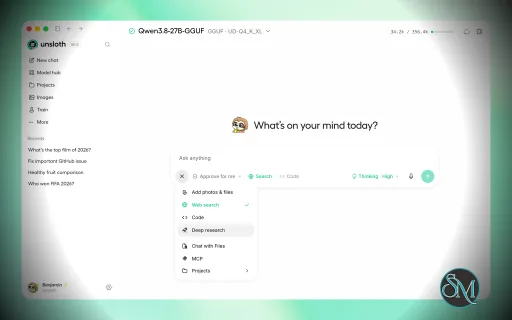
Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.916-beta - Software Mirrors |
|---|
Unsloth v0.1.916-beta for WindowsUnsloth-Desktop-Windows.exe | 20.68 MB Unsloth-Desktop-Windows-ARM64.exe | 20.06 MB |
Unsloth v0.1.916-beta for macOSUnsloth-Desktop-MacOS.dmg | 21.19 MB |
Unsloth v0.1.916-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 22.56 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 22.3 MB Unsloth-Desktop-Linux.AppImage | 169.56 MB |
Others Download related to Unsloth v0.1.916-betaUnsloth-Desktop-ARM64.app.tar.gz | 20.96 MB |
Unsloth v0.1.916-beta Source Code
Unsloth v0.1.916-beta Source code (zip)
Unsloth v0.1.916-beta Source code (tar.gz)
|
Unsloth v0.1.916-beta Release Notes: This release brings large performance fixes across Unsloth: faster typing and search in long chats, faster image/video loads, two-GPU image/video gen. It also adds separate browsers for each chat, floating browser window.
Highlights
- Large performance fixes with more Glass theme optimizations coming next week
- Glass theme fixes no more blur, better rendering, more options
- Unified memory offloading now properly works for big models
- Separate browsers for each chat - Multiple chats can now run their own browser individually
- Floating browser you can move and resize over the chat & let the model do it's thing
- Dynamic V3.1 Qwen3.8-Flash - 50% less token use, 15% more accurate
- Two-GPU image and video up to 2x faster on matching NVIDIA cards
- Faster chat search and deleting - search and delete chats much faster
- Stable diffusion image/video models loads up to 40% faster
- LTX-2.5 video much faster for new prompts on 16 to 24 GB GPUs
Chat performance
- Typing in a long chat no longer lags when a Glass theme or chat background is on.
- Chat search stays fast on very long histories instead of failing to load.
- Clearing and deleting chats is much faster on large histories.
- The first use of voice or audio features after launch no longer freezes a streaming reply for seconds.
- Read aloud with the Unsloth model engine no longer waits seconds on a model lookup before speaking.
- Glass themes over a background image respond up to 2x faster without GPU rendering, as on some Linux desktops.
Images and video
- With two matching, idle NVIDIA GPUs, models such as SDXL, Qwen-Image and Wan2.2 5B run half of each step on the second card when they fit on one, about 1.5 to 1.8x faster.
- On the same setup, FLUX and Lumina 2 split an even-sized batch of images across both cards.
- SDXL loads up to 40% faster, so the first image arrives sooner.
- On 16 to 24 GB GPUs, LTX-2.5 encodes new prompts on the GPU instead of the CPU, so a clip with a new prompt renders much faster.
- LTX-2.5 GGUF Q8_0 video renders about 10% faster on NVIDIA GPUs, with identical frames.
- Repeat renders with the same LoRA are faster when the model is not quantized, GGUF or offloaded.
- Some image models, such as FLUX and Z-Image, render faster on Linux with AMD RDNA3 and RDNA4 GPUs.
New in Unsloth
- Float the built-in browser over the chat as a small window you can move and resize; each chat remembers whether it floats.
- Load Anima, Chroma, MOSS-Image and Krea 2 image models from single-file checkpoints, with LoRA and LoKR files for all but Chroma.
- Glass themes dim the background image instead of blurring it, and controls on other pages match the chat's glass.
- Owners can rename a managed account without losing its chats, files or settings.
- Owners can cap model download speed in Settings > General > Downloads.
- OpenAI-compatible connections can send custom headers.
Fixes
- On chat-only installs with a non-GGUF model already downloaded, the first chat fetches the default model instead of failing.
- GGUF models on CPU-only machines no longer run out of memory with Auto context.
- On Windows, HTTPS downloads resume after a pause or interruption instead of starting over.
- Updating Unsloth on Windows no longer sits silent for half a minute at the end.
- Connecting Blender through MCP works again.
- Compare mode no longer leaves one pane empty on the first message.
Training and library
- In Python,
model.generate() for Llama, Qwen2 and Qwen3 models is faster by default on NVIDIA GPUs under Linux, up to several times for small models.
- Training on a Hub dataset split into hundreds of files starts up to a minute sooner.
- With Assistant completions only, answers that start with a newline are no longer left out of training.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
 -- Platform
 -- Link


 -- Windows
 -- Download


 -- macOS
 -- Download


 -- Linux x64 / Ubuntu (deb)
 -- Download


 -- Linux ARM64 / Ubuntu 24.04+ (deb)
 -- Download


 -- Linux x64 (AppImage)
 -- Download


 -- Windows ARM64
 -- Download
What's Changed- Bump install.sh / install.ps1 pins to unsloth>=2026.11.2 by @danielhanchen in #16688
- Carry the float8 training mode into the parallel capability query by @danielhanchen in #16637
- Studio: send custom headers on remote connections by @Souravrajvi0 in #15097
- Studio: fold an unchanged LoRA set into a resident denoiser, restore it exactly before a change by @danielhanchen in #16675
- Refuse tensor parallel on blocks that own parameters in the registry by @danielhanchen in #16638
- Kernels: keep sequence length out of Triton specialization in the RoPE kernels by @danielhanchen in #16690
- Studio: keep Qwen-Image's bf16 text encoder automatically when the card has room by @danielhanchen in #16678
- Studio: read the SDXL v-prediction markers beside the weight load and once per commit, skip the UNet scheme probe by @danielhanchen in #16696
- Studio video small host: price the encoder converted beside the cast misses, cast an oversized DiT from its source shards by @danielhanchen in #16700
- Native quant tests: make peft see torchao as absent when the test blocks it by @danielhanchen in #16704
- Studio: decode escaped text in spreadsheet previews by @DimitriChrysafis in #16592
- Studio: preserve refusal messages in imported chats by @DimitriChrysafis in #16599
- Capability registry: refuse tensor parallel where tp_native cannot shard, and add the zoo MoE families by @danielhanchen in #16709
- README: say UNSLOTH_LLAMA_CPP_BACKEND picks the GGUF chat build, not PyTorch by @LeoBorcherding in #14256
- Studio: state the audio memory estimate in placement refusals by @debojyoti-dev in #16628
- Decode with CUDA graphs by default in plain generate(), with memory release and an eager fallback by @danielhanchen in #16691
- Studio diffusion: CFG-parallel for U-Net families (SDXL) by batch split by @danielhanchen in #16679
- Studio diffusion: Automatic arms CFG-parallel on an idle card of the same model by @danielhanchen in #16680
- Studio diffusion: CFG-parallel for a group-offloaded denoiser by @danielhanchen in #16681
- Studio diffusion: Automatic partner card, FLUX batch split, LoRA scale mirror, CFG batching fallback by @danielhanchen in #16682
- Studio diffusion: Automatic prefers one card plus a second-card copy over a layer split for FLUX when the primary holds the whole denoiser by @danielhanchen in #16687
- Pipeline parallel: weight the MoE router aux loss per accumulation step as the model forward does by @danielhanchen in #16708
- Scan baseline: re-review the five unsloth-zoo sites 2026.11.2 moved by @danielhanchen in #16732
- Kaggle Studio GPU CI: request hardware detection after sign-in by @danielhanchen in #16728
- Studio video: report the dense bf16 text encoder when the automatic hosted fp8 encoder cannot be fetched by @danielhanchen in #16724
- CPU backend: honour unsloth_tiled_mlp and UNSLOTH_TILED_MLP in FastLanguageModel.from_pretrained by @danielhanchen in #16731
- Notebooks CI: refresh the Colab oracle snapshot to the torch 2.14.1 GPU runtime by @danielhanchen in #16738
- CPU backend: install the every_n_layers gradient checkpointing router by @danielhanchen in #16730
- Context parallel: compiled layers follow each packed row under Ulysses by @danielhanchen in #16733
- Studio: load NVFP4 diffusion checkpoints from .safetensors only by @danielhanchen in #16739
- Studio: stop silently dropping earlier replies sent as item references by @NilayYadav in #16694
- Studio: keep the typed message when picking a saved prompt by @NilayYadav in #16695
- Studio: show the chat background in conversations on Windows at 100% scaling by @LeoBorcherding in #16702
- Keep reasoning when formatting chats with the gemma-4-thinking template by @NilayYadav in #16701
- Studio: run each Compare model with its own recommended sampling by @NilayYadav in #16686
- Multi-account Playwright: an aborted /login must not use up the stalled-load retry by @danielhanchen in #16768
- Studio: answer Refresh and Edit in a Compare pane with its own model by @NilayYadav in #16698
- Context parallel: no graph break in compiled Ulysses attention on packed rows by @danielhanchen in #16734
- Hide the Model hub scroll fade in glass themes by @Imagineer99 in #16780
- Studio: glass theme dims the wallpaper instead of blurring it, page controls take the model button glass, Reduce motion off by default by @shimmyshimmer in #16751
- Studio: let an approved Python call reach a host outside the sandbox allowlist by @danielhanchen in #16674
- Studio: rename a managed account without recreating it by @danielhanchen in #16668
- Bump trufflesecurity/trufflehog in / by @dependabot[bot] in #16778
- Bump step-security/harden-runner in / by @dependabot[bot] in #16777
- Bump docker/login-action in / by @dependabot[bot] in #16776
- Add opt-in BF16 AdamW with stochastic parameter updates by @danielhanchen in #16662
- Studio: floating monitors stay under the pointer and land without a flash by @shimmyshimmer in #16781
- open_login test: bring its own Playwright error types so a leaked stub cannot break it by @danielhanchen in #16784
- GRPO: keep packed forwards off for models that mix tokens across packed rows by @lonexreb in #16349
- Studio: search for llama-server once per Decision API settings answer by @danielhanchen in #16617
- Desktop: keep the bundled AppImage tray loader off the host's Ayatana by @debojyoti-dev in #16613
- Studio: fingerprint the same manifest scopes the downgrade migration scan reads by @danielhanchen in #16556
- Studio: the in-app browser can float over the chat as a small, resizable window by @shimmyshimmer in #16775
- Studio MLX images: faster GGUF to MLX bit packing, byte-identical output by @danielhanchen in #16746
- Studio: skip the NVML memory probe child when CUDA_VISIBLE_DEVICES is blank by @danielhanchen in #16597
- Studio: list a GGUF repo once for the mmproj, MTP, DSpark and DFlash lookups of one load by @danielhanchen in #16565
- Studio: read each thread's stored messages once per chat re-import by @danielhanchen in #16615
- Studio remote-code scan: read each Hub config once per scan request by @danielhanchen in #16606
- Studio RAG: reuse one rag.db connection per thread within a linked-folder sync pass by @danielhanchen in #16607
- Studio: browser dictation in Chrome no longer repeats the last word by @NilayYadav in #16685
- Studio: judge an HSA_OVERRIDE_GFX_VERSION GPU by its override in the cold engine status by @danielhanchen in #16670
- perf(studio): queue MLX prompt-cache snapshots without waiting on the GPU by @Lyxot in #16683
- Studio: keep cancelled fine-tuning jobs in paginated results by @Max-Reisinger in #16633
- Studio: read adapter_config.json once per inference worker load by @danielhanchen in #16604
- Studio: load Anima, Chroma, MOSS-Image and int4 Krea 2 ComfyUI single files by @oobabooga in #16710
- Studio: fix two first-use regressions from deferred startup hardware detection by @danielhanchen in #16629
- perf(studio): stream MLX VLM SentencePiece tokens as they are sampled by @Lyxot in #16684
- Studio: quantize Qwen-Image-2.1-Turbo NVFP4 with the Qwen-Image-2.1 layer policy by @danielhanchen in #16757
- Studio: size more audio.cpp music models from measured peaks and show the load estimate in the picker by @oobabooga in #16726
- Studio: answer the first Compare message in both panes by @NilayYadav in #16693
- Studio: fit Auto context to system RAM on CPU-only machines by @NilayYadav in #16689
- Fused LoRA backward: skip the gradient GEMMs of a frozen A or B by @danielhanchen in #16752
- Studio: reuse an identical llama-server prompt count within a tool round by @danielhanchen in #16756
- Decode: CUDA-graph replay for Qwen2 models by @danielhanchen in #16753
- Studio diffusion: stream the LTX-2.5 encoder, cache and trim FLUX.3 prompt encodes by @danielhanchen in #16750
- Studio video: denormalize decoded frames slice by slice in the uint8 export by @danielhanchen in #16748
- Avoid duplicate successful sandbox probes during refresh by @heychaeyin in #16735
- Studio: move MLX to mlx-vlm 0.7.12 and serve mlx-vlm-only text families by @Lyxot in #16765
- Studio diffusion: fused FLUX AdaLN on by default on NVIDIA Linux (2.4% per eager step, fp32 error unchanged) by @danielhanchen in #16760
- Studio diffusion: TF32 matmuls on the default speed tier, not only max by @danielhanchen in #16762
- Studio video: MiniMax-H3 int8 video decoder on by default (30-33% faster decode, LPIPS 0.0004-0.0013) by @danielhanchen in #16764
- Studio multi-GPU: split an even Lumina 2 batch across two cards (1.7-2.1x, fp-order only) by @danielhanchen in #16786
- Studio video: keep a streamed LTX-2 denoiser partly resident per request (21% faster per step) by @danielhanchen in #16787
- Studio Images: pin the parked SAM 3 copy with registered host memory by default (unpark 0.36 -> 0.14 s) by @danielhanchen in #16791
- Diffusion autoopt parity: add tf32 to the Anima and Chroma default-tier rows by @danielhanchen in #16838
- Studio: apply ComfyUI LoRA and LoKR files to Anima, Krea 2 and MOSS-Image by @oobabooga in #16711
- Studio diffusion: fuse the SwiGLU product into the down projection's act quant on untuned sm80+ archs by @danielhanchen in #16785
- Studio sd.cpp: --mmap for CPU renders on builds whose --mmap keeps the CPU repack by @danielhanchen in #16758
- Studio CPU diffusion: one thread per logical CPU on small SMT hosts, for sd.cpp and torch (1.03x to 1.26x) by @danielhanchen in #16774
- Studio: int8 activations on T4 for Qwen-Image-Edit (2.03x per step) by @danielhanchen in #16813
- Studio diffusion: compiled int8 W8A8 linear on RDNA3 / RDNA4 ROCm (Qwen-Image-2.1 int8 21% faster per step on gfx1151, now ahead of bf16) by @danielhanchen in #16825
- Studio: install flash-attn's Triton AMD backend on ROCm RDNA3 / RDNA4 (10-15% faster diffusion steps on gfx1151) by @danielhanchen in #16767
- Studio video: opt-in Sol-H3-VAE decoder for MiniMax-H3 by @danielhanchen in #16747
- Studio video: decode the VAE untiled on CPU hosts when it fits in RAM (Wan2.2 VAE decode 1.5x) by @danielhanchen in #16766
- Studio: label the Chroma and Anima families in the family picker by @danielhanchen in #16809
- Parallel capabilities: follow the measured composition evidence (packed CP, Unsloth checkpoint, tiling, block swap) by @danielhanchen in #16773
- Studio tests: check family picker labels in backend CI, where families are added by @danielhanchen in #16856
- FP8 LoRA test: expect the kernel route when unsloth_zoo drops HF output flags by @danielhanchen in #16855
- CPU backend: context parallelism engages (or refuses) instead of silently running DDP; CP modules import by @danielhanchen in #16802
- Studio sd.cpp installer: retry a transient download failure before stepping down to the CPU build by @danielhanchen in #16788
- Studio sd.cpp: read the linked CUDA major from DT_NEEDED so a CUDA 13 build gets no cu12 cuDNN by @danielhanchen in #16789
- Studio bookmarks test: click Follow link again when the click does not navigate by @danielhanchen in #16858
- Studio diffusion training: no per-micro-step host syncs, one decode per cached image, streamed int8 base load by @danielhanchen in #16763
- Studio: let the floating browser go anywhere, and float per chat by @shimmyshimmer in #16859
- Studio video memory plan: count the forward's headroom before keeping whole-module offload by @danielhanchen in #16805
- Studio MiniMax-H3: price the slab compaction against the host reserve so a 16 GiB L4 render is not OOM-killed by @danielhanchen in #16849
- Studio chat UI test: drag the monitor grip again when a native resize stops early by @danielhanchen in #16861
- Studio diffusion: protect the first and last NVFP4 steps by default on sm_100-class cards (W4A16 auto) by @danielhanchen in #16759
- Studio: prompt More menu for Fork and Bookmark, and no composer scrollbar flash by @shimmyshimmer in #16866
- Mac CI: run the permission and loaded-models indicator suites alongside the UI suites by @sfjchen in #15703
- Installer mirror test: bound the probe speed by the batch time, not a fixed 1 KiB/s by @danielhanchen in #16871
- Pipeline parallel on CPU: run the chunked cross entropy on the last stage by @danielhanchen in #16846
- Studio LTX-2.5: release the server's cached GPU blocks before an encode, so later prompts stop encoding on the CPU by @danielhanchen in #16804
- Studio LTX-2.5: keep a streamed denoiser partly resident per request by @danielhanchen in #16845
- Studio diffusion: measured activations for Lumina-Image-2.0 (int8 stays resident on 16-24 GB cards, ~3% per render) by @danielhanchen in #16808
- Context parallel: give decoder layers no mask inside a CP step so block compile keeps one graph on packed rows by @danielhanchen in #16862
- Studio: name the runtime and its release in the runtime update card by @shimmyshimmer in #16880
- Studio: clear the API key when the connection type changes by @NilayYadav in #16842
- Studio: stop read aloud from waiting on a model catalog rescan by @oobabooga in #16831
- Fix slow typing in long chats on Windows by @Imagineer99 in #16656
- Pipeline parallel: refuse the MoE router aux loss over several micro-batches at Trainer init by @danielhanchen in #16822
- Context parallel: accept Unsloth's fast Qwen3 attention and compiled FastModel attention by @danielhanchen in #16870
- Studio: CI gate that fails when typing in a long chat gets slower as the chat grows by @danielhanchen in #16801
- Studio: draw nothing for the glass lens when it is Off (glass 1.4 to 2.1x faster without GPU rendering) by @oobabooga in #16852
- Studio: probe STT Transformers availability off the event loop by @danielhanchen in #16783
- Studio: round the MLX warmup and eval ratios up like transformers by @vineethsaivs in #16827
- Studio: build the video backend off the event loop in /video/status by @danielhanchen in #16792
- Studio MiniMax-H3: opt-in FlashInfer SM120 fused block kernels for FP8 and NVFP4 by @danielhanchen in #16875
- Studio: validate each dataset snapshot once per provenance attestation by @danielhanchen in #16790
- Studio: show the OpenAI thinking summary once by @NilayYadav in #16841
- Studio: keep fine-tuning jobs in order when a batch starts ahead of them by @NilayYadav in #16832
- Studio: read unread scheduled replies aloud when opened by @oobabooga in #16847
- Studio audio analyze: screen the true peak in float32 and convolve only the candidate outputs by @danielhanchen in #16794
- Studio: resume paused and interrupted model downloads on Windows by @NilayYadav in #16828
- Studio: update the NPU runtime, harden its pin updates, and polish the NPU UI by @oobabooga in #16834
- get_chat_template: apply mapping when the role key is not renamed by @vineethsaivs in #16425
- Studio: run Chroma's ComfyUI fp8 files in fp8, as ComfyUI does by @oobabooga in #16872
- Studio: let unsloth start dsh install DeepSeek Harness on Node 22 by @NilayYadav in #16844
- Legacy CLI: accept --dtype None on every backend, not only MLX by @vineethsaivs in #15775
- RL patch pass: skip the whole-module ast.parse when reading trainer class source on Python < 3.13 by @danielhanchen in #16806
- Studio: index FK child columns, partial index for the run lease sweep, keep the inventory clean on Deep Research start by @danielhanchen in #16795
- TextPreprocessor.add_structure_tokens: leave fenced code blocks alone by @vineethsaivs in #16697
- Studio RAG: batch llama-server token counts and encode the auto-inject query once by @danielhanchen in #16812
- RL class source: parse the code above a class with ast.parse, not a dynamic compile() by @danielhanchen in #16896
- install.ps1: delete the committed venv rollback in a background process by @danielhanchen in #16796
- Unsloth Studio: keep chat search fast on long histories by not shipping tool images and widget seeds to the index by @LeoBorcherding in #16848
- Studio: make the claude mcp add command work in every project by @NilayYadav in #16839
- Studio: decode the Transformers chat stream incrementally instead of re-decoding the current line per token by @danielhanchen in #16800
- Load path: read an adapter's base config through the probe memo, skip the remote mapper for unknown LoRA bases in Studio by @danielhanchen in #16793
- Studio GGUF: fuse Q8_0 dequant and cast into one kernel (LTX-2.5 Q8_0 denoise -12%, bit-identical) by @danielhanchen in #16884
- Studio chat UI test: wait for the monitor size limits before the resize, and report them by @danielhanchen in #16885
- Studio: ask before Python runs blocked shell commands via __import__ by @NilayYadav in #16840
- Studio: test that the picker keeps a Hub search tab when a local model lands by @mrityu75 in #14180
- Studio: ask to update Codex when it is too old for unsloth start codex by @NilayYadav in #16843
- Studio: limit model download speed by @NilayYadav in #16819
- Studio: start Blender MCP on mcp 2 by @danielhanchen in #16895
- Report incomplete Studio streams in the CLI by @Max-Reisinger in #16868
- Studio: make links in the collapsed update notes clickable by @NilayYadav in #16829
- Check a dataset for bad rows and over-length examples before training by @NilayYadav in #16818
- Match the Chat with files panel and Add files button to the glass theme by @Imagineer99 in #16761
- Backend tests: importorskip the unsloth submodule a test uses, not the stubbable package by @danielhanchen in #16898
- Studio: compile Anima's transformer blocks by @oobabooga in #16873
- Keep gradient checkpointing settings working on transformers 5.23 by @NilayYadav in #16833
- Studio diffusion: settle device memory once per video plan, wake sd.cpp polls on server output by @danielhanchen in #16797
- Studio Qwen-Image-2.1: fused q/k RMSNorm + RoPE and broadcast modulation for eager renders on ROCm by @danielhanchen in #16891
- Studio: reorder cloud providers in the connection picker by @shimmyshimmer in #16904
- Document browser use and sandboxing in the README by @Imagineer99 in #16903
- Studio: smaller sidebar logo on web, desktop sidebar header back to its pre-#16775 look by @shimmyshimmer in #16907
- Studio: fix the browser use bar's text size and button order by @shimmyshimmer in #16905
- Studio diffusion: overlap the quant scheme probe with the planner import on a cold image load by @danielhanchen in #16882
- Studio LTX-2.5: read the hosted int8 checkpoint as native Linears when the DiT is offloaded by @danielhanchen in #16886
- Studio: prequant fingerprint check on a thread pool, zero-copy (13x faster first load verify) by @danielhanchen in #16879
- Studio: fill the H3 conditioner's pinned arenas once, before registering (33% faster cold pin) by @danielhanchen in #16887
- Tests: undo the Unsloth load's PEFT LoRA forward swap after the probe memo tests by @danielhanchen in #16908
- Chat UI: let the floating monitor settle after the viewport restore before dragging it by @danielhanchen in #16909
- fix(studio): preserve Unicode separators in S3 JSON Lines transcripts by @Max-Reisinger in #16725
- Studio: keep fine-tuning job pages complete when a batch starts by @NilayYadav in #16823
- Studio: wait for a pending embedding model download instead of failing every linked-folder file by @debojyoti-dev in #16722
- Studio: Element outline setting, outlined light glass, Transparent glass with strength as opacity, glass Show on, and glass on pages without a background by @shimmyshimmer in #16890
- Reduce scrolling lag in long chats by bounding offscreen reply painting by @Imagineer99 in #16782
- Studio: stop dialogs and menus from restyling the whole chat on open and close by @danielhanchen in #16902
- Studio: reduce long-chat panel and scrolling lag on Linux by @wasimysaid in #16854
New Contributors- @DimitriChrysafis made their first contribution in #16592
- @sfjchen made their first contribution in #15703
- @mrityu75 made their first contribution in #14180
Full Changelog: v0.1.915-beta...v0.1916-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: